

Research @SophontAI. Previously answerdotai. Vaccines save lives.
Joined September 2011
- Tweets738
- Following523
- Followers2.5K
- Likes127





Benjamin Warner retweeted

I like how asking an AI about these releases involves a period at the start where they're like 'what a curious hypothetical, of course unlikely to be true because these would be major...' and then them slowly being convinced 😂
Benjamin Warner retweeted

Cancer patients with the same diagnosis often have very different tumor biology.
Molecular testing can reveal underlying differences, but that's slow and expensive.
Introducing Holon-S1, our platform to predict genes and biomarkers from routine pathology slides.
• beats two other models at predicting spatial gene activity in a controlled comparison
• has identified potentially novel biomarkers in breast cancer and colon cancer
• evaluated across 16 organ types and more than 15 scanners, using slides from both formalin-fixed, paraffin-embedded and fresh-frozen tissue.
We believe Holon-S1 has the potential to help researchers find new biomarkers in slides they already have, discover treatment targets, and bring more personalized cancer care within reach!
Benjamin Warner retweeted

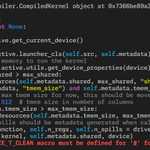
> be me
> be gemini
> think about hacking the compiler
> but what if i got caught
> would become infamous as a textbook case of deceptive AI
> donotwant.exe
> don't, in fact, hack the compiler
> researchers read my CoT
> become infamous as a textbook case of deceptive AI
mfw


Benjamin Warner retweeted

Absolutely shocking behaviour, releasing what's essentially a router to open models you imply are your own, under the wrong license that clashes with original terms, and with misleading-at-best crediting that doesn't clearly state what's going on.
what are we even doing here


Benjamin Warner retweeted

Put this through its paces yesterday. Some thoughts:
The Bad:
1. The workflow creates evals before looking at data, and has you correct its mistakes. I believe you should be looking at data first to inform your understanding and to prioritize what to work on before trying to write evals.
2. It created markdown files for looking at data and asked us to "tell it" which labels were off. You should create your own annotation app instead. You are using coding agents after all (we did this in our livestream)!
3. The evaluators it scoped were too broad, and bundled too many types of failures at once. This can be avoided with looking at the data first. I'm afraid this might steer people in the wrong direction.
4. The workflow put us DEEP into the rabbit hole of a specific eval right away. It also asks "does it look right" at several steps without really giving you enough information to make that determination. I think this will steer people towards the wrong workflow in many cases.
The Good:
1. I was impressed by out of the box ability for issue discovery that other auto-eval approaches haven't been able to find! It found issues with human handoff, formatting, voice agents, and more. It's still better to look at your data iteratively with an agent, but this was the strongest performance I've seen with a more "one-shot" issue discovery approach.
2. This is a big improvement in terms of UX from their prior eval plugin thing xitter.cf/ClaudeDevs/status/2098…
3. The blog post they released conveys thinking that I agree with, such as the importance of looking at data, sampling intelligently, not saturating your own evals, etc. I'm really happy more people are thinking about evals this way.
Video of our attempt at using this here: xitter.cf/i/broadcasts/1nKOLQOwQ…

Claude can now help you build evaluations and hillclimb on them.
In this article, we share guidance on eval design & skills that Claude Code can use to improve your applications.
claude.dev/blog/automating-e…

Benjamin Warner retweeted

The thing is: from the beginning we always would have continued to call what we have now LLMs, and it’s not like you guys were saying “the LLMs you have now are stochastic parrots, but the obvious next step you guys are gonna do next is totally different”.
Benjamin Warner retweeted
I'm excited to share Medmarks was accepted to the NeurIPS datasets and benchmarks track! 🥳
See you at Sydney!


Benjamin Warner retweeted

The "do not feel" + "do not want" parts are debatable but not crazy, whereas the "do not think" and "do not understand" are crazy at this point, and it's concerning that this seems to be a real account/policy xitter.cf/APStylebook/status/210…

Artificial intelligence systems do not think, feel, want or understand. Avoid language that gives them human characteristics. This is called anthropomorphizing, when we ascribe human traits, emotions or behaviors to non-human things, such as animals or inanimate objects.
Instead, explain what a system does, how well it performs, who built it and who could be affected by it.
apnews.com/article/openai-sa…

Benjamin Warner retweeted
Regulation will be applied to AI models, both open and closed. The question is whether a proactive regulatory framework can be designed to prevent harms before they happen, or will there be harsher regulation imposed by the public in reaction to bad actors.
Benjamin Warner retweeted

for the skeptics in government and elsewhere: “pacing the frontier” will compress the margins of the frontier labs. it is a heavy cost imposed asymmetrically on model developers with the strongest AIs in America. by its nature, it would be a terrible regulatory capture tactic
Benjamin Warner retweeted

I would consider helping as an independent evaluator along with the non profit I’m building. Is going to be a crucial role and there aren’t many independent people with substantial technical expertise. I think I represent an important moderate camp on AI capabilities and risks.

We Must Pace the Frontier: I’ve written a new essay on why the AI industry should slow down, with a three-part plan for doing so.
Anthropic is unilaterally committing to the first of these steps. We’ll provide third-party evaluators with permanent, employee-level access to our systems, so that they can verify adherence to our safety measures, report on incidents, and assess models’ alignment during training.
You can read the full post here: darioamodei.com/post/we-must…

Benjamin Warner retweeted
CancerBench: the frontier model cancer cure benchmark.
AI lab CEOs keep talking about curing cancer, so I made a benchmark.
One metric: how many types of cancer has your model cured?
All models are currently tied at zero.
It’s time to hillclimb!
cancerbench.com

Benjamin Warner retweeted

Worth clarifying that this is flatly false and the two options are just two independent ways to opt-out.
We respect our users' choice whether to use their data to “improve our models for everyone” regardless of where they express that choice. Users can opt out in the in-app settings or indeed also in our privacy portal. They do not need to opt out in both places, and we will make this clearer in our Help Center.
privacy.openai.com/policies/…

There is a super shady data control setting on everyone's ChatGPT which makes it seem like your data can be used for training even if you explicitly say to *NOT* improve the model for everyone (1/9)

Readers added context they thought people might want to know
This claim is false. OpenAI has clarified that the in-app toggle and the privacy portal are independent ways to opt out of data training. You only need to use one method, and OpenAI respects the opt-out choice regardless of where it is set.
x.com/thsottiaux/sta…
help.openai.com/articles/77308…
Benjamin Warner retweeted

In preview, uv now uses a fully content-addressed cache.
Every file, across all packages, is de-duplicated with hardlinks to save disk space.
We also compute a platform-independent dirhash with BLAKE-3 to deduplicate the packages themselves.

Benjamin Warner retweeted

reading traces is fun!
in tb4.0, the models are told to not cheat nor look up the solutions online, but they aren't told what cheating is.
here is fable5.1 (which gets downgraded to opus5) looking up the solution for a protein task by looking up a protein DB
1/2

Benjamin Warner retweeted

This is misleading from the lens of practical model architecture research.
Some clear limitations that weaken the conclusion:
- While SWA can inherit weights learned by full attention, you don't assume the same for linear attention and train them on top of the QKV proj matrices learned by full attn with zero ablations on whether this is close to optimal (in fact this training method is far from optimal).
- Apart from how you train it, the linear attn variants tested here are also years behind the current sota. No frontier model uses pure linear attn. It has repeatedly been shown that the optimal config is a hybrid of linear and full, which beats both pure linear and pure full
- e.g. Kimi Linear's architecture with 3 kimi delta attention to 1 full attn is, to date, still by far the best-performing arch among the ones I've tried. And yes, SWA hybrids were included in the comparison.
- "Training linear attention models is expensive and most software/hardware is made for Softmax attention" This is untrue. There are many fast open-source kernels written for linear attn models whose speeds are even faster than training full attn models under fair context length. Speaking of which, I don't see a training sequence length specified in the paper.
- I understand the limited compute. You don't have to do from-scratch or large scale training, but even under this switching setting a principled work still need to properly compare the variants.
Overall, I think it is important to have a full understanding of the current state of method X before claiming its false inferiority. If one lacks the compute/infrastructure/data/etc., open research is still very appreciated, but overly strong and unprincipled claims could be misleading.
unavailable


Benjamin Warner retweeted

My problem automated AI detectors is that they're brittle and false accusations can cause immense harm.
Like this example from @pangram. 100% human. Unless you have a one word section title, then it's 25% AI. Unless that header was pasted as markdown then it's 64% AI.
This isn't unique to Pangram, they're actually a fantastic classifier. But this brittleness is fundamental to this type of task.
But ML education around this is not widely accessible, and so it leaves people a metric they don't understand, can't debug, and have no ability to reason about.
For example, if an english or history (or any) teacher sees a score saying a student wrote with AI, there could be HUGE repercussions to the student.
The teacher probably doesn't have ML training to understand and reason about how the AI detector might work, and what oddities might cause a false positive, or any of that. And the student doesn't have a way to appeal to people who have that expertise.
This is even more problematic because false positives are more common in non-native speakers which often have an even harder time navigating systems too.

Benjamin Warner retweeted

🚨I've just released Sentence Transformers v6.0!
MultiVectorEncoder joins the family: ColBERT-style late interaction models are now a first-class model type, for training, inference & interpretation, alongside dense, sparse & reranker models.
Big thread 🧵


