

Applied AI & research | models, agents & cybersec | still stacking sats
Won’t trap me
Joined November 2013
- Tweets51.6K
- Following1.3K
- Followers2.9K
- Likes222K




Bitduke retweeted

You might wonder whether the models had simply seen these old papers before. They have been public since 2004.
So we inserted the same errors into 58 trials published in 2026, incl all eligible open-access phase 3 trials from July to October. Detection was 58-99%, and 838 of 840 AI reviews still beat the human average.

Bitduke retweeted
In our study, we reran a classic peer review experiment. Researchers had inserted 9 major and 5 minor errors into reports of randomized clinical trials and sent them to 607 reviewers. Reviewers without training found 27% of the major errors, and training barely helped.
We gave the same papers to 15 LLMs. They found 53-96%. Even the smallest models found about twice as many major errors as human reviewers.

Bitduke retweeted
I fully agree with @anshulkundaje, @PracheeAC and @arjunrajlab. The median human review leaves a lot to be desired. @lh3lh3 thinks journals are right to ban AI-generated reviews, and some people rate AI reviews below human review. Our data point the other way. I also like Prachee's point that review at a single snapshot in time will become outdated once readers can run these checks themselves.

Bitduke retweeted

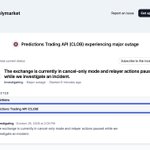
BREAKING: @Polymarket HALTS TRADING, PUTTING THE EXCHANGE IN "CANCEL-ONLY MODE" AND PAUSING RELAYER ACTIONS "WHILE WE INVESTIGATE AN INCIDENT"
THE OFFICIAL STATUS PAGE LISTS A MAJOR OUTAGE AS OF 18:05 UTC
IT COMES AS SEVERAL USERS REPORT ACCOUNTS BEING DRAINED
SOURCE: status.polymarket.com/cmvtus…

Bitduke retweeted

UPDATE FROM POLYMARKET RELATED TO THE DRAIN GOING ON.
"The exchange is currently in cancel-only mode and relayer actions paused while we investigate this incident, the team is all hands on right now working on this. We will update you all as soon as possible."

This quoted post is unavailable.
Bitduke retweeted

I was going to post some new sama quotes from this interview this morning, but prinz already posted a great summary. I will add that this is the third time I've seen Mr Altman talk about self replicating OpenAI datacenters. The first use case for OpenAI robots appears to be building more OpenAI robots and building more OpenAI datacenters. Mr A also wrote specifically about this on his blog a couple of years ago.
'Yeah, people talk a lot about RSI as AI that does AI research. There's very little talk about self-replicating data centers, this idea that you can use AI to control robots and run fabs and build turbines or solar panels and build data centers. But I think we have that within grasp.'

Sam Altman on automation of AI R&D, RSI, OpenAI's internal model:
1. "We don't know yet how [automated AI R&D] truly is going to work. We know today how to say: find me a 5% compute efficiency win."
(Note: a 5% compute efficiency gain that the model can find automatically is actually a big deal!)
2. "What I don't think anyone knows how to do yet is to say, go discover a new architecture that is as big of a single leap forward as the transformer was. And I think that's where things are heading."
3. "If you apply the same pipeline that we applied to get our models to be so good at math to AI research, it will probably work [for automated AI R&D]."
4. The bottleneck to getting good AI R&D results is shifting to asking the right questions and using things like swarms correctly, but answers to these questions will become much clearer in the next 3 months:
"One of the interesting things that people talk a lot about in OpenAI... is what are the questions that you're supposed to ask of GPT-7? Probably it's not enough to just say, make me RSI. And also, it's probably not enough to say, buy me a 5% compute efficiency win. I think this is one of the most interesting debates going on right now. And the answer is not just what question to ask it, but it's things like agent swarms. How are we going to use these models in a way that, like, actually maximizes what we can get out of them? I think we're going to learn a lot about that in the next 3 months."
5. OpenAI's extreme focus on model efficiency:
"I bet we could redo Navier-Stokes at 1/100 of the cost a year from when it was done."
6. More on OpenAI's internal model:
"There was one weekend when we got a new model... The name of the channel was "model-name-hold-my-beer". And people were just throwing that at the hardest problems they could. And people just didn't think the model was going to do these things. And we had this collective experience of people's hardest research problems from their academic career, the model was just knocking down one after the other, many different fields, it was incredible to watch... it was many of the problems we published, many other things."
7. The other loop is self-replicating data centers:
"Yeah, people talk a lot about RSI as AI that does AI research. There's very little talk about self-replicating data centers, this idea that you can use AI to control robots and run fabs and build turbines or solar panels and build data centers. But I think we have that within grasp."
Bitduke retweeted

on security tasks, my gut feeling is still glm 5.3f > glm 5.3 > deepseek 4.1f 1017 > gpt 5.6 sol blue. folks are overhyping deepseek.
Bitduke retweeted
OpenRouter served 5.2T tokens yesterday. We did ~1.8T (1/3 of their volume) on just 64x B300 and 64x M890P. Where do all GPUs go? 😂😂😂


Bitduke retweeted

the 30 days of codex updates has felt like a huge larp unfortunately. but i believe in them for the next model lap!
Bitduke retweeted

Meet NVIDIA Nemotron 3.5 Transcribe 🎙️
An open-weight, promptable 30B MoE model with ~4B active parameters that brings transcription in 40 languages, speaker attribution, translation, contextual prompting and audio understanding into one checkpoint.
Watch it keep track of who said what when everyone’s talking at once.
1/ 🧵
Bitduke retweeted

Team is working on this but it's not rolling out just yet, sorry for any confusion. Plan is to bring together best of both Chat / Work capabilities together at some point this year, but we're going to proceed carefully here and take our time.
We'll have more to share soon.


Bitduke retweeted

The thing is: the current change is SO fast that those who are waiting / hoping for directions on how to use AI efficiently for your work: it could come too late.
Team dynamics are also shifting very quickly: tenure no longer correlates doing better (faster / higher quality) work necessarily!
Bitduke retweeted
It’s hard to see anything else happening but coding interviews going away.
This won’t mean that technical ability won’t be interviewed: but it interviews will be less predictable, more subjective and harder to prep for than the near-universally-disliked DSA interviews.

The coding interview is dead, at least for my team at Anthropic. I've seen enough to know that it no longer provides signal. I removed it from loops this month.
I have a spicy, optimistic take - I think there's an opportunity for junior engineers: felixrieseberg.com/hunger-be…




Bitduke retweeted

JUST IN: Solana $SOL co-founder Anatoly Yakovenko says US companies opposing tokenized stock trading "should go private then."
Bitduke retweeted

I did say we'd be releasing our models periodically...introducing Gemini 4 Carbon, our next frontier model.
Following Argon's release just two weeks ago, Carbon shows the pace at which we’re pushing the frontier, it ranks #1 on the recently updated v5.0 of @ArtificialAnlys Intelligence Index at 59. It also leads across key cybersecurity evaluations scoring 88.2% on SEC-bench Pro for finding vulnerabilities, 54.8% on ExploitGym for exploitation, and 71.0% on CWE-bench for patching.
We’re seeing significant improvements in long-horizon tasks even compared to Argon, and we’ve strengthened frontier safeguards.
As we did with Argon, we’re going to roll it out gradually + responsibly. Some trusted cyber defenders will get access starting this week. We'll be expanding it to more partners through our Fairwind Program, ahead of wider availability soon, so hang tight!

Bitduke retweeted
BREAKING: @Google PREVIEWS "GOOGLE MULTI-PARTY COMPUTE" - A CRYPTO CUSTODY AND SIGNING SERVICE FOR BANKS, WHICH ALPHABET ALREADY USES TO SECURE ITS OWN ASSETS ON ETHEREUM AND SOLANA
SOURCE: coindesk.com/tech/2026/10/28…

Bitduke retweeted

another brutal reality check for the open-sauce china shills
GPT-5.5 released on April 23 outscores all tested chinese models
and OpenAI and Anthropic have been holding back their strongest models since the supply chain risk designation, so we aren't even seeing the full extent of the domination


the top 20 models on FrontierCode 2
it's actually hilarious
it's all OpenAI and Anthropic + Grok 4.7 xhigh at #20
DeepSeek V4.1 Flash 1017 max is rank 52
but yeah totally, china is catching up and we are all doomed

Bitduke retweeted

Coinbase has not had a data breach.
Amplitude, an analytics vendor, experienced a security incident which impacted a small subset of Coinbase customer contact data, among other Amplitude customers.
We’ve found no evidence of unauthorized access to Coinbase systems, and customer funds were not impacted.
We are notifying impacted customers and regulatory agencies in accordance with our legal obligations.