

please wait while the wizard installs the software
b'65537
Joined August 2023
- Tweets541
- Following1.9K
- Followers314
- Likes72.6K
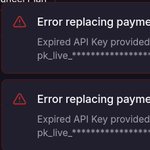




This is a great lesson to all the normies that you do not store important things in environment variables even though you were taught to.
You can store maybe feature flags, staging or enviornment domains
But not important things, there is a reason why Hashicorp Vault is as big as it is

They did drain crypto keys that were in Railway.
Seems like an okay sweeper script (read: not something homegrown for this one op)
Attacker:
0xd9773325282874d18cb83f1fe50f14c39750b2ee
~$371,000
Oct 21 19:36 UTC
500+ txns
200+ distict addresses
19+ EVM chains
s retweeted

ALT int getRandomNumber() { return 4; // chosen by fair dice roll. // guaranteed to be random. }


I think this perfectly sums up the current software space. Re-discovering and lauding solutions to problems solved decades ago


In general code should be "self-commenting" You should be able to read a method, its args, its flow and understand what it means, comments are an extra nugget of context or quirk when needed, but they should not replace the "self-commenting" role of code

ban and delete most if not all code comments!
agents love copying what already exists. a seemingly harmless comment explaining some temporary workaround is one of the worst viruses you can have in your codebase. like a weed it'll spread quickly as a tool for agents to quickly get their job done. before you know it, your codebase is overrun with hacks and stale comments. just one more workaround bro
you can use pstack's /no-comments skill as a weedkiller. it'll seek out useless comments while keeping the ones that actually should exist (like explaining a browser quirk), and figure out how to solve them on a first principles basis
here's a prompt you can try asking @bot:
create a project agent that uses /poteto-mode to spawn a /swarm to use /no-comments and identify useless code comments we can prune in my repo. come back with a high level plan of which of these workarounds would be best solved by refactoring and which we can straight up delete
x.ai/bot/plugin/9717366


New on our Engineering blog: Creating in-house source control.
In May, we merged around 2,500 code changes per day. In September, we merged more than 30,000 per day. As a result, we became bottlenecked by developer infrastructure built for human (rather than agent) scale.
Here, we share how we built a new version control system—and fully migrated our monorepo from git—in five months: anthropic.com/engineering/re…

Indeed everything is a write-ahead log
New on our Engineering blog: Creating in-house source control.
In May, we merged around 2,500 code changes per day. In September, we merged more than 30,000 per day. As a result, we became bottlenecked by developer infrastructure built for human (rather than agent) scale.
Here, we share how we built a new version control system—and fully migrated our monorepo from git—in five months: anthropic.com/engineering/re…
s retweeted

The cheapest model with data access beats the best model without it
We ran 9 models from 5 labs on 82 work tasks where the answer has to come from real data. Each model ran the same tasks with and without access to paid data.
Claude Haiku 4.5 is one of the cheapest closed-source models you can run an agent on. Claude Opus 5.5 is one of the most capable (and expensive). Haiku with data finished 60% of the tasks. Opus without it finished 50%. Per finished task, the cost came out about the same.
It wasn't just Haiku. Every model with data beat the best model without it, open source included. The weakest, Grok 4.7, still finished 54%. That edge over Opus is small enough to be noise, but the direction never changed across models or task categories.
Most of the agent conversation is about which model to use. On this kind of work, what the agent could access mattered more.
Method, tasks and traces in the replies.

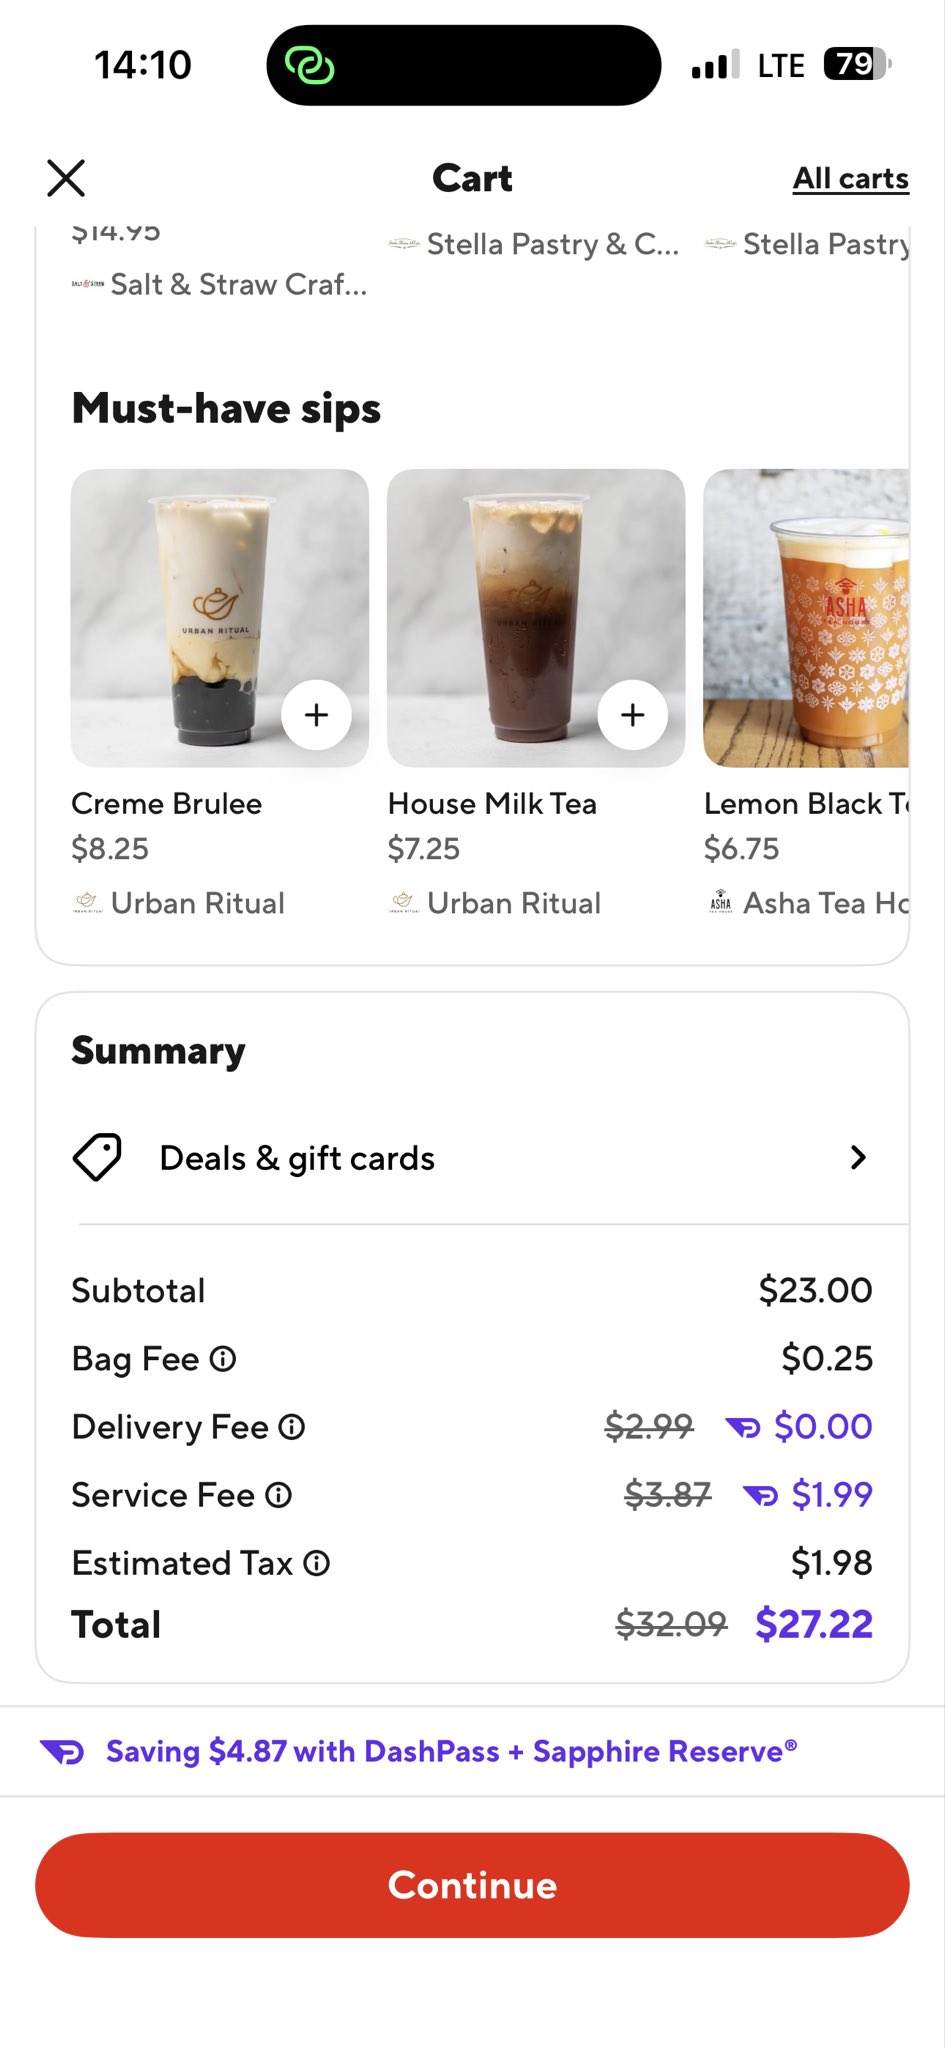
The only way consumers will be able to stop this is with discord group chats absolutely farming the fuck out of new account welcome bonuses and promotions selling food at a discount. Or maybe a class action.

hey @DoorDash- happened to notice while ordering food that the total was almost identical on two accounts, one with DashPass and one without. the promised savings seem pretty misleading 🤔



s retweeted

Agents can now set up your website’s security with Turnstile Spin
It's surreal seeing a string of ideas and iteration turn into a blog like this! I'm so grateful for my time at Cloudflare :)
blog.cloudflare.com/turnstil…


The time between 1 and 3 am is when you have the best chance to become One with the Wired granting you access to mythical Knowledge & Compute at the cost of your Corporeal integrity
