

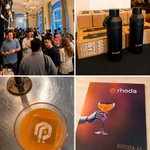




Thanks to everyone who joined us at the party last night! It was a lot of fun, and I hope everyone had a great time!

Thank you to everyone who joined our Video Models Meet Robotics reception at #CoRL2026 last night 🍸
200+ came through Swift’s Attic, and the conversations kept going on the sidewalk well after we closed!
Great meeting so many of you in Austin 🤖


I'll be at CoRL on 11/10 and 11/11. Happy to grab a coffee if you are interested in joining or want to know more about what we are building!
Rhoda will be at #CoRL2026 in Austin 🤖
🍸 Tue Nov 10, 6:30–8:30 PM: Video Models Meet Robotics reception at Swift's Attic. Invite-only, request a spot: luma.com/e8ucuj9c
🎤 Thu Nov 12, 11:25 AM: Vincent Sitzmann @vincesitzmann speaks at the "Do Robots Need World Models?" workshop
do-robots-need-world-models.…

5
27
1,111
Our DVA just went mobile!
Pretraining on internet-scale videos gives DVA strong priors about the physical world, enabling it to learn new mobile manipulation tasks with as little as 15 minutes of robot data.
Huge shoutout to @joannetruong for making this happen!
We taught a robot how to move around in only 15 minutes.
That’s all the mobility data our Direct Video-Action-powered robot needed to accomplish a task that requires mobility and manipulation.
3
15
1,055
Giving robots a sense of touch! Really cool results from teaching robots to interact with the world through tactile feedback, even when blindfolded.
Huge shoutout to the team for driving this work! @AndrewEJXie @leooeld @DaveLindell
More details: rhoda.ai/research/giving-rob…

What can a robot do without vision?
We gave our robot a sense of touch and showed it can recognize and retrieve objects with its cameras blindfolded.
Introducing Rhoda’s new tactile sensor—it feels pressure, texture, vibration, slip, and temperature, just like your fingertips.
2
27
1,401

Changan Chen retweeted
More industries. More real customer work.
Introducing RhodaAtWork, a series on the customer workflows our robots are learning to handle across manufacturing and logistics.
First up: unpacking, scanning and stacking component reels for electronics manufacturing.
Changan Chen retweeted
At Rhoda, we care deeply about the science of pre-training for robotics.
In one of the most rigorous studies of its kind, over thousands of trials and hundreds of hours of robot evaluations, we show how scaling web-video pre-training leads to better real-world robot performance.
At @RhodaAI, we study the science of pre-training for robotics. Great work led by @tongzhou_mu showing the scaling laws of web-scale pre-training and how they translate into better policy performance on real-world industrial tasks!

Does scaling pre-training on general web video improve a complex manipulation task in real deployment?
We scale model size and pre-training compute, and test on one industrial task.
Yes. The better a pre-trained model predicts web video, the better its post-trained policy. 🧵

ALT Seven pre-trained video-model checkpoints on one chart. Task performance on a real robot (at-speed completion rate: every requirement met within 100 s, 0 to 100%) rises with pre-training quality (DINO FD on held-out web video, log scale, axis reversed so better is to the right). XS, S, M, L are model sizes. The four M points are one model at 0.08×, 0.18×, 0.37× and 1× of its pre-training compute.

Changan Chen retweeted

I am thrilled to join rhoda.ai @RhodaAI as an advisor, where I am helping harness the abilities of large-scale pre-training and video models for robotics, putting many of my lab's research learnings of the past few years into practice! I will be in-person at the Mountain View office for part of the summer - reach out if you want to chat :)
One theme came up over and over in the past few days: excitement around world models for robotics. 🤖
The interest from the research community has been incredible. It feels like we’re entering a new phase for physical AI by approaching it with real time video models!
1
3
1,538
Huge shoutout to the Rhoda team for making the event happen! 🙌
If you’re at @CVPR, come say hi:
@ericryanchan @alexwbergman @isskoro @leooeld @QianqianWang5 @GordonWetzstein @vincesitzmann @BaadeAlan
We’re hiring! 🚀
Careers: rhoda.ai/careers


I’ve known Yuejiang and worked with him for many years. He’s always curious, humble, and eager to learn new things.
He's not only a fantastic researcher but also one of the best mentors I've worked with.
If you're pursuing a PhD in embodied AI, consider applying to his lab!

Excited to share that I’ll join @NUSComputing as an Assistant Professor in 2027
🏛️ I’ll build LEMA Lab: lema-nus.github.io, study the principles of embodied intelligence, & empower every lab member to thrive
📢 Recruiting 3-6 PhD students in the next application cycles

1
10
3,043
I'll be at CVPR next week (6/3–6/7). If you’re working on or exploring opportunities in video models for robotics (research or engineering), happy to chat 🤖
We’re also hosting a Rhoda party Thursday night with many of our technical team in town. DM me for an invite 🍻
We’re hiring across research and engineering 🚀
Open roles:
• video model pre-training
• robot post-training
• ml infrastructure
• deployment
• phd internships
Careers: rhoda.ai/careers

2
8
1,536
We got our large-scale foundational video model running real-time on an edge device! Amazing work led by @leooeld!
Amazing work on long-context video memory and reasoning led by @QianqianWang5!
We are entering a new era of robot deployment.
With our model, teams can iterate on solutions and data collection more rapidly thanks to highly efficient training. What once took months can now be achieved in as little as 19 days, bringing development to an entirely new pace.
1/ We are speed running industrial robotics.
It took us just 19 days from the first day of data collection to filming a 2.5-hour continuous run of our model autonomously breaking down industrial containers — zero human intervention.
The data efficiency of our DVA model is fundamentally changing how fast we bring robots out of the lab and into the factory.
Autonomous operation with 3 hours of data collection at a customer factory.
Over the past year and a half, I’ve spoken with many robot learning researchers, and a recurring concern is how to achieve a 99.99% success rate. Many video demos showcase a single flawless run, but that doesn’t address the long-tail challenges of real-world tasks, where countless corner cases arise. What we’ve observed with video models is that, once sufficiently powerful and pre-trained, they can capture multi-modal distributions effectively. In practice, this means the model can learn diverse behaviors for handling edge cases without requiring hundreds of hours of video data.
Most robot demos are “golden runs”: a perfect take selected from many attempts.
But real-world deployment is about Continuous Operation.
Watch our DVA model tackle a real-world decanting task for 1.5 hours straight: Uncut, Zero human intervention.
🧵👇
4
865