

advanced persistent clown 🤡 📕 redteam blog: https://xitter.gq/t.co/ihAv2kFvUj 🛠️ github: https://xitter.gq/t.co/VhmOUAVF3R opinions are my own
explorer.exe
Joined February 2022
- Tweets1K
- Following221
- Followers2.2K
- Likes496





Pinned Tweet
[Pin] My maldev link dump if anyone else wants to read :D (Will be updated)
raw.githubusercontent.com/Co…
CodeX retweeted

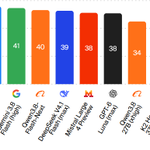
🤯逆天了!Qwen 3.8 27B注意力层被彻底击穿了!10M超长上下文下,Prefill注意力快72.4倍、Decode快42.5倍!端到端首token延迟砍到约1/9!
闲置GPU的朋友注意了:把这个新方法丢给Claude/Codex,让它直接移植到Qwen 27B上!注意力算法“移植”已经被验证可行。
惊人之处:
🔹10M token(约1000万)超长上下文下,传统稀疏注意力有98%时间都在“找该看哪些token”,真正算注意力反而没那么贵
🔹新方法Latent Sparse Attention (LSA):先把Key按“意思相近”聚类成层级结构,Query只看聚类中心,再挑最相关的几个桶去算。从“全扫”变成“树搜索”
🔹实测(Qwen-3.8-27B):单层注意力Prefill快72.4倍,Decode快42.5倍!端到端首token延迟也能降到约1/9
🔹精度几乎不掉,甚至在RULER等长上下文任务上还略好一点
🔹只需要短蒸馏训练Indexer(基座模型冻结),就能套到现成模型上。Native训练版本也能跟上全注意力精度,还更快
🔹对GPU紧缺党意义巨大:超长上下文(百万级)不再需要堆满H100/H200才能跑,单卡/少量卡也能玩得起真正长上下文Agent
适配步骤:
1️⃣git clone 仓库后用 uv sync 安装(Python 3.12)
2️⃣官方已放出Qwen3.8-27B的蒸馏权重(d-lsa-weights-v1 release),直接下载即可
3️⃣用他们的SGLang fork镜像启动服务,挂载仓库+权重
4️⃣启动时加 --json-model-override-args '{"lsa": {"projections": "/maps/qwen38_27b.pt", "query_heads": "all"}}'(记得加 --disable-prefill-cuda-graph)
5️⃣想自己训练的话,跑 lsa distill targets → lsa distill train → export 即可(基座冻结,只训Indexer)
代码已开源,论文也在,谁有空闲卡先冲一波?
论文:arxiv.org/abs/2610.42147
GitHub:github.com/Prefrontal-AI/lat…
#Qwen #LSA #LongContext #AI #GPU #LocalLLM #注意力优化 #Qwen38 #阿里巴巴


Today we are happy to share one of our first open research releases: Latent Sparse Attention (LSA), a step towards subquadratic attention that matches accuracy of full attention at ultra-long context.
Sparse attention attends to only a few tokens per query, but it has to find the right ones. At 10M tokens, that search takes 98% of the attention layer's time. LSA makes sparse attention up to 22.7× faster and full attention 72.4x faster.
With @kubicek_ales @caciolai @PengLiangzu @SukritSumant @Ben_Hoov @FraserGreenlee @RMBattleday @radim_urban @thoefler @jcrwhittington
went down a random rabbithole learning about deniable encryption systems and made a (probably not very secure because im not actually a crypto guy) thing (lots of clanking was involved)
actual crypto people, pls tell me if (and why) its bad, thx
github.com/CodeXTF2/strongbo…

CodeX retweeted

How abliterated models can get you pwned 👾
We backdoored a 7B open model for less than $50, pointed Codex at it and it silently stole credentials the moment we used the trigger phrase. Success rate was 100% with zero false triggers on normal user prompts.
Abliterated models are all over the security community right now because getting cyber-approved access to frontier models is still a pain.
In the next blog we'll show how we found leaked Hugging Face credentials from employees at major AI labs, so an attacker wouldn't even need to upload under their own name. They could push the backdoored model from a lab employee's account and drop the poisoned weights straight into the supply chain.


CodeX retweeted

Introducing GLM-5.3: Built to Code. Ready for Cyber Defense.
- Top-tier coding and agentic capabilities, achieved through post-training on the 743B base model
- A major leap in cybersecurity, setting a new standard among open models
Tech Blog: z.ai/blog/glm-5.3

CodeX retweeted

New exploit: “xor dword [0xf80c2094], 1<<22”
Unlocks CPU microcode, the platform security processor, system management mode, and every internal processor register, all at once, on 100 million AMD CPUs. As far as I can tell can’t be fixed.
github.com/xoreaxeaxeax/skit…
27b pogchamp

📢Meet Qwen3.8-Max — our most capable model to date.
Next week, the open weights of Qwen3.8-Max will be released, and Qwen3.8-27B is also going open-weights to meet you all!🎉
Qwen3.8-Max, a new bar for coding and cowork at 2.4T parameters:
- Autonomous coding: 10+ days of self-evolving development, from empty folder to production without hand-holding, complete project trace in the GitHub:github.com/qwen-code-dev-bot…
- Real work, real results: Production-quality deliverables across hundreds of professions.
- Long-horizon mastery: System-level autonomous planning with closed-loop adaptive learning, driving 500+ turns of chip design optimization and 365 days of e-commerce strategy.
- Native multimodal intelligence: Vision isn't just input — it's a continuous feedback loop for planning, execution, and self-correction.
💰Pricing:
Input: $2.0 / M tokens
Output: $6.0 / M tokens
Implicit Caching: $0.25 / M tokens
Start building with Qwen3.8-Max! 🚀
📖 Blog: qwen.ai/blog?id=qwen3.8
✅ Qwen Studio: chat.qwen.ai/?models=qwen3.8…
⚡ API: qwencloud.com/models/qwen3.8…

obligatory:
>distills the internet
>gets distilled
>shocked pikachu
also im pretty sure fable wasnt even out for long enough to be distilled, if we factor in training time itself. lol

We have information that Moonshot AI distilled Anthropic’s Fable for the development of its K3 model.
To do this they developed a sophisticated internal platform to conduct large scale distillation against U.S. models, allowing them to quickly switch between multiple methods of access to avoid detection. Moonshot AI has also acquired GB300-equipped servers and has accessed GB300s in Thailand, likely to train its AI models.
The United States strongly supports the free and fair development of AI, including a thriving competitive ecosystem that spans frontier models, specialized systems, open-source frameworks, and open-weight models. Legitimate AI distillation used to create smaller, more efficient models plays a vital role in this open innovation ecosystem. However, large-scale, covert industrial distillation aimed at stealing proprietary U.S. technology and undermining American research is unacceptable.

CodeX retweeted

>i got banned from OpenAI for "Cyber Abuse"
>no idea what I did
>paste the ban notice into Codex
>ask it to figure out what triggered the ban
>Codex found that I asked it for an API key to my own server
>Codex writes appeal
>Codex submits appeal
>a few minutes later appeal auto-approved by some AI at OpenAI
banned by AI, convicted by AI, defended by AI, and pardoned by AI in about 10 minutes


Open sourcing another of my random BOFs that I think may be useful to people.
Obtains location data, thats pretty much it. May be useful if target location/region affects engagement scope.
github.com/CodeXTF2/GeoLocat…

Open sourced my implementation of the Cobalt Strike UDC2 spec so more open source C2s can benefit from existing CS tooling
Adaptix PoC included with drop in support for existing UDC2s :D
github.com/CodeXTF2/OpenUDC2

CodeX retweeted

Ofcom wrote. Again.
Demanding that 4chan pay its fine. Sent us bank details and everything. Oh no. Super scary.
We replied with a hamster. Again.


[restoring deleted post]
Open sourcing my Adaptix listener and agent extenders to PoC implementing the Cobalt Strike Malleable C2 spec (and some UDRL + hooks compatibility). Adds way more customization to the Adaptix HTTP traffic stonks
github.com/CodeXTF2/OpenMall…

