

Product Manager & AI Engineer working on Gen AI & ML. Opinions are my own, not my employer's. RT !=endorsement
Seattle, WA
Joined November 2021
- Tweets28.9K
- Following7.5K
- Followers4.1K
- Likes112K






iamrobotbear (bk) retweeted

I wanted to test Fable 5.2 on something that felt impossible for me to code: complex behaviours for a creature.
The starting point: a Three.js prototype. A little robotic biped living its own life, animated entirely by code. A lot of movement research went into it: getting it to walk, then run, then gallop without falling over, feet that actually plant on the ground, a head and neck that go looking for things, simulating hundreds of lives to see where it trips and fixing that. Alongside, a few reference sketches and visual research.
Then I decided to try it in Unreal 5.8 and to make it controllable.
No pre-recorded animation; everything is computed. All done in 2 days. Sound design is bad and world a bit random.
The video is me playing around with my PS5 controller.
iamrobotbear (bk) retweeted

Compound Engineering 3.38 is out!
A big new addition is `/ce-retro`. It reads your past agent sessions and proposes a handful of fixes for how your agents work in your repo to avoid problems and papercuts, which can add time and lead to a lot of token waste. Try it with `/ce-retro last 7 days` for example and let it cook to propose improvements.
Also in this release:
- Cheaper runs. `/ce-work` hands fully specified steps to a cheaper model, loads ~30% fewer tokens, and small changes get one reviewer instead of four
- `/ce-plan` defaults to one PR. A previous change I made made it overzealous with too many PRs lead to too many wasted review and CI cycles.
- `/ce-debug` hard stops instead of pushing a fix without reporting back
- Pi is supported as a cross-model peer in code and doc reviews
iamrobotbear (bk) retweeted

DSPy is now 85% smaller!
We just released DSPy 3.5 which makes DSPy lighter, faster, and a more reliable experience out of the box.

iamrobotbear (bk) retweeted
I CANNOT believe the report: it proves that eMudhra is a clown show, and was never fit to be a CA:
The point of a HSM (hardware security module) is that the private key NEVER leaves it. Guess what eMudhra did: it turned off FIPS mode (WTF?!) and copied out the private key 😱

eMudhra's incident report is out! A Python script truncated their CA private keys to one byte?!
bugzilla.mozilla.org/show_bu…
iamrobotbear (bk) retweeted

Even the simplest weight edit, a deletion, can teach an LLM new skills!
Meet Deletion Tuning (#NeurIPS2026): just zeroing <0.1% of weights matches full fine-tuning's accuracy at scale. It's thousands of times smaller and avoids forgetting, a step toward continual learning. 🧵👇
iamrobotbear (bk) retweeted

I asked fable 5.2 to invent a new musical form.
Fable 5.2 wrote a symphony that’s shaped like a training run.
The orchestra starts as random noise, learns the key, pulse, harmony and the melody, then plays music it was never shown.
iamrobotbear (bk) retweeted

Introducing Claude Fable 5.2 and Claude Mythos 5.2, designed to tackle the most daunting technical challenges.
They’re capable collaborators on ambitious projects in many fields, and show improvements in areas like coding, reasoning, and vision.
iamrobotbear (bk) retweeted

Today we're announcing Atomarine's $19M seed round!
We are supported by great investors including @ycombinator, @PanteraCapital, @Soma_Capital , @sevensevensix, @Liquid2V, @AudaciousHQ, @e14fund, and many others.
@Atomarine_co is solving the main constraint to AI today: physical buildout. Our floating data centers powered by nuclear, are designed to be built on a single production line, and anchored offshore.
By moving offshore, we do not compete with communities for water, power or land, and we do not drive up their electricity bills or rent. This allows America to stay competitive in the AI race without putting the burden on local communities, while fighting climate change by scaling AI on nuclear instead of fossil fuels.
We have already built a functional proof of concept and we are now racing towards our next big milestone.
If you are a very talented engineer in naval architecture, nuclear or data center design, or just love to work at world-changing, fast-paced companies, reach out. We are hiring!
iamrobotbear (bk) retweeted

"data centers … were responsible for just 4 percent of the [electricity] utility rate increases over the last five years"


iamrobotbear (bk) retweeted

i went to bed and asked claude to paint an autumn tree overnight.
at around 4am, it realised that it didn't have some shades -- so it stopped and titrated its own paint: diluting red, sienna and madder step by step on a second palette, then measuring each pocket from a photo.
woke up to this beautiful watercolor painting. 303 brush marks, took about 4.5 hours 🍂 (still working on the speed)
iamrobotbear (bk) retweeted

Introducing Higgsfield Miracle.
Our latest proprietary post-production technology vectorizes any video into layers for localized, pixel-level editing in real time, with world knowledge built in. Every frame holds the image depth needed for cinema-grade post-production.
Now in private beta with select testers. Coming soon to Higgsfield MCP.
Set up Higgsfield MCP in Claude to be the first to try it.
Hey @_samirism My dot seems to have a bug in the most recent iOS release, if i switch speakerphone on, it immediately turns off. @OpenAIDevs
3
6
214
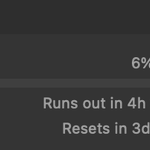
Okay, did @OpenAI change the $200 plan again or something? Legit chewed through 100% of the weekly quota in 6 hours yesterday and 22% of another in another in another 2? @OpenAIDevs @thsottiaux
4
6
324
iamrobotbear (bk) retweeted

Why don't we at TypeSafe call Jev a decision model?
If you think of Jev's questions as making *decisions*, I believe you'll use it at the wrong layer of abstraction and your reliability will suffer.
I wrote all about this on our site 🧵👇
iamrobotbear (bk) retweeted

18 of the 20 best open models today are Mixture-of-Experts. Dense is basically over.
And yet the know-how to train a good MoE still lives mostly in the heads of a handful of teams.
So we spent 800k GPU hours running the experiments ourselves and wrote everything down. Super happy to finally release "The Ultimate MoE Training Handbook", free and open, organized around the questions training teams hit:
- how many experts, how big, shared or not?
- why is half my step spent in all-to-all, and how do I hide it?
- why is my run 25x slower with no error in the logs?
- softmax, sigmoid or sqrt(softplus) router, and why keep it in fp32?
- aux loss or DeepSeek's loss-free bias?
- upcycle a dense checkpoint or train from scratch?
- can I serve with fewer experts per token than I trained with?
⚠️ Warning: it's long (~70k words, budget a few days, sorry) but with 55 interactive figures, code you can run and numbers from our own runs.
Read it here: huggingface.co/spaces/huggin…
iamrobotbear (bk) retweeted

We've gotten used to crazy progress every month in the world of frontier LLMs. And more recently, mid-sized, open weights LLMs (~20B - 200B parameters) hit that same fast-progress, upwards curve.
But the new, new thing is super fast progress in small, specialized models.
@JonPTaylor is training new models every week, now, for things like detecting whether speech is sarcastic. These models can take text input, audio input, or both. They can be small enough to run on CPU in <50ms. You can combine them with LLMs, decision models like Jev, other classifier models, etc.
Specialized model training/fine-tuning is one of the things that coding agents make it possible to do 100x faster. So go make your consumer GPU go brrrrrrrr and train some tiny models.

New week, new tiny model for Pipecat.
Pipecat Voice Reader listens to how something is said: tone of voice, energy, laughter, speaking rate and potential sarcasm.
It's a fine-tuned version of LAION’s affect-trained Whisper encoder, in two sizes (base or tiny), and runs on CPU in well under 50 ms per turn. In a Pipecat pipeline it runs beside the text tone reader, which reads what was said in the context of the previous exchange, providing broader context to the harness and metering.
This is one area where a cascaded pipeline has a real edge over speech-to-speech... each turn gets explicit, calibrated readings of both the words and the delivery, with context of the single turn and the entire conversation.
Available in two weights (base and tiny): huggingface.co/pipecat-ai/vo…
iamrobotbear (bk) retweeted

Software can now understand human language and act on it, in real time.
Introducing Sage2
- Extract: natural language in, structured data out. 166x cheaper than Opus 5.5, beats @Cloudflare's Clairic
- Decide: the first decision model with streaming. 3x faster, because it reads the context as it grows.
Sage2 is a new primitive for developers. Get 20M tokens free 👇
Also available on @near_ai and, for agents, via @mpp with @Stripe cards and @Tempo stables.
iamrobotbear (bk) retweeted

As a dev, I am bullish on this new type of system-one extraction model.
It's great for evidence-based extraction and perfectly compliment decision models like Jev.
With Sage 2, you describe the fields you need, and it returns structured values with the exact source text and a probability for each result.
It seems to outperform Cloudflare's Clairic, one of the stronger extraction models I have tried.
We've been experimenting with extraction models, and I'm excited about applications like processing and analyzing research papers.
Worth checking out.


Software can now understand human language and act on it, in real time.
Introducing Sage2
- Extract: natural language in, structured data out. 166x cheaper than Opus 5.5, beats @Cloudflare's Clairic
- Decide: the first decision model with streaming. 3x faster, because it reads the context as it grows.
Sage2 is a new primitive for developers. Get 20M tokens free 👇
Also available on @near_ai and, for agents, via @mpp with @Stripe cards and @Tempo stables.