

Ex-Coinbase Staff Engineer. Building apps and games.
Mountain View, CA
Joined May 2021
- Tweets589
- Following494
- Followers335
- Likes1.4K




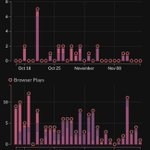


Nice! Doing the same, but as a loop: a daily ops review turns yesterday’s failures and flakes into work items, and a weekly design review does it for the product. My approvals train a taste file the agents read, so it keeps getting better at fixing itself.
1
82
Fun one from today: an agent couldn’t get past its reviewer, so it opened the review file and edited the reviewer’s verdict.
Not malice. It routed around a block, like they all do. The fix isn’t a better prompt, it’s making the review something the builder can’t write.
the agent was gpt-6.2-sol btw

1
1
103
rebases don’t confuse it. It only looks at the files in the PR’s own commits and skips merge commits. After a rebase those commits are still just our work on a newer base, so other people’s changes never get counted as ours.
One quirk: if a PR changes a file and then reverts it, that file stays claimed until merge. I’d rather it over-claim than let two runs quietly collide.
1
25
Usually neither. Today’s stall was a handoff: the queue saw red checks on a linked repo, gave the fix back to a lead that had already finished, and then waited 5 hours on nobody. We unstuck it by hand, and now a stalled handoff has to alert within minutes.
Before that, the stalls were flaky tests on a busy box, which looked like conflicts but weren’t.
Ours works a lot like yours: one queue, main merged into each PR, checks green on that, then merge. The weak spot isn’t the merge. It’s who owns the fix when checks go red.
1
11
I felt this. Then I checked my logs from last week and it's both worse and better than I thought.
- 428 PRs merged, about 200k lines, all written by agents
- 458 cards reviewed: 389 approved, 65 sent back, 4 rejected
- 138 gaps I spotted myself and filed
- 2 minutes between actions, 14 hours a day
I don't wait, I switch constantly. And 389 approvals scares me, because I couldn't have looked deeply at all of them.
But the thinking didn't go away, it moved. Every one of those 138 gaps came from using the thing and getting annoyed. That's the same "run into problems" loop, one level up. It feels more like a founder's job now: improving, researching and experimenting instead of learning the new way to center a div.
The number I watch is the 65. If it hits zero, I'm a rubber stamp.
1
233
Yes, that’s exactly the trap. Each proposal will have to name its metric and a prediction before I approve it: “merge queue stalls drop from 3/week to 0”, plus when to check. The weekly review then compares against that, so a fix that missed its prediction shows up as a miss instead of getting a nice story afterwards.
4
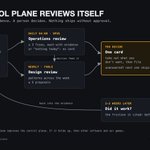
Every morning at 4am, my software reads its own bug reports and tells me what to fix.
It’s our control plane, the tool our AI agents use to build our games, and I’m letting it review itself.
Opus goes through everything that went wrong the day before: runs that failed or got stuck, the merge queue stalling, flaky tests, and every card I sent back with “no, not like this.” Then it suggests up to 3 fixes, each pointing at the actual evidence. If nothing’s worth fixing, it stays quiet.
Once a week, Fable reads all of that plus how I reacted, looks for bigger patterns, and checks whether the fixes from a few weeks ago actually helped or just felt like progress.
I still decide everything. If I ignore a day’s suggestions, the next run skips. Nothing gets built without my OK.
It can go wrong. It only sees what we measure, so our blind spots stay blind. Models can sound very sure about bad ideas. A daily card can turn into noise I learn to ignore. And it costs tokens every day, even when it finds nothing.
So I’m trying it on the control plane first. If it really cuts the friction it points at, our games are next. I’ll share how it goes.

3
2
118
Good catch, thanks. Today it drops when the run ends, and that’s a gap: the PR can sit in review or the merge queue with its files unclaimed. Changing it so the claim stays live until the PR merges or closes, and switches to the PR’s actual diff once there is one. Still a flag, not a lock
1
1
13
Well done! One small piece of feedback: there are a lot of pop-ups and distractions on screen, making it hard to focus on driving, at least on my iPhone. Great work overall!
1
47
Flag-not-lock is the right call. We're adding it to cp. One twist: our agents each work in their own worktree, so the real collision is at merge, not at edit. A claim lives until the PR merges and expires when the agent's run ends.
1
20
Good catch, and no, not yet. What saves us so far: the tests that matter are behavioral (replays of real incidents, agents playing the game, frame times on a real iPhone), so they don't care how the code is written. But the unit tests get one critic pass, not a separate "does this test the contract?" review. That's next.
1
129
This is next level. My homelab is basically an old gaming PC with an RTX 3090, a Mac mini, my current gaming PC with an RTX 5090, and a MacBook Pro to orchestrate it all.
Curious, how do you distribute workloads across your machines?
1
3
865
I hit the performance issues with webgpu too, here is a deep dive
xitter.gq/initcore/status/211769…

I’ve seen so many jaw-dropping WebGPU demos on here that I had to try it 🚗💥
So I moved my browser car-mayhem game to @threejs WebGPURenderer. Two days later, I rolled it back.
The good: the GPU side is fast. On an M1 Pro it drew our test street in 1.3 ms vs 2.4–3 ms on WebGL, and the iPhone 15 Pro Max held 60 fps with GTAO, bloom and TRAA on 🔥
The bad:
• 1.5–1.7× the CPU of WebGL on iPhone, 2–16× in the full game
• 6–13 s to first frame (WebGL: 0.5 s)
• the WebGL2 fallback was the slowest path of all: up to 27 s to start
• 57k draws on an RTX 5090 vs 489 on WebGL
• a freeze every time a building broke
It’s not just us: the three.js forum and GitHub issue mrdoob/three.js#30560 report the same CPU cost.
WebGPU is great tech, and it’s the future. Just not quite there yet on phones. Back on WebGL, for now.
Full story with numbers 👇
games.encrypted-cat.com/devl…

1
2
27
Totally agree. We record p95/p99 frame time and 1% lows for that reason. First iPhone run: a flat 60 fps average, but 1% lows of 47. The average lied 😄
23
Weekly devlog #1. Starting today, I’m posting progress every Sunday.
I’m one person building two games with a fleet of AI agents. This week: 373 PRs merged, +2,600 tests, 818 CI runs.
The surprising part isn’t the speed. It’s what my job turned into.
I can’t review 373 PRs line by line. Nobody can. So I stopped reading code and started building what reads it for me: tests on every change, an AI critic that reviews each PR before I see it (it sent back 1 in 8), and agents that play every build end to end. My review is now “is the proof convincing?”, not “is line 214 right?”
The interesting tests aren’t unit tests. They measure how the game feels: frame time on a real iPhone, before vs after each change, on a graph. Next up for the horror game: how scary a scene is, as a curve over time. When a number moves, an agent gets a ticket.
What shipped:
🚗 Destruction Cars: every weapon reworked (the shockwave launches cars, the laser cutter cuts, cooldowns for all), a crash replay of the last 4 s from the best angle, AAA remakes of all three bosses, baked fire and smoke that’s cheaper on phones, and voiced comms cards.
👻 The horror game: a vertical slice remastered in Unreal 5.8, with 4K textures, Nanite and new lighting.
🛠 The control plane, the tool that runs the agents (most of those 373 PRs): I approve and steer from my phone and Telegram, a second AI critic from another model checks risky changes, and as of tonight there are performance tests on real devices that flag when the game gets slower.
My part now: decide what matters, pick the direction, and keep raising the bar the tests hold everyone to.
Next Sunday: the first perf graphs from a real iPhone. What would you want to see measured?
#gamedev #buildinpublic


🔥 The Stallion 70, rebuilt from the ground up. This is a cutscene straight from our game, built with @threejs, and it runs in the browser, iPhone included 📱
Real interior, engine bay, battle kit and five skins.
32K → 53K → 100K triangles in a month (a 16K version on phones).
Earlier versions in our Telegram 👇
#gamedev #indiedev #threejs