
PhD Student @PrincetonCS @PrincetonPLI. Previously @SCSatCMU.
Joined May 2022
- Tweets35
- Following503
- Followers549
- Likes212





Pinned Tweet
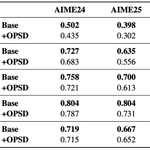
New Paper: Rethinking On-Policy Self-Distillation for Thinking Models
On-policy self-distillation (OPSD) is a promising approach to recursive self-improvement. Thinking models seem especially well positioned to teach themselves with privileged information since they can deliberate, verify, and self-correct.
Surprisingly, we find that OPSD can make thinking models worse.
(More details in 🧵below)

Self-distillation does not work for thinking models YET
arxiv.org/abs/2603.24472
openreview.net/forum?id=VhCJ…
arxiv.org/abs/2606.11709

Simran Kaur retweeted

New blog post on continual learning for LLMs! 🚀 How can post-trained models learn from off-policy data without forgetting?
We find that:
- Simple model merging makes off-policy SFT surprisingly strong
- A new method, grafting: learning updates on earlier checkpoints and transferring them to post-trained models largely removes forgetting!
- Substantial gains on hard math, self-improvement, and knowledge injection while preserving existing capabilities
We dive deeper into the intuitions and experiments in this blog! ar-forum.github.io/grafting-…
I’ll be in SF next week for #COLM2026! If you’re around and want to grab coffee / chat, feel free to DM :)
I’ll also be presenting "Rethinking On-Policy Self-Distillation for Thinking Models" at these workshops:
- Efficient Reasoning (spotlight)
- Context Beyond the Window: Persistent Knowledge in Language Models
- Scientific Understanding of Foundation Models
Simran Kaur retweeted

Excited about this paper (presented at 2 ICML workshops). On-policy self-distillation (i.e., model learning from a copy of itself that has privileged info, e.g., gold answer) is popular. It fails for thinking models at longer thinking budgets! Reason: interferes with self-doubting. See the tweet thread by @kaur_simran25

New Paper: Rethinking On-Policy Self-Distillation for Thinking Models
On-policy self-distillation (OPSD) is a promising approach to recursive self-improvement. Thinking models seem especially well positioned to teach themselves with privileged information since they can deliberate, verify, and self-correct.
Surprisingly, we find that OPSD can make thinking models worse.
(More details in 🧵below)
(7/n) Takeaway: teacher-side privileged context can suppress the deliberative behaviors that thinking models depend on. Making OPSD work for thinking models remains an open question.
Shout out to my awesome collaborators Narutatsu Ri (@narutatsuri), Liam Fowl (@liam_fowl), Yinghui He (@yinghui_he_), and Sanjeev Arora (@prfsanjeevarora) !
If you’re at NeurIPS, come check out our poster at the Efficient Reasoning (Spotlight) and MATH-AI workshops! 👇

How does RL improve OOD reasoning? How can we distinguish compositional generalization from length generalization? What makes a composition more learnable?
Check out our #neurips2025 workshop poster tomorrow!
🗓️Sat, 12/6, 8am-5pm
Efficient Reasoning
📍Exhibit Hall F (Spotlight)
MATH-AI
📍Upper Level Ballroom 6A
🔗arxiv.org/abs/2512.01775
Joint work with @kaur_simran25 @prfsanjeevarora

Simran Kaur retweeted

Kids use open textbooks for homework. Can LLM training benefit from "helpful textbooks" in context with no gradients computed on these tokens?
We call this Context-Enhanced Learning – it can exponentially accelerate training while avoiding verbatim memorization of “textbooks”!
A thread 🧵1/N

Simran Kaur retweeted
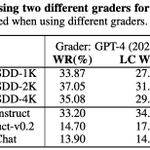
1/ New instruction-following dataset INSTRUCT-SKILLMIX! Supervised fine-tuning (SFT) with just 2K-4K (query, answer) pairs gives small “base LLMs” Mistral v0.2 7B and LLaMA3 8B performance rivalling some frontier models (AlpacaEval 2.0 score). No RL, no expensive human data. “Secret sauce”? Leveraging LLM metacognition!

Excited to share Instruct-SkillMix, a pipeline for generating high quality, diverse synthetic SFT data.
SFT on just 4K examples can boost LLaMA-3-8B-Base over LLaMA-3-8B-Instruct, yielding 42.76% LC win rate on AlpacaEval.
Paper: arxiv.org/abs/2408.14774

Additionally, we perform a preliminary exploration of difficulties in naive instruction-tuning. Replacing 20% of SFT data with “poor quality” data (i.e., deliberately sloppy and unhelpful) leads to super-proportional harm to the models.
[7/n]

tldr; when done well, synthetic data can be quite effective!
Joint work with my amazing coauthors @parksimon0808 @anirudhg9119 @prfsanjeevarora