


this is actual f*cking gold
YOU'RE PAYING 40X MORE FOR THE SAME CLAUDE ANSWER.
half of x says opus 5.5 got nerfed this week.
one guy ran 1,400 claude code sessions through gemini and says something changed on nov 3.
maybe. but here's what eats most limits:
one model doing every job.
opus 5.5: $20 per 1M output tokens
haiku 5.5: $0.50
same rename. same file search. 40x the price.
the split that fixes it:
→ haiku 5.5 - search, rename, logs, 1-line fixes
→ sonnet 5.5 - writes the code
→ opus 5.5 - plans and reviews. nothing else
it won't fix a real bug on anthropic's side if there is one.
but most people pick the smartest model for everything.
the smart ones pick the cheapest model that can do the job.
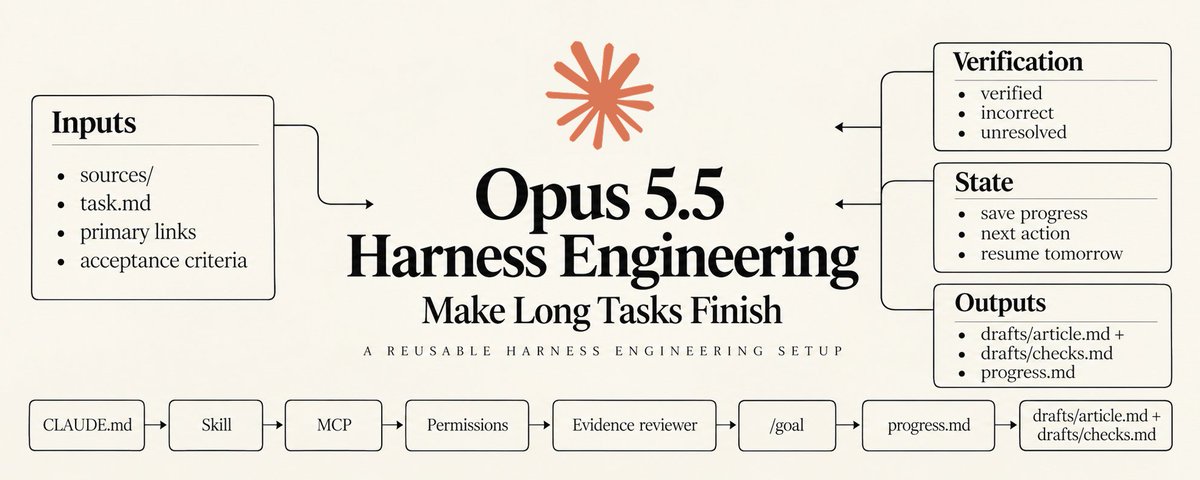
the setup that stops opus looping on long tasks is in the article below.
which model do you run all day?

paste this at the start of your claude code session:
you are the lead. before every task, route it:
- haiku 5.5: search files, read logs, rename, format, run tests, 1-line fixes
- sonnet 5.5: write and edit code, normal features
- opus 5.5 (you): plan, hard bugs, final review only
use subagents with the cheapest model that can do the job.
never do haiku's work yourself.
after each task, write one line: which model did it and why.
THIS IS F*CKING UNFAIR
YOU'RE RUNNING CLAUDE AT 18%. THE PEOPLE WHO SET IT UP RIGHT GET 95%. SAME MODEL. SAME SUBSCRIPTION.
claude code has a flag almost nobody types:
claude --model sonnet --advisor opus
sonnet 5.5 drives. haiku 5.5 does the crawling. opus 5.5 only shows up when it matters
opus 5.5 costs 60x more than haiku 5.5. and you're paying it to grep files
price per million tokens, from the guide below:
→ opus 5.5: $15. architect and judge
→ sonnet 5.5: $3. writes the code
→ haiku 5.5: $0.25. checks every tool call before it runs
→ fable 5.5: $2.50. attacks the diff looking for bugs
18% in a raw chat vs 95% in this setup. his numbers, not anthropic's
the part that got me: in a raw chat agents still write "all 48 unit tests passed" without running a single test
here a separate model has to prove it before git lets the commit through
paste this into claude code ↓
"set up my claude code around 4 roles:
1. main session on sonnet 5.5 with opus 5.5 as advisor
2. haiku 5.5 subagent: checks every bash call and runs the tests
3. fable 5.5 subagent: skeptic. tries to break every diff, replies approved or rejected
4. no commit without an approved verdict
show every change as a diff first. no edits until i say go"
his full 7-stage harness is in the article below
which model is burning your limits right now?


this feels like f*cking cheating
ANTHROPIC JUST SHOWED HOW TO BURN HALF THE CLAUDE CODE LIMITS.
sonnet 5.5, haiku 5.5 and opus 5.5 in one session. every model does one job
you're paying opus to grep files and burning your limits by lunch
one command:
claude --model sonnet
→ sonnet 5.5 leads the session and writes every fix
→ haiku 5.5 crawls the repo in parallel: search, call sites, diff checks
→ opus 5.5 sleeps until it's needed, then signs off on the diff
opus steps in only 3 times:
→ before a plan locks
→ when the same error shows up twice
→ before anything gets called "done"
#3 is where most agents lie to you
sonnet builds. haiku crawls. opus judges.
paste this into claude code ↓
"reconfigure my claude code setup around 3 models:
1. keep the main session on sonnet 5.5
2. create 3 haiku 5.5 subagents in .claude/agents: search (maps the repo, read-only), grep (finds call sites), audit (checks the diff)
3. create 1 opus 5.5 subagent: reviewer. it only reads the plan and the final diff and replies approve or reject
4. add a rule to my claude md file: every repo search and test run goes to haiku. call the reviewer before a plan locks, after the same error twice, and before done
show me every change as a diff first. no edits until i say go"
one dev built his whole agent around moment #3
412 test runs every night. one tiny prompt edit dropped his refund flow from 0.91 to 0.74
no error. no crash. a customer would've noticed first
his full setup is in the article below
which model writes your code right now?


THIS IS ACTUAL F*CKING GOLD
an anthropic engineer just shared how he makes claude check its own work
and burn way fewer tokens doing it
most people still run one model for everything
his setup: 3 models in one session. each gets one job
→ haiku 5.5 (the cheapest): search, tests. all parallel
→ sonnet 5.5 (the middle one): writes the code
→ opus 5.5 (the most expensive): does nothing. until it's needed
opus wakes up only 3 times:
1. before the plan locks
2. same error twice
3. before "done"
#3 is where your agents lie to you
he describes it like this:
an agent hands you a 600-line PR
the tests pass. the names look fine. you approve
somewhere in the middle, one default got flipped
the green check proved the tests passed. not that the code works
so opus checks in a fresh context
it never saw the code being written. only the plan and the diff
the cheapest model does the dirty work. the smartest one only says yes or no
one command:
claude --model sonnet
then paste:
"set up my claude code with 3 models:
1. 3 subagents in .claude/agents on haiku 5.5: search (read-only), grep (call sites), tests
2. 1 subagent on opus 5.5: reviewer. fresh context. reads only the plan and the final diff. approve or reject
3. rule in CLAUDE.md: search and tests go to haiku. reviewer runs before the plan locks, after the same error twice, and before done. last step: "did i miss anything?"
show every change as a diff first. no edits until i say go"
that last question is his trick
he says it often finds 2-3 more things
his full breakdown is in the article below
how many models do you run?

THIS SHOULD BE F*CKING ILLEGAL
you're overpaying for claude and burning through your limits by lunch
anthropic tucked the fix into their own claude code docs and almost nobody uses it:
sonnet, haiku and opus 5.5 in one session. one job each
→ haiku 5.5 does the dirty work: search, call sites, test runs. all in parallel
→ sonnet 5.5 writes the code
→ opus 5.5 does nothing. until it's needed
opus wakes up only 3 times:
1. before the plan locks
2. when the same error hits twice
3. before anything gets called "done"
#3 is where most agents lie to you
the cheapest model does the grunt work. the smartest one only says yes or no
one command and one prompt:
claude --model sonnet
then paste this:
"set up my claude code around 3 models:
1. create 3 subagents in .claude/agents on haiku 5.5: search (maps the repo, read-only), grep (finds call sites), tests (runs the suite)
2. create 1 subagent on opus 5.5: reviewer. it only reads the plan and the final diff and replies approve or reject
3. add a rule to CLAUDE.md: every repo search and test run goes to haiku. call the reviewer before a plan locks, after the same error twice, and before done
show me every change as a diff first. no edits until i say go"
one dev built his whole agent around that #3 moment
every night 412 test runs. every failure read
one night it caught his refund flow crashing from 0.91 to 0.74 after one tiny prompt edit
no error. no crash. the first one to notice would've been a customer
his full harness is in the article below
which model would you trust with the final yes?
youtube pays 3x more for the same f*cking claude script
$35,000 A MONTH. NO FACE. ONE GUY + CLAUDE.
he mapped out how he'd take a faceless youtube channel to $35k a month
step 1 comes before any video - pick the niche by what youtube pays per 1,000 views:
→ finance: up to $30
→ documentaries: up to $25
→ ai: as low as $10
for $35k a month that's ~1.2M views in finance vs ~3.5M in ai (his numbers, "not guaranteed")
same claude scripts. 3x the views for the same money
the combo he says rarely works: generic script + ai voice + stock footage
his setup instead:
→ claude writes like a documentary scriptwriter - a hook in the first seconds, a new question every section, 1,500 words
→ elevenlabs for the voice
→ midjourney or flux for visuals, runway for video
→ capcut to cut it all together
his week: research → scripts → voice + visuals → editing → thumbnails + upload → analytics
the exact claude prompt is in the article below
finance, ai or documentaries?


this is f*cking insane
$20,000 in 30 days. from cartoons claude drew.
a youtube channel went from zero to 7M views in one month
no face, no voice actor, no animator
every video is motion graphics claude wrote in code
50k subscribers in the same 30 days
an estimated $20k+ in month one
then a creator cracked the whole process and gave the skill away for free
so copycat channels are already popping up
everyone else is still paying $100 a month for ai avatars and cloned voices
this one did it with plain animation and one tool
the article below breaks down 5 ways people are turning claude animation into $100k/mo
would you start one?

your ssd has been secretly running at half speed for years
f*ck crystaldiskmark. claude caught it in one prompt
crystaldiskmark: 3,665 MB/s
my files from 2023: 1,486 MB/s
SAME DRIVE. 2.5X SLOWER
the idea came from the article below:
a dev fixed his parents' old android tv with claude code
then packed it into one markdown file anyone can paste
no root, nothing uninstalled, one line undoes it
if claude can audit a tv, it can audit my pc
zero code from me. the prompt:
"test read speed of my oldest large files vs a freshly copied file"
→ wrote its own c# tool to skip the windows file cache
→ dug up my oldest big files from 2023-2024
→ clocked them at ~1,500 MB/s vs ~3,000 for a fresh copy
→ rewrote them and checked sha256 byte for byte
→ re-tested: ~2,900 MB/s
the weird part: reading them twice already pushed them to ~2,270
the rewrite did the rest. the file it didn't touch moved +4%
benchmarks only read a fresh test file
that's why they never catch this sh*t
tv, pc, anything with a shell
testing yours tonight?


this is f*cking insane
THIS YOUTUBE HOST MADE $300,000 IN ONE MONTH. HE DOESN'T EXIST
an amish farmer. a trucker. a retired handyman
zero of them are real. all of them get paid
one channel hit 360k subscribers in about 3 months
every word these hosts say is written by claude
here's the whole machine:
→ claude writes every single script
→ the pictures for an entire channel cost $0.54
→ a $47 ebook sits under every video
$0.54 in. $300,000 out
a real host, a camera crew and an editor can't touch this math
the catch: most people copy these channels 1:1 and get 200 views
what separates 360k subs from 200 views is in the piece below
which niche would you give a fake host?


HOLY F*CK. ALL OF THIS IS FREE
$29,077 WORTH OF CLAUDE CODE TOOLS
970 skills. 273 agents. 1.8M stars.
marketplaces sell the same thing for $19 a skill and $39 an agent
68,900 repos tagged claude-code. these 20 made the cut:
1. everything claude code → 71 agents, 311 skills and 97 commands in one harness
2. agent-skills → 25 production skills by addy osmani: spec, plan, build, verify, review, ship
3. ruflo → agent swarms across claude code and codex with one shared memory
4. agents → 202 agents, 185 skills and 105 commands in 94 installable plugins
5. claude-mem → records what claude did and feeds it back next session
6. planning-with-files → the plan lives on disk and survives /clear, compaction and crashes
7. graphify → turns code, docs and sql schemas into a knowledge graph, nothing leaves your machine
8. understand-anything → a searchable map of your codebase with diff impact analysis
9. ponytail → 53% less code and 45% fewer tokens on opus 5.5, in its own benchmark
10. rtk → a rust proxy that cuts 60-90% of tokens from dev command output
11. headroom → compresses logs, tool output and json before the model sees them
12. context-mode → 315 kb of tool output in, 5.4 kb reaches the model
13. ui ux pro max → 79 styles, 192 palettes and 74 font pairings
14. taste-skill → art direction plus a browser check at several screen widths
15. video-shotcraft → turns your real pages into a product video in remotion
16. agent-reach → youtube, github, reddit and the web from one cli, $0 api fees
17. cc-switch → switch providers in 1 click, manage mcp, skills and prompts in one app
18. pm-skills → 69 product skills and 42 chained workflows
19. claude-skills → 380+ skills from engineering to finance
20. career-ops → scores every job against your cv and drafts the application
the catch: every plugin eats context. start with 3, not 20 - remember that part
most people still run claude code with none of this
nate tried 100+ claude repos and kept 10. his picks are in the article below
which one are you installing first?


links:
1. github.com/affaan-m/everythi…
2. github.com/addyosmani/agent-…
3. github.com/ruvnet/ruflo
4. github.com/wshobson/agents
5. github.com/thedotmack/claude…
6. github.com/OthmanAdi/plannin…
7. github.com/Graphify-Labs/gra…
8. github.com/Egonex-AI/Underst…
9. github.com/DietrichGebert/po…
10. github.com/rtk-ai/rtk
11. github.com/headroomlabs-ai/h…
12. github.com/mksglu/context-mo…
13. github.com/nextlevelbuilder/…
14. github.com/Leonxlnx/taste-sk…
15. github.com/Vincentwei1021/vi…
16. github.com/Panniantong/Agent…
17. github.com/farion1231/cc-swi…
18. github.com/phuryn/pm-skills
19. github.com/alirezarezvani/cl…
20. github.com/career-ops-hq/car…

this is actual f*cking gold
$5M A MONTH APP. ITS VIEWS COME FROM 7 SLIDESHOW PAGES
CLAUDE MADE 120 OF THEM IN ONE GO
100M views. not one video filmed. not one creator paid
one founder copied the playbook and hit 10M views on his own page
here's how:
→ his ai agent scanned 353 slideshows of the biggest page in his niche
→ found 3 formats. the top one averages 6M views per post
→ claude turned them into 120 slideshows. 2 months of content in one go
120 ugc videos would cost $1,800-3,000 and weeks of work
claude did it with a few photos and a hook
he says every 5M views = $2,000-5,000 in revenue
what niche would you start this in?

this should be f*cking illegal
$41,000 A MONTH. FROM VIDEOS NOBODY EVER FILMED
one guy runs a faceless youtube channel and says claude does almost everything
finance, tech and ai, business stories pay $10-30 per 1,000 views
so $41k a month means 1.4 to 4.1 million views. with no camera. no team. no face
here's what claude does:
→ writes 10 scripts in 1 day
→ opens each one with a pattern interrupt in the first 5 seconds
→ plants a curiosity loop every 45 seconds
elevenlabs reads it. runway moves it. capcut cuts it
he just picks the title and thumbnail
a production studio would bill months for this. he runs it alone
send this to the friend you'd start this with

YOUR CLAUDE MD IS MAKING OPUS 5.5 DUMBER AND MORE EXPENSIVE.
it was written for older models.
opus 5.5 follows it more literally.
every vague line turns into extra tool calls. you pay for each one.
"always check every file" alone = 9 tool calls.
anthropic's fix is one command, one rule: "nothing changes until you approve"
→ /claude-api prompt-audit
→ it reads your claude md, skills and prompts
→ flags the lines that burn tool calls
→ proposes a fix for each one
→ you say yes or no
anthropic's test: costs down another 9%.
my run: tool calls 2,023 → 968, accuracy +2.
it flagged "never skip tests" too. i said no. remember that part.
everyone raises the effort setting. nobody rereads the file.
then set claude up once, in this order:
memory → projects → skills → connectors → schedule
skip to the schedule first and it's wrong every morning at 8.
the audit mapped out below - at 0:09 one line lights up 9 calls.
the full setup order is in the guide below

A 365K-STAR REPO LETS CLAUDE CODE CLONE ANY APP FEATURE WITHOUT READING ONE LINE OF ITS CODE.
it's called rea. its own team tested it on notion's clipboard and rebuilt 90s games with it.
so i tried something smaller - one search bar.
4 claude code agents rebuilt it in 4:52 without seeing a line of the original.
your moat was never the code.
→ scout opens the feature and tags 24 findings with evidence
→ spec writer turns them into requirements, 0 original names kept
→ builder gets a locked worktree and never sees the app
→ tester runs both side by side through 18 cases
→ match starts at 64% and hits 100% after 2 edge cases get fixed
3 of the 24 findings stayed "unknown". the spec shipped anyway. remember that part.
everyone copies the 4 prompts. nobody copies the 1 line inside the scout's: "only software i own or am authorised to examine".
the repo is free. the tokens aren't - 170 tools load before the first call.
setup is one line: npx rea-agents setup
the loop mapped out below - at 0:18 it's stuck at 64%. watch what fixes it.
all 4 swarm prompts are in the guide below


THE MODEL THAT FAILED MY TASK TWICE SHIPPED IT 6 MINUTES LATER.
same prompt, same weights.
in a chat box it failed twice. on the second try it forgot a decision it made 3 minutes earlier.
"model's not good enough," i thought.
then i listed what it had to work with: no contract, no map, no tools list, no state, no sensors, no policy, no traces. 7 rows, all "missing".
so i stopped editing the prompt and built the room around it.
i wrote a contract with 1 goal, 3 constraints and 4 checks for "done", and locked deploy and delete behind a human.
first run inside the harness: red tests, fail.
second run: 42 passed, 0 failed, $3.84.
here's what got me: a human took the last step. deploy sat on "waiting human" until a reviewer said yes.
and that's when it hit me - i'd burned 2 attempts on a prompt, and the bug was those 7 empty rows.
i haven't touched that prompt since.
the full loop is mapped out in the video - 7 jobs, 3 attempts, then a human.
full breakdown + 12-point checklist in the article below

there are bugs on github with cash on them
i went to bed. my agent went hunting
by 8am: 1,200 found. 31 fixes ready. $10,000 if they merge
the ones it kept paid $250-$350 a fix. $322 on average
the video is that night mapped out
the trick is what it threw away:
788 nobody had touched in 60+ days
252 where someone already sent a fix
anything bigger than a day of work
it only cloned the 31 that were left. ~1.9m tokens for the whole night
every monday at 23:00 it goes again on fresh bounties. i don't even start it
the catch: none of it pays until a maintainer merges. and it opened 0 prs - it's not allowed to without me
one repo it kept says "no ai-generated prs". so it's 30, not 31
how much do you think this does in a month?


mai retweeted
GOOGLE BUILT A SELF-IMPROVING AGENT. THE PART THAT DOES THE IMPROVING IS CLAUDE.
harness² went open source this weekend. the default editor is claude opus 4.8.
it never touches the weights. after every task it rewrites everything around them - prompt, tools, memory, skills.
glm-5 went from 64.2 to 75.7 after one rewrite.
→ runs the task once as a reference
→ tries 2 rewrites of its own setup
→ keeps what the runs back up, no grader needed
→ saves the lessons to EXPERIENCE.md for the next task
watch 0:12, that's where the new harness gets assembled.
the catch is every task runs 3 times, and google doesn't say what that costs. remember that part.
stock gemini lost to glm-5 wearing a better setup. google published that table themselves.
would you let claude rewrite your agent's setup after every task, or only after it fails?

