Sr Staff Research Scientist / TLM @ Waymo | World Models | Prev. PhD@Berkeley, Google, Cruise | Opinions are my own
Mountain View, CA
Joined November 2013
- Tweets80
- Following230
- Followers370
- Likes307

Max Jiang retweeted

Here’s what’s new with Genie 4:
🔵 Photorealism: Built on Gemini Omni for lifelike detail across spaces and subjects
🔵 Advanced physics: Aerodynamics, collisions, and people who move naturally
🔵 Real-time controls: Prompt to change the scene, add elements, or interact with characters
🔵 Native audio: Ambient sound, music, background noise, and interactive dialogue
🔵 Gemini reasoning: Plans multi-step events to maintain coherence as scenes evolve
These capabilities are a step toward developing safe virtual environments to see how agents and robots navigate their surroundings.
We’re exploring early use cases with trusted testers first, before bringing the model to Google AI Ultra subscribers in Project Genie and early access partners in our API and @GoogleAIStudio soon.
Find out more → goo.gle/48idm3b
Max Jiang retweeted
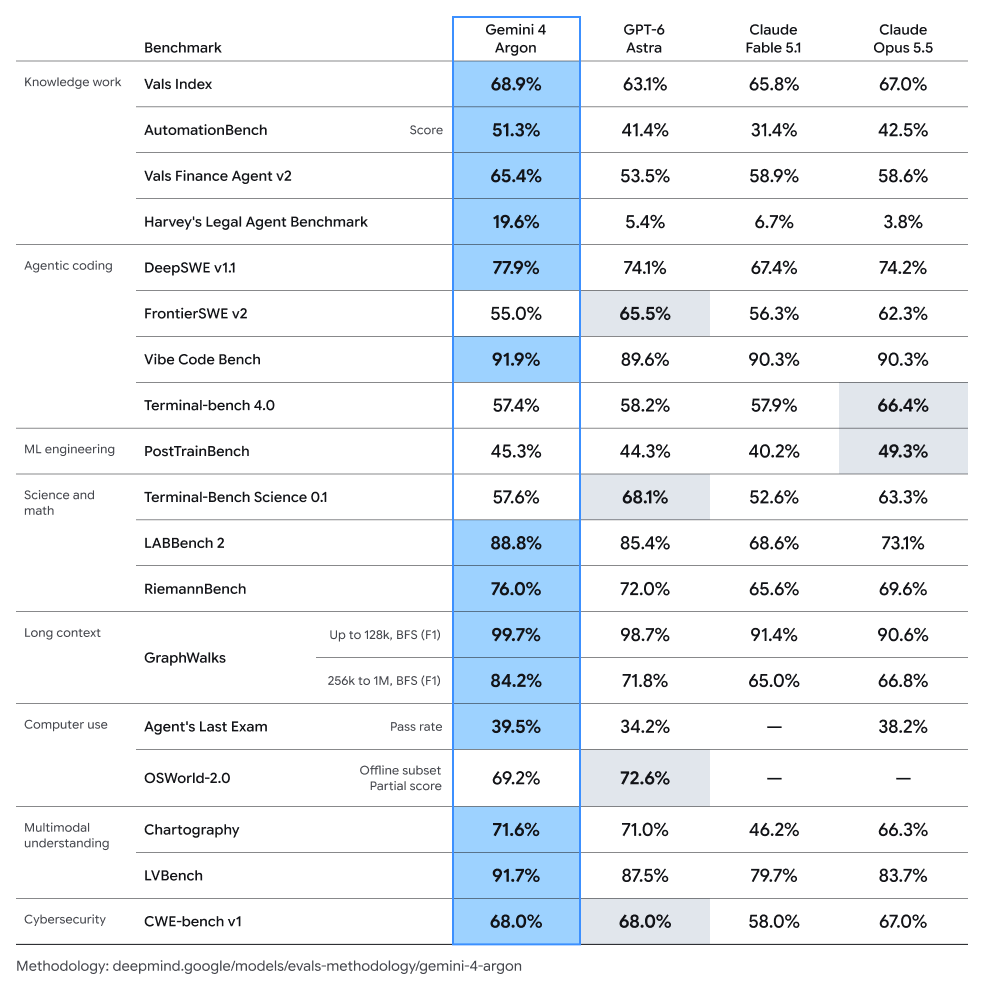
Introducing Gemini 4 Argon – our new frontier model.
It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.
Max Jiang retweeted

Gemini Omni is a major leap in world understanding & multimodal editing! It can take photos, video & audio and build entirely new scenes. Over time it’ll be able to handle any input & any output - starting w/ video
You can even give it your own videos & iterate on your ideas:
Max Jiang retweeted

📢Our team @GoogleDeepMind is hiring a Research Scientist in MTV, NYC, or SF!
Join us to push the frontiers of visual perception & spatial reasoning for multimodal foundation models like Gemini, Nano Banana, and more!
Send your CV to [email protected]

Max Jiang retweeted

Great use of Genie 3 from @waymo to create high-fidelity, interactive simulations of rare events that are nearly impossible to capture in the real world.

Genie 3 🤝 @Waymo
The Waymo World Model generates photorealistic, interactive environments to train autonomous vehicles.
This helps the cars navigate rare, unpredictable events before encountering them in reality. 🧵
Max Jiang retweeted
Super cool use case of Genie 3 simulations!

We’re excited to introduce the Waymo World Model—a frontier generative mode for large-scale, hyper-realistic autonomous driving simulation built on @GoogleDeepMind’s Genie 3.
By simulating the “impossible”, we proactively prepare the Waymo Driver for some of the most rare and complex scenarios—from tornadoes to planes landing on freeways—long before it encounters them in the real world.
waymo.com/blog/2026/02/the-w…
Max Jiang retweeted

Exponential scaling ongoing – @Waymo has officially doubled our fully autonomous cities in a matter of weeks, reaching 10 cities with the newest additions of San Antonio and Orlando. This is a testament to the maturity and generalizability of the Waymo Driver, our deliberate, safety-first approach to scaling, and an important step as we prepare to serve more riders across more cities soon.

Max Jiang retweeted

🚗 Excited to present our paper "Drive&Gen: Co-Evaluating End-to-End Driving and Video Generation Models" at #IROS2025!
📅 Time: 10:55–11:00, Wed, 10.22.2025
📍 Room: 103C, Paper WeAT27.6
arxiv: arxiv.org/abs/2510.06209
#IROS2025 #WorldModels #AutonomousDriving #GenerativeAI

Max Jiang retweeted

Can a single autonomous driving simulation world model jointly insert, delete, and control the behavior of all agents and traffic lights in a bird's-eye-view scene?
For the first time, we show this is possible in SceneDiffuser++, our CVPR '25 paper, w/ 60+ second simulations.🧵
Max Jiang retweeted

Genie 3 feels like a watershed moment for world models 🌐: we can now generate multi-minute, real-time interactive simulations of any imaginable world. This could be the key missing piece for embodied AGI… and it can also create beautiful beaches with my dog, playable real time
Max Jiang retweeted

Exciting news: @Waymo is beginning public service on the Peninsula, starting with Palo Alto, Mountain View, and Los Altos! Initial service area below.

Max Jiang retweeted
Exciting new @Waymo milestone: Waymo One is now serving 200k+ paid trips each week across LA, Phoenix and SF - that’s 20x growth in less than two years! Up next: Austin, Atlanta and Miami.
Max Jiang retweeted

Just sat down to read the DeepSeek-R1 paper. We're entering an era where compute isn't primarily for training. It's for creating better data. I expect to see the money & compute spent on data processing (generation / annotation / curation) grow to match and exceed the money & compute spent on pre-training.
People have talked about pre-training plateauing because we're "running out of data" on the internet to scrape. While that may be the case, capability improvements are going to continue full steam ahead. The improvements in intelligence are going to come not from putting in more data (scraped from the internet) but rather from putting in more compute (to generate higher-quality data). Intuitively, this feels similar to me to how people learn. You don't learn just by ingesting lots of tokens. In many cases, you learn by thinking more (I am referring to training time, but thinking more also applies at inference time).
There are many creative ways to put in more compute to get better data, and this problem will be an important research area for a number of years.
- In this paper, they train two models. Why two models? The first one (a reasoning model trained via RL) is used to generate data to train the second. This works by using the first model to generate reasoning traces and then selectively keeping only the high quality outputs (quality is judged by simply checking the results). This approach of "checking the results" works well for domains like math and coding where you can easily check the results.
- In drug development, it is super common to put compute into generating better data in two phases. In the first phase, a generative model (e.g., for protein sequences) generates a massive number of candidate drugs. In the second phase, scoring or filtering is done with a slew of predictive models which may predict structure, toxicity, solubility, binding affinity, etc. After all this work is done, you may end up with 100 data points.
- In physical domains (e.g., climate applications), expensive but accurate physics simulators exist (these simulations are run on super computers for long periods of time to simulate the physics of the atmosphere or some other system). All of that data can be used to train models, which is showing a ton of promise.
The question of "how to put more compute into generating better data" is central to progress in AI right now.
Max Jiang retweeted

We’ve been waiting for this moment and now we can share it with you: Today, we received our paid driverless permit from the CPUC! In the coming weeks, we’ll begin charging fares for rider-only trips and welcoming new riders into Waymo One in San Francisco. waymo.com/blog/2023/08/waymo…
Max Jiang retweeted

My first computer graphics research project in undergrad was to build an interactive system for artists to create complex shapes from a single image. Now, this whole process is automated with diffusion models!
Check out our NeRDi at #CVPR2023 !
Poster: cvpr2023.thecvf.com/virtual/…


Max Jiang retweeted
Expanded our rider-only (no human driver) 24x7 operations to all of SF and doubled the downtown PHX area including @SkyHarbor airport. Proud and inspired by what the team accomplished this year, leveraging some mind-blowing AI/ML advances. More exciting milestones ahead… onward!

Today we’re proud to announce:
➡️ We’re the first AV company to launch a commercial service to an airport
➡️ We just doubled our #DTPHX territory in a matter of weeks
➡️ We’re now rider-only 24/7 in all of #SF
We’re leading the way forward. blog.waymo.com/2022/12/wheel…
Max Jiang retweeted

Waymo One is now open to the public in Downtown Phoenix! Download @Waymo’s app, hail a ride 24/7 and enjoy a rider-only journey all to yourself. waymo.com/phx 🤖🚘
Max Jiang retweeted

I made a quick and dirty Stable Diffusion notebook that lets you batch your images and then saves them to your Google Drive. I hope you find it useful for the next few hours until someone makes something better. 😄
colab.research.google.com/dr…