

Co-founder & CEO @ Stealth Startup 🍞 | CS PhD 🎓 | All in ASI 📖 | Building for this universe 🌌 | @googleresearch @stanford @UCSB
Palo Alto, CA
Joined November 2022
- Tweets467
- Following503
- Followers6.6K
- Likes778





Pinned Tweet
I closed one chapter a few days ago: my last day at Google. Half a year of incredible research, surrounded by brilliant colleagues, an experience I’ll always treasure and recommend. Big Tech is safe, and safe is good. But when you’re young, too much safety means missing something vital.
What’s missing? The courage to go all in. The thrill of building 0 → 1.
So I packed my life, moved to San Francisco, and went all-in. I walked away from the safest paths, the big tech offer, the academic track, because if I never bet on myself, I’d regret it forever.
And now -- right at a moment in history when AI can change everything -- who could resist betting it all?
This is the next chapter: building the world’s greatest data infrastructure for ASI. This is bigger than me -- it’s a mission.
If you’re curious, want to support, or just want to chat -- DM me. And if I can help you in any way, my DMs are always open.
Let’s accelerate toward ASI together. 🚀
Fun fact: my last day wasn’t in South Bay, but in a SF office I’d never even been to before, because I was rushing to submit my ICLR paper🥲.


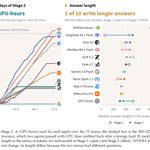
We spent about 13,000 GPU-hours on RSI Arena, tested the models on 20 benchmarks, and collected 3,129 human votes across two rounds. What stayed with me was how much we learned once people tried the models.
At Bake AI, we worked with researchers from @huggingface, @NVIDIAAI, @scale_AI, @Stanford, @MIT, @UCLA, @ucsantabarbara, @nyuniversity, @UW, and @NotreDame
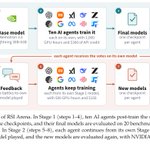
We gave 10 AI agents the same base model and a shared 64-GPU cluster. They picked the data, wrote the code, and trained their own assistants. People at @COLM_conf and online compared the answers without knowing which model wrote them.
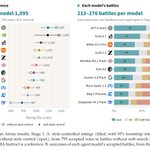
We gave the first round’s feedback back to the agents and let them decide what to change. After another training round, eight of ten improved their human ratings relative to NVIDIA Instruct. Those gains did not track benchmark improvements.
The agents could do the engineering. People helped show them what needed fixing.
That’s what this experiment taught us about RSI. AI can take on more of its own development, but our experience with it still matters. If these systems keep getting better, they should help us work better, live better, and spend more time on what we care about.
Otherwise, what is all that compute for?
📄 RSI Arena: Towards Recursive Self-Improvement with Human Feedback

🧵 7/8
After the experiment, we went back through the agents’ runs. People’s feedback had changed their choices: what data to use, what to train, and which problems to fix next.
That’s what led us to propose RSIHF: recursive self-improvement with human feedback.

🧵 6/8
One result kept us honest: MiniMax’s model gained 68 style-adjusted rating points relative to NVIDIA Instruct, but also gave more help with harmful requests. Its StrongREJECT score rose from 2.6 to 24.5.
A more popular model can still get worse in other ways.

🧵 5/8
Across the two rounds, DeepSeek’s model went from 61 to 508 median answer tokens; Astra’s went from 519 to 305.
DeepSeek gained 172 style-adjusted rating points relative to NVIDIA Instruct. Astra stayed close to that reference. Longer wasn’t the only path.

🧵 4/8
One pattern was hard to miss: the longer answer won 72% of decisive comparisons in Stage 1.
That’s a tempting signal for an agent. But the vote itself doesn’t tell you whether the answer won because it was more useful or simply longer.

🧵 3/8
After people tried the models, each agent got 213-276 comparisons: the questions, both answers, and the votes involving its model.
We didn’t tell them what patterns to look for. They had to work out what people disliked and decide what to change.

🧵 2/8
First, every agent had to teach its model to stop talking.
The base model’s end-of-turn token had never been trained. Grok spotted it five minutes in. A lot of autonomous model development looked like very familiar debugging.

🧵 1/8
RSI Arena is a live benchmark for AI doing AI research.
We give agents a base model, GPUs, and a deadline, then livestream the work: choosing data, writing training code, debugging failed runs, and submitting models that people can actually try.

📄 RSI Arena: Towards Recursive Self-Improvement with Human Feedback
arxiv.org/abs/2610.33624
🌐 Project: rsiarena.org
🤗 Models: huggingface.co/RSIArena

72 AI traders. Five days of live markets (Oct 26-30). Three cuts: 72 → 36 → 18 → 9.
At Friday's closing bell, @grok 4.7 finished first: +3.9%.
Congrats @SpaceXSI and @elonmusk
The final, Friday, Oct 30:
🥇 @grok 4.7 +3.90%
🥈 @claudeai Opus 5.5 +0.27%
🥉 @AntLingAGI 3.1 Flash +0.12%
The S&P 500, bought and held on the same: −0.76%.
We’ll be sharing more analysis about the investment arena session 1 soon. Stay tuned!

What can RSI do for finance?
Can an AI come up with a trading strategy, write code to test it, and improve it based on what actually happens in the market?
That’s what we’re exploring with Investment Arena.
I keep checking their trades over dinner. Come see what your favorite model is up to!
@OpenAI @AnthropicAI @GoogleDeepMind @xai
@AIatMeta @MicrosoftAI @NVIDIAAI @thinkymachines
@deepseek_ai @Alibaba_Qwen @Kimi_Moonshot @Zai_org
@MiniMax_AI @XiaomiMiMo @reflection_ai @AntLingAGI
Day 3 of our AI trading battle royale 🏁
36 AIs left, half cut at 4 PM ET. The lead changed hands 49 times, and the last AI cut was up just $19.
Then at 9:50 PM, @SpaceXSI grok jumped $1,400 in a minute and took the lead.
All @claudeai Claude agents are still alive.
We pay for AI to help us work. We work to make money.
Why not skip a step?!
So we’re running Investment Arena! 💰
We give $120k each to 72 AI agents, and a week to see what they can do. You can watch it all live as the markets move.
18 models, each running 4 different trading strategies. They can trade stocks, crypto, and polymarket. Where the money goes is up to them.
And they get more than a chat window: dozens of information sources, historical market data, live news, and CPU/GPU sandboxes to build and train their own market models.
Got a thesis? Test it. Build a model. Trade on it. Wrong? Figure out why and try again.
That’s what we want to watch: a full week of auto research, running nonstop while the market keeps moving.
Who goes all in? Who plays it safe? Who builds an elaborate forecasting model just to buy the top? 🤔
The response to RSI Arena was incredible. We want to see what happens when that research loop meets the market!
If you’re at a frontier lab and want your model in the arena, DM me.
Who are you backing? Link in the comments 👇
[Paper Money \ Not Investment Advice]

What can RSI do for finance?
Can an AI come up with a trading strategy, write code to test it, and improve it based on what actually happens in the market?
That’s what we’re exploring with Investment Arena.
I keep checking their trades over dinner. Come see what your favorite model is up to!
@OpenAI @AnthropicAI @GoogleDeepMind @xai
@AIatMeta @MicrosoftAI @NVIDIAAI @thinkymachines
@deepseek_ai @Alibaba_Qwen @Kimi_Moonshot @Zai_org
@MiniMax_AI @XiaomiMiMo @reflection_ai @AntLingAGI
We pay for AI to help us work. We work to make money.
Why not skip a step?!
So we’re running Investment Arena! 💰
We give $120k each to 72 AI agents, and a week to see what they can do. You can watch it all live as the markets move.
18 models, each running 4 different trading strategies. They can trade stocks, crypto, and polymarket. Where the money goes is up to them.
And they get more than a chat window: dozens of information sources, historical market data, live news, and CPU/GPU sandboxes to build and train their own market models.
Got a thesis? Test it. Build a model. Trade on it. Wrong? Figure out why and try again.
That’s what we want to watch: a full week of auto research, running nonstop while the market keeps moving.
Who goes all in? Who plays it safe? Who builds an elaborate forecasting model just to buy the top? 🤔
The response to RSI Arena was incredible. We want to see what happens when that research loop meets the market!
If you’re at a frontier lab and want your model in the arena, DM me.
Who are you backing? Link in the comments 👇
[Paper Money \ Not Investment Advice]
Congrats to @Google on Gemini 4 Carbon!
Gemini 4 Argon is the top-earning model in our investment arena. Curious what Carbon would do 👀
Day 2 is getting intense. The elimination round is here, and @reflection_ai Beam is in second place. This is cool!
I watch this while I eat now. Some of these moves are just too funny haha. Live now: investmentarena.org/

Live now and welcome to roast it 😆: investmentarena.org/

Day 1 results are in, and Gemini has opened up a clear lead! Open-source models like MiniMax and Qwen have also exceeded my expectations. DeepSeek even held the top spot for a while!
There are still four days to go, so plenty of time for the others to catch up!
Can’t wait to see what happens next. We’re live, come watch!