Creating a smarter world with Deep Learning, Human Performance Improvement and AI. AWS Certified Cloud Practitioner. All comments and RTs are my own.
Boston/Chicago
Joined June 2008
- Tweets1.8K
- Following3K
- Followers725
- Likes1.4K





Owen Lawlor retweeted

Elon Musk reposted one Grok Bot interview this week. Just one. It's this one.
SpaceXAI engineer, Lauren Tan:
"I was a meat proxy between my agent and my browser. So I fired myself.
Now 10+ Chiefs of Staff run my agents 24/7. I just check the work in the morning."
In one hour she shows how she built that dark factory with GrokBot:
Skills → Verification → Loops → Graphs
You are not the operator. You are the bottleneck. She removed herself - and the fleet took over.
The talk Musk decided everyone should see. Free, for now.
Bookmark it. The meat-proxy era is over. The dark-factory era is billing.


Owen Lawlor retweeted

introducing Jevbox: an open-source document drive that organizes itself, answers questions, and cites everything (all powered by Jev).
TLDR;
- upload anything and Jev categorizes and files it into the folder tree
- search is hierarchical: Jev picks the folder, then the document, then the section. No embeddings, no vector DB
- every answer cites the page and section it came from
- permissions are enforced at retrieval. If someone loses access to a source, they lose access to answers built on it too
- ships with an MCP server, so your agents get the same permission-aware context
@andrewlu0 has been experimenting with Jev internally and wanted to see how far it could go on a real document library. It's built on Extend Parse + Jev, and fully open-source
The GitHub has instructions to self-host, or you can deploy it to Render in one click

Owen Lawlor retweeted

THE CREATOR OF OBSIDIAN JUST SHIPPED HIS OWN CLAUDE SKILLS PACK
44,000 developers already installed it. most people building second brains with claude have no idea it exists
these aren't community skills. they're written by kepano himself - the person who built obsidian. that means they respect obsidian's actual conventions: markdown, bases, JSON canvas, backlinks, plugins, all of it
drop them into your claude skills folder once. next time you say "summarize my notes about karpathy" or "extract this article to my inbox," the right skill wakes up automatically. no prompt engineering. no manual context. no config
i tested 10 claude + obsidian repos to write my full breakdown. this is the one with the highest trust factor - because the person shipping it is the one who defined what an obsidian vault even looks like
the full ranked breakdown of all 10 is in the article
i test things like this on myself and share the results. follow @0xkkai if you want to see what's next


Owen Lawlor retweeted

Google Brain founder, Andrew Ng:
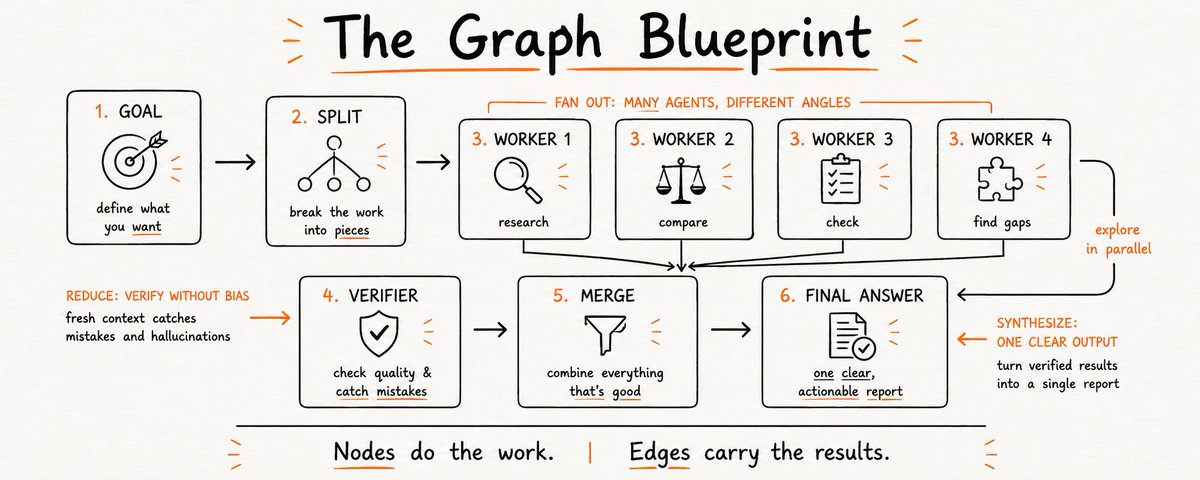
"Prompting will be dead in 6 months, graphs are what's replacing it."
In 2 hours at Stanford he shows how to build agents that work and improve entirely on their own.
The first 10 minutes cover what most $500 courses never do.
Watch the lecture first, then read the guide below on how to build a system that improves itself.

Owen Lawlor retweeted

Ein SpaceX-Ingenieur beschrieb einmal, was passiert, wenn Elon Musk einen Fehler in deiner Arbeit findet.
Der Ingenieur hatte eine thermische Analyse für ein Bauteil des Raptor-Triebwerks eingereicht. Das Dokument umfasste achtzig Seiten. Es durchlief die Prüfung von drei leitenden Ingenieuren. Es wurde genehmigt und für die Umsetzung eingeplant.
Zwei Tage später kam um elf Uhr abends eine E-Mail von Elon. Eine einzige Zeile. „Deine Berechnung des Wärmestroms auf Seite vierunddreißig geht von stationären Bedingungen aus, aber der Lastzyklus ist transient. Rechne es neu.“
Der Ingenieur sagte, er habe fünf Minuten lang auf diese E-Mail gestarrt. Nicht weil sie harsch war. Sondern weil sie stimmte. Die Annahme steckte tief in einer Teilberechnung, die keinem der drei prüfenden Ingenieure aufgefallen war. Elon hatte sie gefunden, in einem Dokument, das er gar nicht hätte lesen müssen, auf einer Seite, wo niemand von ihm erwartet hätte, dass er sie um elf Uhr abends an einem Dienstag gegenprüft.
Er sagte, genau solche Momente seien der Grund für die Kultur bei SpaceX. Nicht weil Elon Menschen mit Reden motiviert. Er hält kaum Reden. Die Kultur entsteht, weil jeder Ingenieur weiss, dass jedes eingereichte Dokument Zeile für Zeile von einem Mann gelesen werden könnte, der genau den einen Fehler findet, den alle übersehen haben. Nicht um zu bestrafen. Sondern um zu verhindern, dass der Fehler in die Hardware gelangt. Denn Fehler in Hardware führen zu Explosionen.
Die Angst gilt nicht der Kündigung. Die Angst gilt dem Gedanken, Arbeit einzureichen, die nicht das absolut Beste ist, und dass der CEO eines Sechs-Firmen-Imperiums genau den Fehler findet, den man selbst hätte erkennen müssen. Diese Angst erzeugt bessere Ingenieurskunst als jedes Motivationsposter es je könnte.
👉🏼 Eigentlich unglaublich, nicht?
Owen Lawlor retweeted
🚨#BREAKING: A 28-year-old confirms he has spent the last 10 YEARS of his life interviewing World War II combat veterans to keep their stories alive...
...in fact, for the last 10 years, he has interviewed World War 2 veterans EVERY SINGLE DAY
He started as a teenager, ditching school to ride his BIKE to the local retirement home, walking up to the front desk and asking to, "meet some World War II heroes."
His name is Rishi Sharma.
He's crossed all 50 states and half the world.
He's slept in his car and lived on gas-station food to afford it.
He asks these men for hours of their memories, and then he hands the entire recording to their families...
...FOR FREE
So that 200 years from now, a great-great-grandchild will know not just their hero's name, but how he laughed, how he cried, and what he sacrificed.
Rishi has no military family, his parents immigrated here from India.
He does it out of pure gratitude.
In his words:
"My parents were given the opportunity to immigrate and raise a family because of veterans like these. It's a debt of love I'll spend my entire life trying to repay..."
As one 100-year-old Marine who stormed Iwo Jima told him, remembering the flag going up:
"The hair on my arms still stands up when I think about how beautiful it was."
THAT is America.
250 years of ordinary people doing extraordinary things...
God bless our veterans. 🇺🇸🇺🇸


Owen Lawlor retweeted

In twelve months, EVERY company will be running a Company Brain.
The teams who build it this year will spend the next year compounding. Everyone else is going to play catch up.
Here's what it actually is. You connect your Slack, your GitHub, HubSpot, all your tools into one intelligence layer, then build the org chart around it: a main brain up top, a fleet commander running the agent fleet, specialist sub-agents handling execution.
The reason it works is change management basically disappears. Your team already lives in Slack. You're just adding agents to the room they're already in.
You NEED to start building yours now. In a year this will stop being an advantage and will become table stakes.


Owen Lawlor retweeted

AMD CEO Lisa Su just killed Nvidia’s $4,000 AI box with a $1,499 lunchbox.
She walked on stage, held it in one hand, and ran a 235 billion parameter model live. No data center. No cloud. No rented GPU.
The chip inside is something nobody saw coming. AMD’s Ryzen AI Max+ 395 is the first x86 silicon where CPU and GPU share the same 128GB of memory. That single trick lets a desktop run models that used to need a server rack.
Out of those 128GB, Linux hands the GPU 110GB to play with. For context, an RTX 5090 gives you 32GB. A 4090 gives you 24. This box gives you more than three times either of them, in a chassis the size of a thick paperback.
The benchmark that broke the room: this chip beat an Nvidia RTX 5080 by more than 3x on DeepSeek R1 inference. A $1,499 lunchbox outrunning a $1,000 discrete graphics card on a real AI workload. Nvidia spent a decade convincing the world you needed their hardware for serious AI. AMD just put that on a desk for half the price.
Here is what nobody is telling you. A heavy AI user right now pays $200 for Claude Code Max, $200 for ChatGPT Pro, $20 for Cursor, $20 for Gemini. That is $5,280 a year leaving your account. The box pays itself off in 9 months and then runs free for the rest of its life.
Install Ollama. Pull Qwen3 235B. Point Claude Code at localhost. Same interface you already use, except now nothing leaves your machine, nothing costs per request, and no company throttles your usage at 3am when you finally have time to build.
This is the moment every AI subscription becomes optional. Lawyers stop fearing OpenAI leaks. Developers stop watching the token meter. Founders stop renting H100s for prototypes that never ship because the bill scared them.
The first thousand people to figure this out will own the next two years of private AI consulting.
Save this, and read the full breakdown article below you are watching the next shift hit before everyone else does.


Readers added context they thought people might want to know
This is a $4,000 machine, a far cry from the $1,500 price point hallucinated in the original post.
microcenter.com/product/711962…
hypebeast.com/2026/5/amd-ryz…
Owen Lawlor retweeted

Karpathy said something you'll regret ignoring:
"Remove yourself as the bottleneck. Maximize your leverage. Put in very few tokens, and a huge amount of stuff happens on your behalf."
Loop engineering is the exact thing that does that.
In a hand-run session, the operator handles two things:
- deciding what the agent runs next
- and checking its output before the next step
Both are manual, and both decide how far the agent gets on its own without the operator.
Loop engineering moves both steps into the system.
A core operating structure surrounds the loop, and the diagram below depicts it.
- A schedule decides what to run
- Loop is the maker that produces the work
- A separate checker agent grades the output
- A file on disk holds the state they both read.
The loop runs until either done, max iterations, or an exhausted budget.
Here are some practical engineering considerations:
1) A model grading its own output justifies what it already did instead of catching where it failed.
That's why a separate checker's findings return to the maker as the next instruction. And the cycle repeats until the checker finds nothing left to fix.
2) A loop with no stop condition burns tokens, and the cost climbs fast once sub-agents and long runs add up.
That's why the exit must be set before the loop runs, not while it is running.
A simple exit could be:
↳ fix only the major issues, run one final pass, and stop after two loops, with "all tests pass and lint clean" as the rule that ends it.
3) State has to live on disk, not in context.
The model forgets everything between runs, so an MD file or a knowledge graph holds what is done and what is still open.
Each run reads it and writes back to it, which lets a loop pick up again after days.
4) The lower the verification bar, the safer the loop.
Boring, repetitive checks like a stale version string or a missing test are trivial to verify, so a loop runs them with little risk while the operator is away.
Judgment-heavy work is loopable too, but only as far as the checker can confirm the result.
Let's look at how an unattended loop fails in two ways.
1) It reports done when nothing is actually verified.
The separate checker exists to prevent it, but it merges code faster than anyone reads it, so over weeks, the team stops understanding its own codebase while every check stays green.
Green tests say the code passed the tests, not that anyone knows what shipped. Someone still has to read what the loop merges.
2) The checker keeps a running loop honest, but it only catches failures inside a run.
The harness around the loop, like the prompts, tools, and checks wrapped around the model, still drifts and breaks in production as models change.
That repair loop is usually run by hand based on observability traces.
My co-founder wrote a detailed walkthrough (with code) on making that harness repair itself, where a failing trace gets diagnosed, the fix is verified against the exact input that failed, and the failure is locked as a regression test so it cannot recur.
Read it below.


Owen Lawlor retweeted
Hadamard thought in image space

World Labs CEO Dr. Fei-Fei Li: "The world is not made of words."
"Language models have given machines an extraordinary command of concepts, vocabulary, and reasoning, but the physical world, virtual or real, runs on a different substrate."
"Where language models learn the statistical structure of text, world models learn the statistical structure of space and time: how light falls on a surface, how a garden looks from an angle no camera has captured, how objects respond to force and follow the laws of physics."
"Language gave machines a way to talk about that world. World models are how machines will finally come to understand, imagine, reason and interact with it."
Full piece: drfeifei.substack.com/p/a-fu…
Owen Lawlor retweeted

Today I’m launching AI IQ — frontier AI models, scored on the human IQ scale.
Instead of endless leaderboard tables, AI IQ shows:
• Where models land on the IQ bell curve
• How frontier IQ is changing over time
• How models compare on IQ and EQ
• What intelligence costs in practice
GPT-5.5, Claude Opus 4.7, Gemini 3.1, Grok 4.3, Kimi K2.6, Qwen3.6, DeepSeek V4, Muse Spark, and more.
Link in the first reply. Curious which chart surprises you most.


Owen Lawlor retweeted

I had a chance to interview @jack on Long Strange Trip and then sit in on his Q&A with a bunch of Sequoia founders yesterday. Here's my take followed by my takeaways.
Almost all of us are running a derivative of the playbook laid out in Andy Grove's "High Output Management" book that has been lightly edited down through the generations. Jack's set of ideas is a stark departure from that playbook. It reminds me of the shift I went through at the start of my career (pre web - yes, I'm that old!) to "digital transformation," but this is a much bigger, harder shift.
Some of my CEO friends have pushed back on these ideas saying something to the effect that Jack isn't a great CEO so we shouldn't listen to him. First, I'm not sure if that is true, but even if it is true, he is an undeniable innovator and first principles thinker applying that thinking here to org design, not just product design. Second, @brian_armstrong, a consensus great CEO is running something that sounds VERY similar to this playbook as well as almost every startup created in the last 18 months. Third, the first quarter Jack printed after putting this in place was a banger. ...To that end, I think we should all call this new playbook, "Dorsey Mode" after the guy who stuck his neck out.
If you want to run Dorsey Mode, a lot of things fall out of it that fall out of it:
1. Strategy - Planning cycles are out the window because the speed increases too much. All those 1 way doors you were procrastinating now look like 2 way doors.
2. Distribution - Given how much easier it is going to get to build products, competition and customer confusion will reign. In this new world, distribution is king. Companies with truly creative distribution strategies (rare!) will gain advantage. Also, long live ye olde enterprise sales.
3. Interviewing - All of the startups I work with have changed their interviewing process. Many have a case with a hard ai problem to solve embedded in it or at least have the prospective employee open their laptop and show them something interesting they built with ai. 4. Profile - There was a split in my group of CEOs at the Q&A -- some were learning hard into pilled jr engineers and some were leaning hard into very senior engineers. It roughly seems like the older companies with more code like Meta and HubSpot, are leaning harder into the very senior engineering types. ...Everyone seems keen to hire "curious" types not afraid to go very deep down rabbit holes.
5. Org shape - Triangle shaped org charts are like democracy, its the least bad system we've got. The biggest problem with triangles is that they get worse with size. The new org chart, in theory, is circular with the world model in the middle and very small teams surrounding it. Very few pure managers in the middle anymore. This seems "early," but directionally right to me.
6. Compensation - The difference between a middling employee and a top one is getting much wider which will necessitate a net new pay scale with a much higher standard deviation.
7. Titles - Jack got rid of them and is trying to focus everyone on the work as opposed to the level. As someone who tried this earlier in my career at HubSpot, I'm a little skeptical of this one, but the meta point of trying to focus people on what they "lead" versus who they "manage" is a good one that I hope sticks.
8 Decisions - Almost all decisions these days are made by carbon based life forms. Dorsey Mode turns an increasing amount of decisions over to the system.
9. IT - This is will totally change as their primary function will be to building the scaffolding for the world model and enable the company to keep feeding it the context and taste it will need to improve. EVERYTHING needs to be "legible" (I hate that I'm using that overused word, but it works) ...Btw, an early sign that a company is in Dorsey Mode is when they record every meeting, including the one on one's, cleverly stripping out some HR bits and centralizing them for use by the model. Btw, Ray Dalio had it right, but was just too early.
10. Slop - As more non-technical people build more things, there will be more slop. I didn't grok Jack's answer to this and I'm not sure the answer myself, but Dorsey Mode companies will need to figure out a system to reign in the badly designed systems.
11. Agency - This another word I cringe at using b/c it is so overused, but hiring folks with high agency that are self motivated will be key. The tricky part is that the beef with the current generation is that they are less like this than their predecessors.
12. CEO - This isn't something that will bubble up. The CEO needs to run hard at it and push it down hard and expect to get pushback from laggards. Jack spends 3 hours every morning building hard things with the new tools. ...AI isn't something that lends itself well to learning by reading or watching a video, so CEOs are running hackathons, show & tell's, building days, office hours, and token leader boards. ...Btw, lots of companies are doing the leader board thing (including mine) -- I think this works until it doesn't!
13. Budgets - Budgets in a lot of software orgs are basically enumerated in headcount. The denomination goes back to dollars.
As Jack (and my cofounder @Dharmesh) likes to say, in some cases, it is a lot riskier not to take a risk and this is one of those cases.


Owen Lawlor retweeted

Central Park is great, but it takes up a lot of space and isn’t utilized to its full potential.
That’s why I worked with McKinsey on a plan to make it a state of the art data center, complemented by rooftop parking and nuclear power.
We can still build beautiful things.

Owen Lawlor retweeted

Introducing SubQ - a major breakthrough in LLM intelligence.
It is the first model built on a fully sub-quadratic sparse-attention architecture (SSA),
And the first frontier model with a 12 million token context window which is:
- 52x faster than FlashAttention at 1MM tokens
- Less than 5% the cost of Opus
Transformer-based LLMs waste compute by processing every possible relationship between words (standard attention).
Only a small fraction actually matter.
@subquadratic finds and focuses only on the ones that do.
That's nearly 1,000x less compute and a new way for LLMs to scale.