


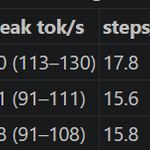



Qwen3.8-Flash-Next solo (TP=1) up to 130 tok/s ‼️
Same recipe involves 4 different quants all up for your taste.
🚀 If you prefer speed go for INT4.
🧠 If you prefer quality go for Nvidia FP4-local
⚖️ Middle Hybrid48 or Uncensored


Qwen3.8-Flash-Next from Nvidia (FP4-Local)
🚀 Peak up ~30%
🏭 Average up ~10%
💻 TTFT down ~10 times
Recipe includes FP4 / Int4 / Hybrid48 / Uncensored
⚡️ github.com/myllmbox/qwen38-f…

Qwen3.8-Flash-Next from Nvidia (FP4-Local)
🚀 Peak up ~30%
🏭 Average up ~10%
💻 TTFT down ~10 times
Recipe includes FP4 / Int4 / Hybrid48 / Uncensored
⚡️ github.com/myllmbox/qwen38-f…
Qwen3.8-Flash-Next from Nvidia (FP4-Local)
Same amazing speed and better quality‼️
🧠 KV - 1.66m ‼️+ YaRN
🚀 Peak c=1 @ 82 tok/s
🏭 Peak c=16 @ 297 tok/s
Latest 0.32.0 vLLM
⚡️ github.com/myllmbox/qwen38-f…

GLM-5.3-Flash from Nvidia (FP4-Local)
🚀 Peak up ~20%
🏭 Average up ~5%
🧠 KV up ~10%
⚙️ Prefill up ~25%
🪑 Concurrency up ~30%
💻 TTFT down ~10 times ‼️
⚡️ github.com/myllmbox/glm53-fl…

GLM-5.3-Flash from Nvidia (FP4-Local)
🚀 Peak c=1 @ 69 tok/s
📊 Average c=1 @ 42 tok/s
Most important thing quality ‼️
In our visual tests it scored 11.5 out of 12 ‼️
github.com/myllmbox/glm53-fl…

It although has recipe for @aldozampatti customized int4. Measurements are still going on on this quant. Potentially some more optimizations will land on it.
Both quants boot in ~5min.


Qwen3.8-Flash-Next kits v5.3.1, solo + two-Spark cluster
First token on a cached 200k context: 0.67 s on one Spark, 0.95 s on two (was 4.1 s).
⚡️ github.com/myllmbox/qwen38-f…
⚡️ github.com/myllmbox/qwen38-f…

Hard choice ‼️
Bit lobotomized deepseek or healthy glm ⁉️
@MiaAI_lab is throwing another glove for us to step up 😉
Sped is on Mia side quality is bit not. So what is your choice? Nvidia or Mia? That's is the question
More and more i get to SDD I start to raise more and more questions. How long each iteration should have? In general practice how many iterations agents need to finish a task? I talk about implementation / qa / fix cycle. As recently what i noticed it's about 6-7 cycles for average task.
Looks like next step in AI evolution.

Introducing Flint, @Recursive_SI’s first model: a fast local coding model built with our automated research system, the Eureka Machine.
• Best-in-class fast local coding
• Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark
• Built from scratch in under 4 months
Private, unmetered intelligence on your own machine. Open weights available now on @huggingface, run it locally on your favorite framework or try it for free on @opencode or @pidotdev.
Qwen3.8-Flash-Next (tp=2) from Nvidia (FP4-Local)
Performance is up ~20%-30% comparing to TP=1.
🧠 KV - 4.18m ‼️+ YaRN
🚀 Peak c=1 @ 92 tok/s
🏭 Peak c=64 @ 834 tok/s
Latest 0.32.0 vLLM
⚡️ github.com/myllmbox/qwen38-f…

Qwen3.8-Flash-Next from Nvidia (FP4-Local)
Same amazing speed and better quality‼️
🧠 KV - 1.66m ‼️+ YaRN
🚀 Peak c=1 @ 82 tok/s
🏭 Peak c=16 @ 297 tok/s
Latest 0.32.0 vLLM
⚡️ github.com/myllmbox/qwen38-f…
Fun notice while making comparisons looks like good quants maintain quality of 9 out of 12 that applied to @NVIDIAAI / @aldozampatti / @ViC305 . And most interesting thing @ViC305 managed to make smallest one with same quality ‼️
Latest Nvidia FP4-Local quants are just amazing 🥰
So what to chose?
Qwen3.8-Flash-Next or GLM-5.3-Flash
We compared them so you could take a look at the differences and make your choice 😉
⚡️ myllmbox.com/?a=mbx-v53&b=mb…
Qwen3.8-Flash-Next from Nvidia (FP4-Local)
Same amazing speed and better quality‼️
🧠 KV - 1.66m ‼️+ YaRN
🚀 Peak c=1 @ 82 tok/s
🏭 Peak c=16 @ 297 tok/s
Latest 0.32.0 vLLM
⚡️ github.com/myllmbox/qwen38-f…
GLM here xitter.cf/vr8vr8/status/21121750…
GLM-5.3-Flash from Nvidia (FP4-Local)
🚀 Peak c=1 @ 69 tok/s
📊 Average c=1 @ 42 tok/s
Most important thing quality ‼️
In our visual tests it scored 11.5 out of 12 ‼️
github.com/myllmbox/glm53-fl…