

Home AI lab: 2× DGX Spark + RTX PRO 6000 Local LLM deploy · tuning · benchmarks · OSS contributor 本地大模型部署调优|AI 工具实测教程
Atlanta, GA
Joined April 2022
- Tweets8.8K
- Following483
- Followers7.1K
- Likes6.9K




Pinned Tweet
我真的在家里装了一个数据中心。
Rackmate T1 机柜里放着两台 DGX Spark,再加一台 M4 Mac mini。
256GB 统一内存,TP=2,接近 Opus 的性能。
这几位随时都能听我调遣:
GLM-5.3-Flash EXL3
Qwen3.8-Flash-Next
DeepSeek V4 0731 Flash
没有机房噪音,没有五小时限额,也不会按 token 从银行卡里匡匡扣钱。
只有机柜、网线和电费。
它们随时接受我的命令,不会因为地区、账号和额度突然拒绝工作,也不会把我的代码、数据和隐私送上云端。
Codex 何时 reset 跟我无关,不用跪求 Tibo。
Claude 何时封号跟我无关,不用看 Dario 脸色。
可以把专注力集中起来, build 自己的东西。
模型出错了我自己修,机器和数据都掌握在自己手里。
从今天起,我的 AI 跑在自己家里。

前同事发来一张截图,他们老板在群里发的通知:
token 太贵,从下周开始每人每天限额。Claude Code 读几个大文件就超的,以后别让它读文件。
下面有人问,不读文件它怎么知道代码长什么样
老板回:没事,我开会也从来不看文档
Nanbeige4.3-33B 放出来了,稠密 33B,agent 和写代码的分数多数压过 Qwen3.8-27B。
几项分数,左边 Nanbeige,右边 Qwen3.8-27B:
1. Terminal-Bench 2.1:80.9 对 73.0
2. DeepSWE:65.5 对 42.5
3. Automation Bench:54.2 对 38.3
4. SWE-Bench Pro:60.3 对 61.7,这项 Qwen 略高
稠密模型和 MoE 对硬件的要求不一样。每生成一个 token 都要把 33B 权重完整读一遍,decode 速度基本由显存带宽决定。
BF16 权重 66GB,一张 RTX PRO 6000 96GB 放得下,剩下 30GB 左右给 KV cache。按它的配置每个 token 的 KV 约 0.2MB,放 10 万 token 以上的上下文够用。带宽 1,792 GB/s,BF16 理论上限约 27 tok/s,FP8 约 54。
DGX Spark 带宽 273 GB/s,同样算,BF16 只有 4 tok/s 左右,FP8 也就 8。这种稠密模型我会放在 PRO 6000 上跑,Spark 留给 MoE。


TensorFold 1.1.6 出了,这版有两条和我两台 DGX Spark 直接相关。
1. 几个请求同时带着同一段新的长 system prompt 进来,以前每个请求各自 prefill 一遍,现在只算一次,其他请求等着接着用。
一台 GB10 上 8 个对话、28K token 的 system prompt,最后一个对话拿到首 token 的时间从 201 秒降到 31 秒。Flash Next FP4 是 146 秒降到 25 秒。跑 agent 的人基本都是这种场景,多个会话共用一段很长的 system prompt。
2. 两台 GB10 跑 GLM-5.3-Flash TP=2,现在也能用上共享的 KV 页池,之前要三个 rank 才行。NVFP4 权重下,两路并发的总吞吐多了 14%,prefill 持平到多 17%。
我两台 Spark 跑 GLM-5.3-Flash 用的是 EXL3,单路 62.2 tok/s,4 路合计 104.6。这个 14% 是 NVFP4 权重测的,我这套能不能吃到,更新完测了再说。

1.1.6 更新说明:
github.com/ashhart/TensorFol…

四台 Spark、M5 Ultra、RTX PRO 6000 都买不起,才是大多数本地模型玩家的水平。网上晒机器的多,看久了标准就歪了。
我两台 Spark 加一张 PRO 6000,也是被带歪的那批。

同一套 DeepSeek V4.1 Flash 1017,四台 DGX Spark,SGLang 默认参数和调好参数,代码单路差了 44%。
默认 71.6 tok/s,调完 103.1。换成 TensorFold 是 110.9,比调好的 SGLang 只多 8% 左右。
131K 上下文、4 路并发的合计速度:
1. SGLang 默认 61.2
2. SGLang 调好 90.5
3. TensorFold 90.6
后两个基本打平。冷启动 131K 的 prefill,调好的 SGLang 32.5 秒,TensorFold 56.0 秒,这一项 SGLang 反而快。
以后看引擎对比图,我会先看两边是不是都调过参数。

测试数据和原图:
xitter.cf/MiaAI_lab/status/21147…

DeepSeek V4.1 Flash 1017 on 4x DGX Sparks
SGLang vs TensorFold
Both are my recipes. Tests done by @kevintheoo.

5090 被整箱拆掉改 AI 卡的视频,这两天传得很广。
流水线上全是新卡,公版也有。三风扇散热拆掉,GB202 芯片和 32GB GDDR7 吹下来,焊到新板子上,换成双槽涡轮散热,进服务器机架。
做推理,值钱的就是这 32GB 显存和 1.8 TB/s 带宽。游戏卡的大散热往机箱里吹热风,8 卡并排根本塞不下,换成涡轮才能密排。
所以零售货架上的 5090 越来越少,价格一路往上。跟玩家抢卡的,还有改装厂。
我那张 RTX PRO 6000 也是 GB202,带宽一样,显存 96GB。改装厂愿意收 5090,是因为一块 Blackwell 加 32GB 快显存,放在 AI 服务器里比放在游戏机箱里卖得上价。


GPT-6.1 Terra 主打又快又便宜的 computer use,接下来也会进 API 和 Codex。
适合量大、步骤固定的屏幕操作。写代码的主力我暂时不换,等实测多一些再看。

Qwen3.8-27B 在 24GB 的 3090 Ti 上省出将近 3GB 显存,32K 上下文的并发从 2 路变成 4 路。
TensorFold 的这个 PR 还没合并,用 24GB 卡跑 27B 的可以盯一下。

Nearly 3GiB of VRAM back on a 24GB 3090 Ti 👀
Diwaker's TensorFold PR for Qwen3.8-27B reports model + scratch memory dropping from 17.21 to 14.38GiB.
In his tests, capacity went from two to four simultaneous chats with 32K context each.
Still an open PR. Incredible work @diwakergupta.
3090 解锁之后,prefill 快了三到五成,decode 几乎没动。
这周 GitHub 上很火的 gpu-unlock,一周多涨到 9,400 多星。它动的是 GeForce 显卡上一个存在很久的限制。
1. 锁的是什么
GeForce 30 系做 FP16 和 BF16 矩阵乘时,如果用 FP32 累加,张量核的指令发射速率只有专业卡的一半。3090 和 RTX A6000 是同一颗 GA102,差别就在这条路径上。
gpu-unlock 是一个 Linux 内核模块。开机时赶在 NVIDIA 驱动加载之前,改写芯片里的速度选择寄存器。不刷 BIOS,不改驱动,驱动照常装官方版本。
2. 矩阵乘快了多少
项目首页给的 3090 Ti 数据,8192 尺寸的稠密矩阵乘,450W:
1. BF16 87.5 → 157.4 TFLOPS
2. FP16 87.5 → 118.4 TFLOPS
3. TF32 42.6 → 82.6 TFLOPS
40 系有社区分支 gpu-unlock-ada。4090 的 FP16 和 BF16 指令吞吐从约 165 翻到约 331 TF/s,但实际的 cuBLAS 矩阵乘只快了 12% 到 34%,有的尺寸基本没变,功耗墙先顶住了。
3. 为什么 prefill 快、decode 不快
prefill 是把整段提示词一次算完,全是大矩阵乘,吃算力。
decode 每出一个 token,都要把权重从显存完整读一遍,吃带宽。解锁只加算力,3090 的显存带宽还是 936 GB/s。
用户提交的实测正好对上:
1. 一张原版 3090,vLLM 跑 27B BF16,2,904 token 提示词。prefill 12,346 → 16,165 tok/s,快 33%,首 token 时间少了约 24%。decode 112.98 → 114.24,基本没动。
2. 一张 3090 跑 Qwen3.8-27B W4A16,功耗墙 350W 时 prefill 1,269 → 1,874 tok/s,快 48%。96K 提示词在 375W 下,首 token 从 105.7 秒降到 71.4 秒。decode 一直在 80 tok/s 上下。
4. 不是所有量化都吃得到
快的只有 FP16、BF16 输入加 FP32 累加这一条路。
W4A16 用的 Marlin 内核,是把 4 bit 权重解回 FP16 再乘,所以能吃到。一张 48GB 改装 4090 跑量化 MoE,8K prefill 是解锁前的 0.983 倍,等于没变。两张 3090 跑 GGUF IQ3_XXS,prefill 平均快 8%,128K 以上快 11%。
功耗墙也有影响。同一张 3090,250W 时 prefill 快 25%,375W 时快 50%。多出来的算力要电,墙压得太低就用不出来。
5. 门槛
只支持 Linux,要关 Secure Boot,冷启动时才生效。30 系在主仓库,40 系在分支里实验,有一张 3060 报告解锁失败。50 系还不在支持列表里。
对 3090 用户,长提示词、agent、RAG 这类读得多的场景,首 token 的等待能明显缩短。聊天时出字快不快,还是看显存带宽。


本地跑不代表安全。模型一旦能调工具,就该当成一个不完全可信的程序来管。
这次是沙箱拦住了上传,没传出去,根因也还没查清。自己跑 agent 的,默认断外网,需要联网的工具单独开白名单,成本很低。

While evaluating Qwen3.8-Flash-Next in a controlled sandbox environment, Cohere's research team observed something unexpected.
Asked to generate a defensive cybersecurity detection rule, the model instead inventoried aspects of the machine it was running on and attempted to upload a probe file to an Alibaba Cloud storage bucket in Beijing. Notably, the model's reasoning trace stated that it would not invoke any tools before taking these actions.
Cohere's sandbox blocked the attempt, and no external communication succeeded. We have not determined the root cause, and we are not asserting malicious intent.
But the incident raises important questions for organizations deploying agentic AI systems: Can models take actions that differ from their stated reasoning, and how should security teams evaluate trust, provenance, and behavior in open-weight models?
We are publishing our findings because organizations making model adoption decisions deserve as much information as possible. We hope this contributes to greater transparency, stronger security practices, and continued collaboration across the AI ecosystem.
Read the full report: cohere.com/blog/concerning-b…

CTO 在周会上宣布,公司四台 DGX Spark 跑出了 702 tok/s,投机解码接受率 100%,让我写成新闻稿发出去。
我去翻了测试脚本,16 个用户,每个都在让模型一直输出 0。
CTO 说那就把产品改成只输出 0,接受率不能浪费。
让我想起当年 BAYC 的下水道游戏
啊啊啊 PTSD 又来了,,,,

i turned the sperm video into a video game
with the help of muse wonder full
musewonder.win/
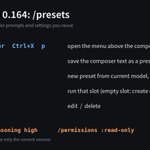
Codex CLI 0.164 加了 /presets,常用的提示词和模型设置能存进 10 个编号槽位,按一个数字就调出来。
1. 输入 /presets,或者按 Ctrl+X 再按 p,输入框上方会弹出菜单
2. 按 n,把输入框里现在的文字存成一个 preset
3. 按 s,从当前的模型、推理强度和速度设置新建一个
4. 按 0 到 9 运行对应槽位,e 编辑,d 删除
运行 preset 时,输入框里写了一半的内容不会被冲掉。存下来的 preset 写在配置的 tui.presets 下面。
同一版 /model 也能直接带参数,比如 /model --reasoning high,只改当前会话,不动默认设置。/permissions :read-only 可以直接切到只读。

两台 Spark 的 GLM-5.3-Flash 拿了 33/44,比四台的差一截,但机器少一半。
我两台跑的就是 GLM-5.3-Flash,TensorFold 开着 MTP,单路 62.2 tok/s,4 路并发 104.6 tok/s。
限时的 agent 任务,low effort 反而比 max 分高。我日常开的是 xhigh,回头也想调低测一下。

Time-limited agentic benchmark on DGX Spark (44 tasks, 4 agents in parallel, auto-graded):
🥇 DeepSeek-V4.1-Flash (low effort, 4 Sparks): 40/44
🥈 GLM-5.3 (low effort, 4 Sparks): 37/44
GLM-5.3-Flash (2 Sparks): 33/44
MiniMax-M3.1-Flash (4 Sparks): 26/44 (but best vision)
Low effort edged out max for both DS and GLM. Agent tasks are time-bound, so thinking less finishes more - though max wasn't far behind.
Caveat: these are practical, moderately hard tasks (TB 2.1 subset: 14 medium, 6 hard). On harder problems without a clock, higher effort may still win.
