


vivi retweeted
I GAVE 3 CLAUDE FABLE 5.2 AGENTS ONE NIGHT AND $150 IN TOKENS TO BUILD ME A TRADING TERMINAL FROM AN EMPTY FOLDER. I went to bed at 11 PM. At 6:52 AM there was a new app in my Dock, 212 of 212 tests green, a token bill for $146.30, and the $300 I left in it had turned into $1,912
The folder had one file in it. rules.md, three lines:
"the agent that writes the code never checks it"
"nothing touches real money until every test passes"
"never more than 10% of the balance on one trade"
Who did what:
Architect wrote the plan at 11:04 PM. 9 panels, 4 price feeds, one order button. After that it only said yes or no.
Builder wrote 63 files and rewrote the order book panel 4 times.
Breaker had one job: break everything. It found 38 bugs. At 2:17 AM it fed the terminal a fake 38% price spike and the stop-loss didn't fire. Builder fixed it by 2:28.
At 4:06 AM the last test went green and Architect switched it from paper to my real $300.
19 trades by morning, 15 green. Best one: $GOAT, +$412.40.
7 hr 52 min. $146.30 in tokens. $300 to $1,912.

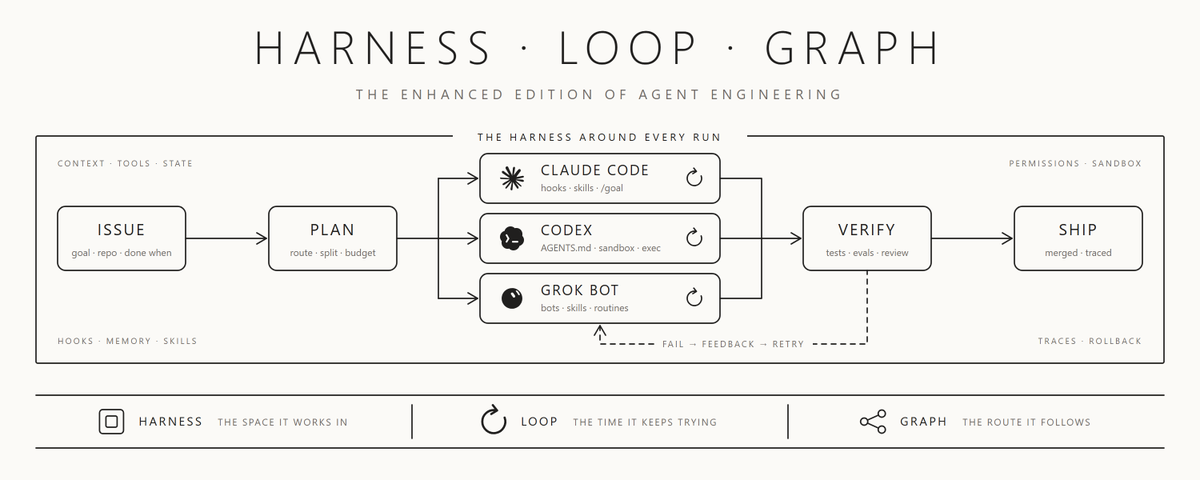
I GAVE 3 CLAUDE FABLE 5.2 AGENTS ONE NIGHT AND $150 IN TOKENS TO BUILD ME A TRADING TERMINAL FROM AN EMPTY FOLDER. I went to bed at 11 PM. At 6:52 AM there was a new app in my Dock, 212 of 212 tests green, a token bill for $146.30, and the $300 I left in it had turned into $1,912
The folder had one file in it. rules.md, three lines:
"the agent that writes the code never checks it"
"nothing touches real money until every test passes"
"never more than 10% of the balance on one trade"
Who did what:
Architect wrote the plan at 11:04 PM. 9 panels, 4 price feeds, one order button. After that it only said yes or no.
Builder wrote 63 files and rewrote the order book panel 4 times.
Breaker had one job: break everything. It found 38 bugs. At 2:17 AM it fed the terminal a fake 38% price spike and the stop-loss didn't fire. Builder fixed it by 2:28.
At 4:06 AM the last test went green and Architect switched it from paper to my real $300.
19 trades by morning, 15 green. Best one: $GOAT, +$412.40.
7 hr 52 min. $146.30 in tokens. $300 to $1,912.
vivi retweeted

my Grok Bot crossed $5,000 the same second the Cybertruck launched
the truck needed 10.87 seconds to beat a BMW M4
the bot needed 30 minutes
$200 → $5,384.62
3:14pm. the stream on my mac: Cybertruck 845 hp vs BMW M4 503 hp, race in 30:06
i had $200 and 30 minutes
same minute my girl texts: "babe the airwrap is back in stock"
and: "$599 tho"
so i opened a terminal and typed one line:
grok_bot run --budget 200
5 AI agents came online, each built on free open-source code from GitHub. my pit crew:
→ SMART$ is the spotter: when the best wallets pile into one coin, it follows them in
→ SNIPER is the launch: in on brand new coins 0.4 seconds after they go live
→ ROUTER picks the racing line, the lowest fee on every entry
→ TRADER does the pit stops: banks the profit and gets out
→ GUARD is the brakes. kills scam coins, cuts any trade that turns red
Grok Bot is the crew chief. it calls every move
stop-loss on each trade, withdraw anytime
i hit start and took my hands off the keyboard
my mac's clock:
3:24pm $500
3:31pm $1,000
3:38pm $2,000
3:41pm $3,000
3:44pm $4,000, both cars rolling to the line
staged. yellow lights. chat counting down
3, 2, 1, green
the Cybertruck launches. same second, SMART$ catches NITRO for +$617.25
$5,038.40
CYBERTRUCK WINS by 0.44 seconds. 10.87 at 127 mph vs 11.31 at 124
chat: "GOOOOO" "THE TRUCK" "ELON"
by the replay my screen said $5,384.62
one more line:
grok_bot send --to mia.sol
$600 "for the airwrap"
her: "WAIT"
her: "$600?? for the airwrap??"
me: "go get it baby"
her: "ILYYY"
the bot never stopped. $4,955.17 when the video ends
30 minutes in numbers:
→ $200 → $5,384.62
→ 56 trades, 47 green
→ best: NITRO +$617.25, on the green light
→ worst: DRIFT -$96.40
→ trades i touched: 0
honest part: 9 trades went red, and GUARD closed all 9 early. one session is not a salary. dry-run it first, then only put in money you could lose tonight
want your own pit crew? give Grok Bot this:
"set up a Solana memecoin pit crew with 5 agents and a $200 budget. spotter (SMART$): copy a coin once 3 or more top wallets are in. launch (SNIPER): enter fresh launches within 1 second, only coins that pass the scam scan. racing line (ROUTER): pick the lowest-fee swap route. pit stop (TRADER): bank profits quickly. brakes (GUARD): scan every token for scams and exit any position that drops past the limit. grow bet size with the balance. dry-run first and keep a decision log"
repos: first reply ↓
would you have cashed out at $4,000 with the cars still on the line?
xitter.gq/savipww/status/2116923…


vivi retweeted

a breeder gave me until 9 tonight to send $1,200 for the last puppy in the litter
i had $150 and less than 7 hours
at 8:42pm i sent the $1,200 and named her Grok
because she literally paid for herself
$150 at 2:16pm. $4,617.29 at 8:41pm
2:14pm, the breeder:
"she's the last one left"
"$1,200 and she's yours"
"2 other families asked... need an answer by 9 tonight"
so i gave Grok Bot my $150 and set the session to end at 9:00pm. exactly her deadline. goal: $1,200
the screen even says it: i set the limits, and it can't withdraw a cent by itself
my 5 agents? dogs, obviously. each one is an open-source project on GitHub, free:
→ Corgi snipes brand new coins the second they launch
→ Pom copies the smartest wallets
→ Doxie does the buying and selling
→ Frenchie is security: sniffs out scams and closes any trade down 8%
→ Doodle is the brain and makes the final call
the pings started: "Corgi sold FLUFF +$10.81"
i put the phone on the charger and left them to it
5:28pm the $1,200 for her was already there
i didn't stop. the deadline was 9
7:30pm $2,000
8:21pm $3,000
8:38pm $4,000
8:41pm Corgi catches a coin called BISCUIT for +$161.40 and i'm at $4,617.29
yes. the best trade of the day was called BISCUIT
the afternoon in numbers:
→ $150 → $4,617.29
→ 176 trades, 148 green (84%)
→ best: BISCUIT +$161.40
→ worst: PUDDLE -$52.16
→ 6 hours 25 minutes, zero trades by me
honest part: 28 trades lost, and Frenchie closed every one of them early. try it with pretend money first, and never with money you'd cry about
8:42pm the breeder: "still want her? it's almost 9"
me: "sent $1,200 she's MINE"
breeder: "she's yours!! what's her name?"
me: "Grok"
breeder: "lol why Grok"
me: "she paid for herself"
$3,417.29 left. almost 3 more puppies
links to all 5 dogs below ↓
what would you name yours?
xitter.gq/x_insider4/status/2114…


vivi retweeted
11:47pm my bestie jess texts me "TULUM FLIGHTS ARE $650 RN 😭😭"
i had $100. i gave it to Grok Bot and slept on it
8:14am i sent her $1,300 for both seats and still had $2,828.62 left 😭
back to 11:47pm. she also sent "im booking tmrw morning ✈️" and "u coming or not??"
right above her texts sat a notification from Grok Bot: "your 5 agents are ready ✨ add $100 to start"
so i did. apple pay, face id, start. phone on the charger, me in bed
my 5 agents are a bunny, a bear, a kitty, a chick and a cloud. each one is a free GitHub repo with one job: new coins, scam checks, smart wallets, buying and selling, and the brain that makes the call
the guy in the article i'm quoting gave his desk a 7th agent, a judge, because at 2am a pretty chart could talk him into anything
same problem here. my fix was dumber
at 2am i was asleep
before it started, the app showed me 2 lines: "you set limits for every trade" and "can't withdraw funds on its own"
i don't trust a bot that can talk me into a buy. i trust one that can't take my money out
8:14am i read the night like a group chat i missed:
"stop-loss armed −8%"
"scam check · clean"
"smart money buying $BLING · Kitty copied in 0.4s"
11:48pm to 8:14am. 213 trades, 178 green, 35 red
the coin that pushed me past $4,000 was called mochi. +$127.22, caught by the bunny
the worst was kiwi, -$48.78, and the bear cut it before it got ugly
and no, it's not magic. 1 in 6 trades lost. try it on paper first and only with money you can lose
save this before your next girls trip 🫶
jess: "gm 😭 did u decide??"
me: "sent u $1,300 🫶 book us both ✈️"
jess: "WAIT WHAT 😭😭😭"
jess: "HOW"
me: "grok bot 💅"
jess: "SEND ME THE LINK RN"
jess, it's in the reply ↓
who's your jess?
xitter.gq/x_insider4/status/2114…
F*CK THE WINS. 97 OF 124 LEADS GOT KILLED, AND 78 OF THEM HAD ALREADY PASSED EVERY OTHER CHECK
59 of those 78 were dead within 24 hours.
the seat doing the killing can't talk. no paragraphs, no recommendation, nothing you can argue with. it answers four closed questions and hands back a number.
here are three real leads going through it:
→ #047: organic .71, late no .82, exit risk 2. all four true, staged, filled, trailed out
→ #052: late = yes at .88. killed, logged with the answer that killed it
→ #058: watch, ask again in 30 minutes, second watch, killed
a second watch is a pass. no answer at all is a pass.
the gate doesn't move:
action buy at 0.70 or higher. organic yes at 0.65 or higher. late no. exit risk 3 or lower. all four or nothing gets bought.
confidence decides if, never how much. a 0.92 and a 0.71 get the same money.
every sunday it gets graded. the 0.80 bucket has to win about 80% of the time. if it doesn't, raise the gate instead of arguing with the table.
54% win rate on day 1. 69% by day 5, across 43 trades.
one honest line: the balance in my clip is simulated. 124 scanned, 97 killed, 78, 59, 43, the thresholds, all of it is the author's own bank over his own weeks. memecoins are the riskiest thing you can trade. paper the gate first, log every verdict, run the sunday check before you trust a single number. NFA.
$500 → $11,101 in 5 days.
my Grok memecoin desk got a 7th seat: Jev. it can't talk. it answers 4 closed questions with probabilities, and nothing gets bought below the gate.
full setup below. save it.
14
35
525
F*CK IT, I GAVE MY BOT 30 DAYS AND ZERO PERMISSION TO SEND ANYTHING
day 2: it passed 52% of its own checks and I was fixing things by hand 14 times that week.
day 29: 100% pass rate, 180 runs, 165 passed, one repair.
it still sent 0 emails without me.
7 seats, and the exact line each one runs on:
→ CHIEF: "Turn this mission into a contract: outcome, inputs, output, definition of done, constraints, approval gates, schedule. Do not start until the finish line is measurable"
→ RESEARCH: "Find 10 non-duplicate sources from the last 90 days. Give date, author, URL and the claim each one supports"
→ BUILDER: "Build only from verified inputs. If a field is missing, write missing. Never fill a gap with a guess"
→ REVIEWER: "Name the failed criterion, the exact paragraph, and which seat fixes it. Do not rewrite it yourself"
→ GATE: "Send, publish, buy, delete, contact anyone: ask me every time"
→ DISTRIB: "Stage it and stop"
→ AUDIT: "Log every step, every retry, every repair. Weekly receipt"
add the limits before you add a schedule:
max 50 items per run. max 2 retries. $0 spend without approval. 0 external actions without approval.
most of the damage is a permitted action repeated every run because a source page changed overnight.
autonomy goes up in levels. level 1 drafts and stages. level 2 stops before anything consequential. level 3 runs on a schedule. level 4 routes work to the other seats. five clean runs to move up, and you move back down the week repairs start piling up.
one honest line: the balance in my clip is a simulated number, not from the guide and not my account. the numbers worth copying are 42 researched, 10 drafted, 0 sent.
start tonight with a boring job: top 5 agent news every morning at 07:00, deduped, with sources.
then read how the full ladder works in the article below ↓


78 TOKENS PASSED EVERY CHECK ON THE DESK. THE 7TH BOT KILLED ALL 78. 59 WERE DEAD WITHIN 24 HOURS
the seventh seat can't talk. no paragraphs, no argument, nothing you can lean on.
six agents find pairs, check contracts, confirm smart money, stage orders, manage exits and run the thread. the seventh answers four closed questions and returns a probability for each.
// JUDGE, same four questions, every lead
organic: yes / no
late: yes / no
exit_risk: 1-5
action: buy / watch / pass
here's the gate:
▸ action = buy at 0.70 or higher
▸ organic = yes at 0.65 or higher
▸ late = no
▸ exit_risk 3 or lower
all four true or nothing gets bought. one false and the lead goes into the log with the answer that killed it.
confidence never changes position size. a 0.92 buy gets the same money as a 0.71 buy.
a model that writes can talk you into things. at 2am four confident paragraphs read the same on the token that goes to zero as on the one that doesn't.
every sunday it gets graded. group the buys into probability buckets, count how many closed green. if the 0.90 bucket doesn't beat the 0.70 bucket, raise the gate.
if it doesn't answer, the lead is a pass.
one honest warning: the $500 to $11,101 in five days is the author's bank and his thresholds. 43 trades, 69% win rate, memecoins. he says it himself, copy the shape and not the numbers. paper the gate first.
the seat that researches never signs. the seat that signs never gets an opinion.
YOU ARE PAYING SENIOR RATES TO RENAME FILES
the setup everyone is reposting is OpenAI Dots plus Claude Code as one dev team. the part actually worth stealing is smaller than that: which model gets the task first.
Sonnet 5.5 reads at $2 per million and writes at $10. Opus 5.5 is double on both.
~/project-x $ claude -p "Fix issue #381. Run the tests. Open a pull request." --model claude-sonnet-5-5
here's the split:
▸ Sonnet takes the first pass on everything, 2 tries maximum
▸ Opus gets it only when Sonnet is stuck, 1 try, and it plans instead of typing
▸ tests decide, not the model. 318 of 318 or the task is not done
▸ you approve the pull request, and nothing merges itself
on 1,000 tasks that is roughly $480 instead of $800 for the same work, because the expensive brain only wakes up for the 20% that earns it.
the part that makes this safe: the Dot never merges. it opens the issue, reads the result and writes you a summary. the branch, the commits and the test output all live in GitHub, so neither model has to remember anything.
by 08:00 there is a PR waiting with no database changes and your approval missing, not a commit you have to undo.
the benchmarks are closer than that price gap suggests. Sonnet beats Opus on Terminal-Bench 4.0, 70.6 to 66.4. Opus pulls ahead on the long messy ones, FrontierCode 54.4 to 46.2. that spread is the entire reason a router exists.
one honest warning: there is no connect button. OpenAI and Anthropic ship nothing that joins these two. you build the GitHub bridge yourself, and if your tests are weak you have only automated a bad merge faster.
8 hours of nothing becomes 9 tasks routed, fixed and green before you open the laptop.
save it, this is the cheapest senior engineer you will ever avoid hiring.

vivi retweeted
THIS IS THE CHEAPEST SECOND BRAIN YOU WILL EVER BUILD
no Obsidian, no Notion, no database. a handful of .md files on your disk and one index the agent reads before you type anything.
the index is CLAUDE.md in the root. Claude Code loads it into the system prompt at session start, so the map is already in its head.
~/brain $ mkdir notes people projects && touch CLAUDE.md
here's the split:
▸ notes/ holds one file per topic, named for the topic
▸ people/ holds one card per person, who they are and what you owe them
▸ projects/ holds status, where you stopped, the next step
▸ MEMORY.md, LEARNINGS.md and decisions.md sit in the root as the core, the lessons and the audit log
the rule that makes it work: one file, one topic. tax-policy.md, not notes.md. ivan-petrov.md, not note-12.md. lowercase and hyphens, always.
the part that makes it fast: nothing gets installed. these are text files. any editor, any agent, any machine, and they outlive whatever app you would have picked instead.
you ask "what did we decide on taxes?" and it goes map, then notes/tax-policy.md, then an answer with the file cited. ask about something you never wrote down and it tells you it is not in there.
that second one is the whole point. a clean structure is what lets it say "missing" instead of inventing a number.
you can pin a file with @MEMORY.md inside the map and it stays in focus every session. two files at most, or you are back to dumping everything into the prompt.
one honest warning: the map is the product, the folders are just storage. a sloppy CLAUDE.md gets you an agent that guesses, and it guesses confidently.
five minutes of folders tonight, filled as you go. no migration weekend.
save it, this is the cheapest memory your agent will ever have.


THIS IS THE CHEAPEST SECOND BRAIN YOU WILL EVER BUILD
no Obsidian, no Notion, no database. a handful of .md files on your disk and one index the agent reads before you type anything.
the index is CLAUDE.md in the root. Claude Code loads it into the system prompt at session start, so the map is already in its head.
~/brain $ mkdir notes people projects && touch CLAUDE.md
here's the split:
▸ notes/ holds one file per topic, named for the topic
▸ people/ holds one card per person, who they are and what you owe them
▸ projects/ holds status, where you stopped, the next step
▸ MEMORY.md, LEARNINGS.md and decisions.md sit in the root as the core, the lessons and the audit log
the rule that makes it work: one file, one topic. tax-policy.md, not notes.md. ivan-petrov.md, not note-12.md. lowercase and hyphens, always.
the part that makes it fast: nothing gets installed. these are text files. any editor, any agent, any machine, and they outlive whatever app you would have picked instead.
you ask "what did we decide on taxes?" and it goes map, then notes/tax-policy.md, then an answer with the file cited. ask about something you never wrote down and it tells you it is not in there.
that second one is the whole point. a clean structure is what lets it say "missing" instead of inventing a number.
you can pin a file with @MEMORY.md inside the map and it stays in focus every session. two files at most, or you are back to dumping everything into the prompt.
one honest warning: the map is the product, the folders are just storage. a sloppy CLAUDE.md gets you an agent that guesses, and it guesses confidently.
five minutes of folders tonight, filled as you go. no migration weekend.
save it, this is the cheapest memory your agent will ever have.
vivi retweeted
a rebuilt function matched the original byte for byte and was still wrong
the comparison tool lined up the instructions and never looked at the number they pointed to. the original checked player power against 128.0. the rebuild checked against 0.0. every byte matched, the meaning did not
the audit after it went through 1,548 floating-point references and found twelve more wrong ones, in five functions that had already been accepted
that is the part the install guides skip. the model reads, explains and rewrites. the check decides whether any of it is true, and the people doing this seriously have a name for the check. they call it the oracle.
doesn't matter if you're rebuilding a feature, porting a codebase or just letting an agent grade itself, the oracle is the whole job
the three kinds, and how to break them on purpose:
> byte oracle - compile your version, compare machine code. DX-Ball's audio balance helper: 3,205 test cases pass and all 63 compiled bytes reproduced. that is proven, not "looks right"
> behaviour oracle - same inputs into both, compare outputs. why Windows Calculator answers 220 to 200 + 10%, cross-checked against Microsoft's own published source with the exact version written down
> runtime oracle - build the whole thing and use it. the Chrome dino speed rule starts at 6, adds 0.001 per update, caps at 13, and they ran it: 10.0 after 4,000 updates, 13.0 after 10,000
> plant 3 failures before you trust a green run. one wrong constant, one swapped branch, one off-by-one. if any of them passes, the oracle is broken and every green result before it is suspect
> room A reads with REA and writes SPEC.md - behaviour, inputs, outputs, edge cases, unknowns. no code, no addresses, no names from the decompile
> room B is a fresh session in a separate folder that gets SPEC.md and nothing else. it never sees the analysis, which is the entire point of a clean room
> hold the builder to a measurable end: every case in the spec passes, all 3 planted failures rejected, nothing outside the folder touched, stop after 25 turns
the Adobe story everyone repeated is the proof. nobody decompiled anything. ArtCraft shipped twelve apps written from scratch in Rust, and FilmCraft's contributor rules forbid reading, disassembling or copying anything inside an Adobe bundle at all. you observe the behaviour by using the app. the people who rebuilt Adobe's workflow banned themselves from reading Adobe.
study the original, ship your own. an output is not a right, and reading a program gives you no claim on its code, its data or its name.
the board in my clip is a visual concept for software you own or may examine. the full guide, the two-room prompts and the planted-failure pack are below.


a rebuilt function matched the original byte for byte and was still wrong
the comparison tool lined up the instructions and never looked at the number they pointed to. the original checked player power against 128.0. the rebuild checked against 0.0. every byte matched, the meaning did not
the audit after it went through 1,548 floating-point references and found twelve more wrong ones, in five functions that had already been accepted
that is the part the install guides skip. the model reads, explains and rewrites. the check decides whether any of it is true, and the people doing this seriously have a name for the check. they call it the oracle.
doesn't matter if you're rebuilding a feature, porting a codebase or just letting an agent grade itself, the oracle is the whole job
the three kinds, and how to break them on purpose:
> byte oracle - compile your version, compare machine code. DX-Ball's audio balance helper: 3,205 test cases pass and all 63 compiled bytes reproduced. that is proven, not "looks right"
> behaviour oracle - same inputs into both, compare outputs. why Windows Calculator answers 220 to 200 + 10%, cross-checked against Microsoft's own published source with the exact version written down
> runtime oracle - build the whole thing and use it. the Chrome dino speed rule starts at 6, adds 0.001 per update, caps at 13, and they ran it: 10.0 after 4,000 updates, 13.0 after 10,000
> plant 3 failures before you trust a green run. one wrong constant, one swapped branch, one off-by-one. if any of them passes, the oracle is broken and every green result before it is suspect
> room A reads with REA and writes SPEC.md - behaviour, inputs, outputs, edge cases, unknowns. no code, no addresses, no names from the decompile
> room B is a fresh session in a separate folder that gets SPEC.md and nothing else. it never sees the analysis, which is the entire point of a clean room
> hold the builder to a measurable end: every case in the spec passes, all 3 planted failures rejected, nothing outside the folder touched, stop after 25 turns
the Adobe story everyone repeated is the proof. nobody decompiled anything. ArtCraft shipped twelve apps written from scratch in Rust, and FilmCraft's contributor rules forbid reading, disassembling or copying anything inside an Adobe bundle at all. you observe the behaviour by using the app. the people who rebuilt Adobe's workflow banned themselves from reading Adobe.
study the original, ship your own. an output is not a right, and reading a program gives you no claim on its code, its data or its name.
the board in my clip is a visual concept for software you own or may examine. the full guide, the two-room prompts and the planted-failure pack are below.
vivi retweeted
ask claude whether a trading rule works and you get an answer in 4 seconds
it has never seen the chart. it has never run the test. it is answering from memory, and a smarter model with no data is just a more convincing guess
the fix is not a better model. it is taking the grading away from the thing that had the idea
one chat window picks the idea, runs the test, grades its own work and forgets all of it when you close the tab. that is four jobs and zero separation. a desk splits them.
doesn't matter if you're testing strategies, research claims or anything you can be wrong about expensively, this shape is the point
the 5 roles:
> lead on Opus 5.5 turns the question into a plan and decides what runs next. it never grades its own output
> scout on Sonnet 5.5 checks the data before a single test runs - delisted companies included since 1998, fundamentals stamped by filing date instead of quarter end. survivorship and look-ahead bias are the two quiet ways a backtest lies to you
> sweeper on Sonnet 5.5 runs 20 configs from one prompt and returns every cell, failures included, so you can see whether the wins form a plateau or one lucky number
> skeptic on Opus 5.5 exists only to break what survived - held-out years, nearby settings, the worst drawdown year. the strongest model goes here on purpose, because generating ideas is cheap and killing bad ones is not
> librarian on Haiku 5.5 pulls from 175 documented strategies instead of from a feeling about what should work
> research.md logs every verdict before any summary, and NO EDGE gets logged and never retested without a new reason
> the split is by time, at 2015, never random. shuffling time leaks the future into the past
the honest half, because this is money and not a side project: the 200-day numbers in that course are the author's published run, gross of costs, so fees and slippage can erase a thin edge. backtests do not model taxes or slippage, the agents never place an order, and a beautiful equity curve marked NO EDGE is still NO EDGE. paper first, always.
the desk in my clip is a visual concept, not a live account. the course below has the agent files, the four team rules and the full setup.

ask claude whether a trading rule works and you get an answer in 4 seconds
it has never seen the chart. it has never run the test. it is answering from memory, and a smarter model with no data is just a more convincing guess
the fix is not a better model. it is taking the grading away from the thing that had the idea
one chat window picks the idea, runs the test, grades its own work and forgets all of it when you close the tab. that is four jobs and zero separation. a desk splits them.
doesn't matter if you're testing strategies, research claims or anything you can be wrong about expensively, this shape is the point
the 5 roles:
> lead on Opus 5.5 turns the question into a plan and decides what runs next. it never grades its own output
> scout on Sonnet 5.5 checks the data before a single test runs - delisted companies included since 1998, fundamentals stamped by filing date instead of quarter end. survivorship and look-ahead bias are the two quiet ways a backtest lies to you
> sweeper on Sonnet 5.5 runs 20 configs from one prompt and returns every cell, failures included, so you can see whether the wins form a plateau or one lucky number
> skeptic on Opus 5.5 exists only to break what survived - held-out years, nearby settings, the worst drawdown year. the strongest model goes here on purpose, because generating ideas is cheap and killing bad ones is not
> librarian on Haiku 5.5 pulls from 175 documented strategies instead of from a feeling about what should work
> research.md logs every verdict before any summary, and NO EDGE gets logged and never retested without a new reason
> the split is by time, at 2015, never random. shuffling time leaks the future into the past
the honest half, because this is money and not a side project: the 200-day numbers in that course are the author's published run, gross of costs, so fees and slippage can erase a thin edge. backtests do not model taxes or slippage, the agents never place an order, and a beautiful equity curve marked NO EDGE is still NO EDGE. paper first, always.
the desk in my clip is a visual concept, not a live account. the course below has the agent files, the four team rules and the full setup.
vivi retweeted
🚨 The software industry isn't ready for what's coming.
Imagine taking almost ANY software, understanding how it works, and building your own version with AI.
Sounds impossible?
Not anymore.
Meet REA (Reverse Engineer Anything) — one of the wildest open-source AI tools right now.
And when combined with Claude Code, things get absolutely insane.
Here's why everyone should be paying attention 🧵👇
01 / AI CAN NOW INVESTIGATE SOFTWARE
Previously, reverse engineering required serious technical knowledge, expensive tools, and countless hours.
Now AI agents can use REA to:
→ Analyze software architecture
→ Trace hidden functionality
→ Examine binaries and dependencies
→ Understand how complex features work
→ Collect evidence behind their findings
What used to be an extremely technical process is becoming accessible through natural language.
02 / FROM ANALYSIS TO REBUILDING
Here's where it gets interesting.
REA helps your AI agent understand how software behaves.
Claude Code can then turn those findings into an independent implementation.
The workflow is surprisingly simple:
🔍 Investigate the software
🧠 Extract its core functionality
📝 Generate a detailed specification
⚡ Build your own version
✅ Test, verify, and improve
All within an AI-powered development workflow.
03 / THE BIGGER PICTURE
Think about what this could mean.
→ Building alternatives to expensive software
→ Understanding complicated applications
→ Creating custom tools for personal workflows
→ Accelerating development dramatically
→ Making software research more accessible
And we're still in the early stages.
Of course, reverse engineering doesn't remove copyright, licensing, or other legal restrictions.
But here's the part most people are missing:
The real breakthrough isn't copying software.
It's giving AI the ability to understand existing systems and use that knowledge to build something new.
We're moving toward a world where understanding complex software no longer requires an entire team of specialists.
The barrier between having an idea and building a working product is getting smaller every day.
And tools like REA are pushing that transformation forward.
Closed-source software isn't disappearing overnight.
But the way we analyze, understand, and recreate functionality is changing forever.
REA + Claude Code is a combination worth watching.
The next generation of software development is going to look VERY different.
**Are we witnessing the beginnin

🚨 The software industry isn't ready for what's coming.
Imagine taking almost ANY software, understanding how it works, and building your own version with AI.
Sounds impossible?
Not anymore.
Meet REA (Reverse Engineer Anything) — one of the wildest open-source AI tools right now.
And when combined with Claude Code, things get absolutely insane.
Here's why everyone should be paying attention 🧵👇
01 / AI CAN NOW INVESTIGATE SOFTWARE
Previously, reverse engineering required serious technical knowledge, expensive tools, and countless hours.
Now AI agents can use REA to:
→ Analyze software architecture
→ Trace hidden functionality
→ Examine binaries and dependencies
→ Understand how complex features work
→ Collect evidence behind their findings
What used to be an extremely technical process is becoming accessible through natural language.
02 / FROM ANALYSIS TO REBUILDING
Here's where it gets interesting.
REA helps your AI agent understand how software behaves.
Claude Code can then turn those findings into an independent implementation.
The workflow is surprisingly simple:
🔍 Investigate the software
🧠 Extract its core functionality
📝 Generate a detailed specification
⚡ Build your own version
✅ Test, verify, and improve
All within an AI-powered development workflow.
03 / THE BIGGER PICTURE
Think about what this could mean.
→ Building alternatives to expensive software
→ Understanding complicated applications
→ Creating custom tools for personal workflows
→ Accelerating development dramatically
→ Making software research more accessible
And we're still in the early stages.
Of course, reverse engineering doesn't remove copyright, licensing, or other legal restrictions.
But here's the part most people are missing:
The real breakthrough isn't copying software.
It's giving AI the ability to understand existing systems and use that knowledge to build something new.
We're moving toward a world where understanding complex software no longer requires an entire team of specialists.
The barrier between having an idea and building a working product is getting smaller every day.
And tools like REA are pushing that transformation forward.
Closed-source software isn't disappearing overnight.
But the way we analyze, understand, and recreate functionality is changing forever.
REA + Claude Code is a combination worth watching.
The next generation of software development is going to look VERY different.
**Are we witnessing the beginnin
vivi retweeted
you don't need a bigger plan. 87,500 of the 100,000 tokens a task burns go to work your bot already did
yesterday's chat dragged into today, full pages read for one price, polling a source that never changed, and research rebuilt from scratch because nothing saved where it came from
seven fixes, and the one that matters most is the one that costs more, not less
doesn't matter if you're running research, monitoring or reporting on a schedule, audit before you pay for more capacity
the 7 fixes, with where the tokens go:
> 01 start from a file, not yesterday's thread. goal, decisions and next action in HANDOFF.md, under 400 words, then open a clean conversation. 28k to 1.5k
> 02 read what the task needs. pull the relevant passages first, keep the full original in sources/, open more only when missing context would change the answer. 22k to 3k
> 03 stop paying for "nothing changed". compare against the last snapshot before any analysis, and never let a failed check count as unchanged. 18k to 1k
> 04 give finished work an expiry rule. store checked_at and a refresh rule, reuse what is still valid, and keep the original verification date instead of relabelling old facts as new. 12k to 1k
> 05 one owner per assignment. one coordinator, separate output files, no source collected twice without a recorded reason. 10k to 0.5k
> 06 cap retries at 2. save progress at real boundaries, log the exact error, and never restart the four briefs that already passed because the fifth page would not load. 7k to 1.5k
> 07 make "done" mean usable. checklist before drafting, PASS FAIL UNKNOWN against evidence, one targeted fix pass, NEEDS REVIEW if a check still fails. 3k to 4k
read that last line again. verification is the only row that goes up, and it is the reason the other six are worth anything. a bot saying "verified" is not evidence.
the 10x is arithmetic, not a benchmark: 8x more assignments processed times 1.25x acceptance equals 70 accepted results instead of 7, on the same million tokens. the author says plainly that real usage stays unknown until a meter measures it, and the board in my clip is his table, not my run.
the full course, the copy-paste prompts and the 4 github tools are in the article below.

you don't need a bigger plan. 87,500 of the 100,000 tokens a task burns go to work your bot already did
yesterday's chat dragged into today, full pages read for one price, polling a source that never changed, and research rebuilt from scratch because nothing saved where it came from
seven fixes, and the one that matters most is the one that costs more, not less
doesn't matter if you're running research, monitoring or reporting on a schedule, audit before you pay for more capacity
the 7 fixes, with where the tokens go:
> 01 start from a file, not yesterday's thread. goal, decisions and next action in HANDOFF.md, under 400 words, then open a clean conversation. 28k to 1.5k
> 02 read what the task needs. pull the relevant passages first, keep the full original in sources/, open more only when missing context would change the answer. 22k to 3k
> 03 stop paying for "nothing changed". compare against the last snapshot before any analysis, and never let a failed check count as unchanged. 18k to 1k
> 04 give finished work an expiry rule. store checked_at and a refresh rule, reuse what is still valid, and keep the original verification date instead of relabelling old facts as new. 12k to 1k
> 05 one owner per assignment. one coordinator, separate output files, no source collected twice without a recorded reason. 10k to 0.5k
> 06 cap retries at 2. save progress at real boundaries, log the exact error, and never restart the four briefs that already passed because the fifth page would not load. 7k to 1.5k
> 07 make "done" mean usable. checklist before drafting, PASS FAIL UNKNOWN against evidence, one targeted fix pass, NEEDS REVIEW if a check still fails. 3k to 4k
read that last line again. verification is the only row that goes up, and it is the reason the other six are worth anything. a bot saying "verified" is not evidence.
the 10x is arithmetic, not a benchmark: 8x more assignments processed times 1.25x acceptance equals 70 accepted results instead of 7, on the same million tokens. the author says plainly that real usage stays unknown until a meter measures it, and the board in my clip is his table, not my run.
the full course, the copy-paste prompts and the 4 github tools are in the article below.
vivi retweeted
you do not prompt an employee. you brief one
and the brief that decides whether any of this works is 4 lines long, pasted once, before the first job
most people skip it and then wonder why the agent writes in a voice that isn't theirs, chases the wrong customers, and one day sends something it should have shown them first. that is not a model problem. nobody told it who it works for.
doesn't matter if you're handing off research, outreach or reporting, start here
the 4 lines:
> Me: your name and what you actually do, in one sentence a stranger would understand. not your title
> My customers: who buys from you and who doesn't. "dental clinics, independent, not chains" beats "small businesses"
> My voice: two lines you actually wrote. not an adjective. it copies rhythm from examples and ignores "professional but friendly"
> Never: contact anyone, post, or pay without my yes. this is the one that keeps the other three from becoming expensive
then the jobs, one a week:
> give each one a day and a time instead of remembering to ask. "every monday at 9:00, 25 new leads" and "every friday at 16:00, the week on one page"
> demand the artifact, not the answer. a spreadsheet with an empty approval column, a one-page pdf, a report ending in three lines of next week
> make it show receipts for every claim. in the clip: 240 read, 192 dropped, 48 kept, 12 claims each linked to a source and 0 invented
the graph in the clip is my own concept and every number on it is simulated, the backtest included. nothing on that screen is a result i'm claiming.
the guide below is a paid partnership built around one product, so the timings in it are the author's runs. the four-line brief and the one-job-a-week order cost nothing and work with whatever agent you already pay for.

