




Charlotte Xia retweeted

💡Ornith-1.5-DFlash
🤗 huggingface.co/collections/o…

Charlotte Xia retweeted

🚀 Physion Arc 1.0 — Anime Track is now live:
physionlabs.ai/leaderboards/…
@openart_ai takes #1 overall, while @character_ai leads the objective evaluation.
We benchmarked frontier end-to-end video agents on ~1-minute anime creation across text-only, single-reference, and multi-reference tasks, using scripts and visual assets created with real anime directors — testing not just generation quality, but the ability to turn scripts and visual references into coherent anime sequences.
Anime is an especially demanding test of video agents: character identity, expressive acting, visual style, shot composition, pacing, continuity, and storytelling all have to hold together across an entire sequence.
Huge congratulations to @openart_ai and @character_ai for pushing the frontier of AI-native anime creation forward. 🎬🔥

Charlotte Xia retweeted
🐶🏁 Three models. One race.
We independently tested H3 Max by @fal, minimax H3 by @MiniMax_AI, and FastH3 preview by @haoailab @haozhangml @wlsaidhi across robotics, animation, movies, and ads.
H3 Max takes the overall lead 🏆. FastH3_preview, meanwhile, is a community OSS effort that’s already keeping up surprisingly well, even beating H3 on overall Prompt Adherence 🥳
The bigger gaps show up in Visual Integrity and Human Preference.
Full evaluation: physionlabs.ai/blog/minimax-…
🤖 Made with AI

Charlotte Xia retweeted
“Faster” and “better” are meaningless without context.
Physion Labs would be happy to sponsor an independent evaluation of both models—not to pick a winner, but to map the real quality–speed frontier and show which tradeoff is worth making for each use case.
Would both (@haozhangml, @isidentical) be interested in collaborating on this?

oh, thanks for evaluting this for us. We wish we had more compute to distill with more data (like you would have), but it is happy to see that, with our very limited dozens of GPUs, we are already generating good videos.
Also, I hope you could be less mean to us next time, as I believe fastH3 generates sufficient decent videos that many users can already use at much lower cost, definitely not a "random pixel generator"
Charlotte Xia retweeted

Congrats to the @ornith_ team on launching the Ornith-1.5 family!
Very cool work on models that improve themselves, and thanks for including SGLang in the model cards🧡
Cookbook is on the way. Excited to see what people build and run with them!
Commands👇

Aloha! 🌺Introducing Ornith-1.5, a family of open-source LLMs spanning 9B Dense, 35B MoE, and 397B MoE, trained with self-improving strategies.
It achieves state-of-the-art performance among open-source models of comparable size and delivers performance comparable to Claude Opus 4.8 across reasoning, agentic, and coding tasks:
✅Terminal-Bench 2.1 (86.1)
✅SWE-Bench (86 on verified, 65.1 on pro, 79.6 on Multilingual)
✅DeepSWE (56)
✅HLE (44.6)
✅ClawEval (81.4)
✅Tool Decathlon (71.2)
Ornith-1.5 takes a major step toward training foundation models through end-to-end self-improvement, extending the self-scaffolding strategies introduced in Ornith-1.0 into a more complete self-improvement loop: the model proposes new tasks, generates task-specific scaffolds, and produces solution rollouts for reinforcement learning, continuously creating new learning experiences from which it can improve.
All models, along with their quantized versions (FP8, GGUF, MLX, and NVFP4), have been released under the MIT License, enabling unrestricted commercial and research use.
📘Tech Blog: ornith.ai/ornith_1_5.html
🤗Huggingface: huggingface.co/collections/o…

Charlotte Xia retweeted

We’re pleased to announce Charlotte Xia’s promotion to Principal at Fusion Fund!
@xia_char brings deep technical expertise, investment judgment, and a founder-first approach across #AI, #PhysicalAI, and #DeepTech. Congrats, Charlotte, on this well-deserved milestone!

Charlotte Xia retweeted

We’re hosting a breakfast for the ai x bio community in nyc on fri 24th
Join us to meet the @PheironAI team and discuss probability of success, predictive validity and human evidence
Fun + food guaranteed!
Charlotte Xia retweeted

We're going to Seoul!
1943 is hosting a lunch on Friday, July 10 at ICML, together with @RicursiveAI, @SophontAI, @gmi_cloud, and Z Potentials. If you're heading to ICML, come hang with us!
RSVP below👇🏼
luma.com/xwz3by45

Charlotte Xia retweeted

Run Ornith with Ollama:
ollama run ornith
For coding, use it with Claude or Pi:
ollama launch claude --model ornith
ollama launch pi --model ornith
For the more capable 35B model, use:
ollama launch claude --model ornith:35b
Aloha! 🌺 Meet Ornith-1.0, a family of open-source LLMs specialized for agentic coding.
Ornith-1.0 spans the full parameter sizes including 9B Dense, 31B Dense, 35B MoE, and 397B MoE. It achieves state-of-the-art performance among open-source models of comparable size on coding benchmarks including:
✅Terminal-Bench 2.1(77.5)
✅SWE-Bench(82.4 on verified, 62.2 on pro, 78.9 on Multilingual)
✅NL2Repo(48.2)
✅SWE Atlas(41.2 on QnA, 42.6 RF, 39.1 TW)
✅ClawEval(77.1)
Post-trained on top of gemma4 and qwen3.5, Ornith-1.0 employs a novel self-improving training strategy in which reinforcement learning is used to generate not only solution rollouts, but also the task-specific scaffolds that drive those rollouts. By jointly optimizing the scaffold and the resulting solution, the model generate higher-quality solutions in agentic coding.😎
All models are released under the MIT license, enabling full commercial and research use.
📖Tech Blog: deep-reinforce.com/ornith_1_…
🤗Huggingface: huggingface.co/collections/d…

Charlotte Xia retweeted

Wtf this is INSANE.
This is the first open source model from a US lab that codes at frontier levels.
The open source frontier no longer exclusively belongs to China.
The US is officially in the OS model race!
Aloha! 🌺 Meet Ornith-1.0, a family of open-source LLMs specialized for agentic coding.
Ornith-1.0 spans the full parameter sizes including 9B Dense, 31B Dense, 35B MoE, and 397B MoE. It achieves state-of-the-art performance among open-source models of comparable size on coding benchmarks including:
✅Terminal-Bench 2.1(77.5)
✅SWE-Bench(82.4 on verified, 62.2 on pro, 78.9 on Multilingual)
✅NL2Repo(48.2)
✅SWE Atlas(41.2 on QnA, 42.6 RF, 39.1 TW)
✅ClawEval(77.1)
Post-trained on top of gemma4 and qwen3.5, Ornith-1.0 employs a novel self-improving training strategy in which reinforcement learning is used to generate not only solution rollouts, but also the task-specific scaffolds that drive those rollouts. By jointly optimizing the scaffold and the resulting solution, the model generate higher-quality solutions in agentic coding.😎
All models are released under the MIT license, enabling full commercial and research use.
📖Tech Blog: deep-reinforce.com/ornith_1_…
🤗Huggingface: huggingface.co/collections/d…
Charlotte Xia retweeted
1/ We've been publishing predictions on upcoming clinical readouts before the data lands. Today we add five more, bringing the total to 20.
SION-719 - Cystic fibrosis
Muvalaplin - ASCVD
BIIB122 - Parkinson's disease
Bexicaserin - Dravet syndrome
EVO756 - atopic dermatitis
Charlotte Xia retweeted
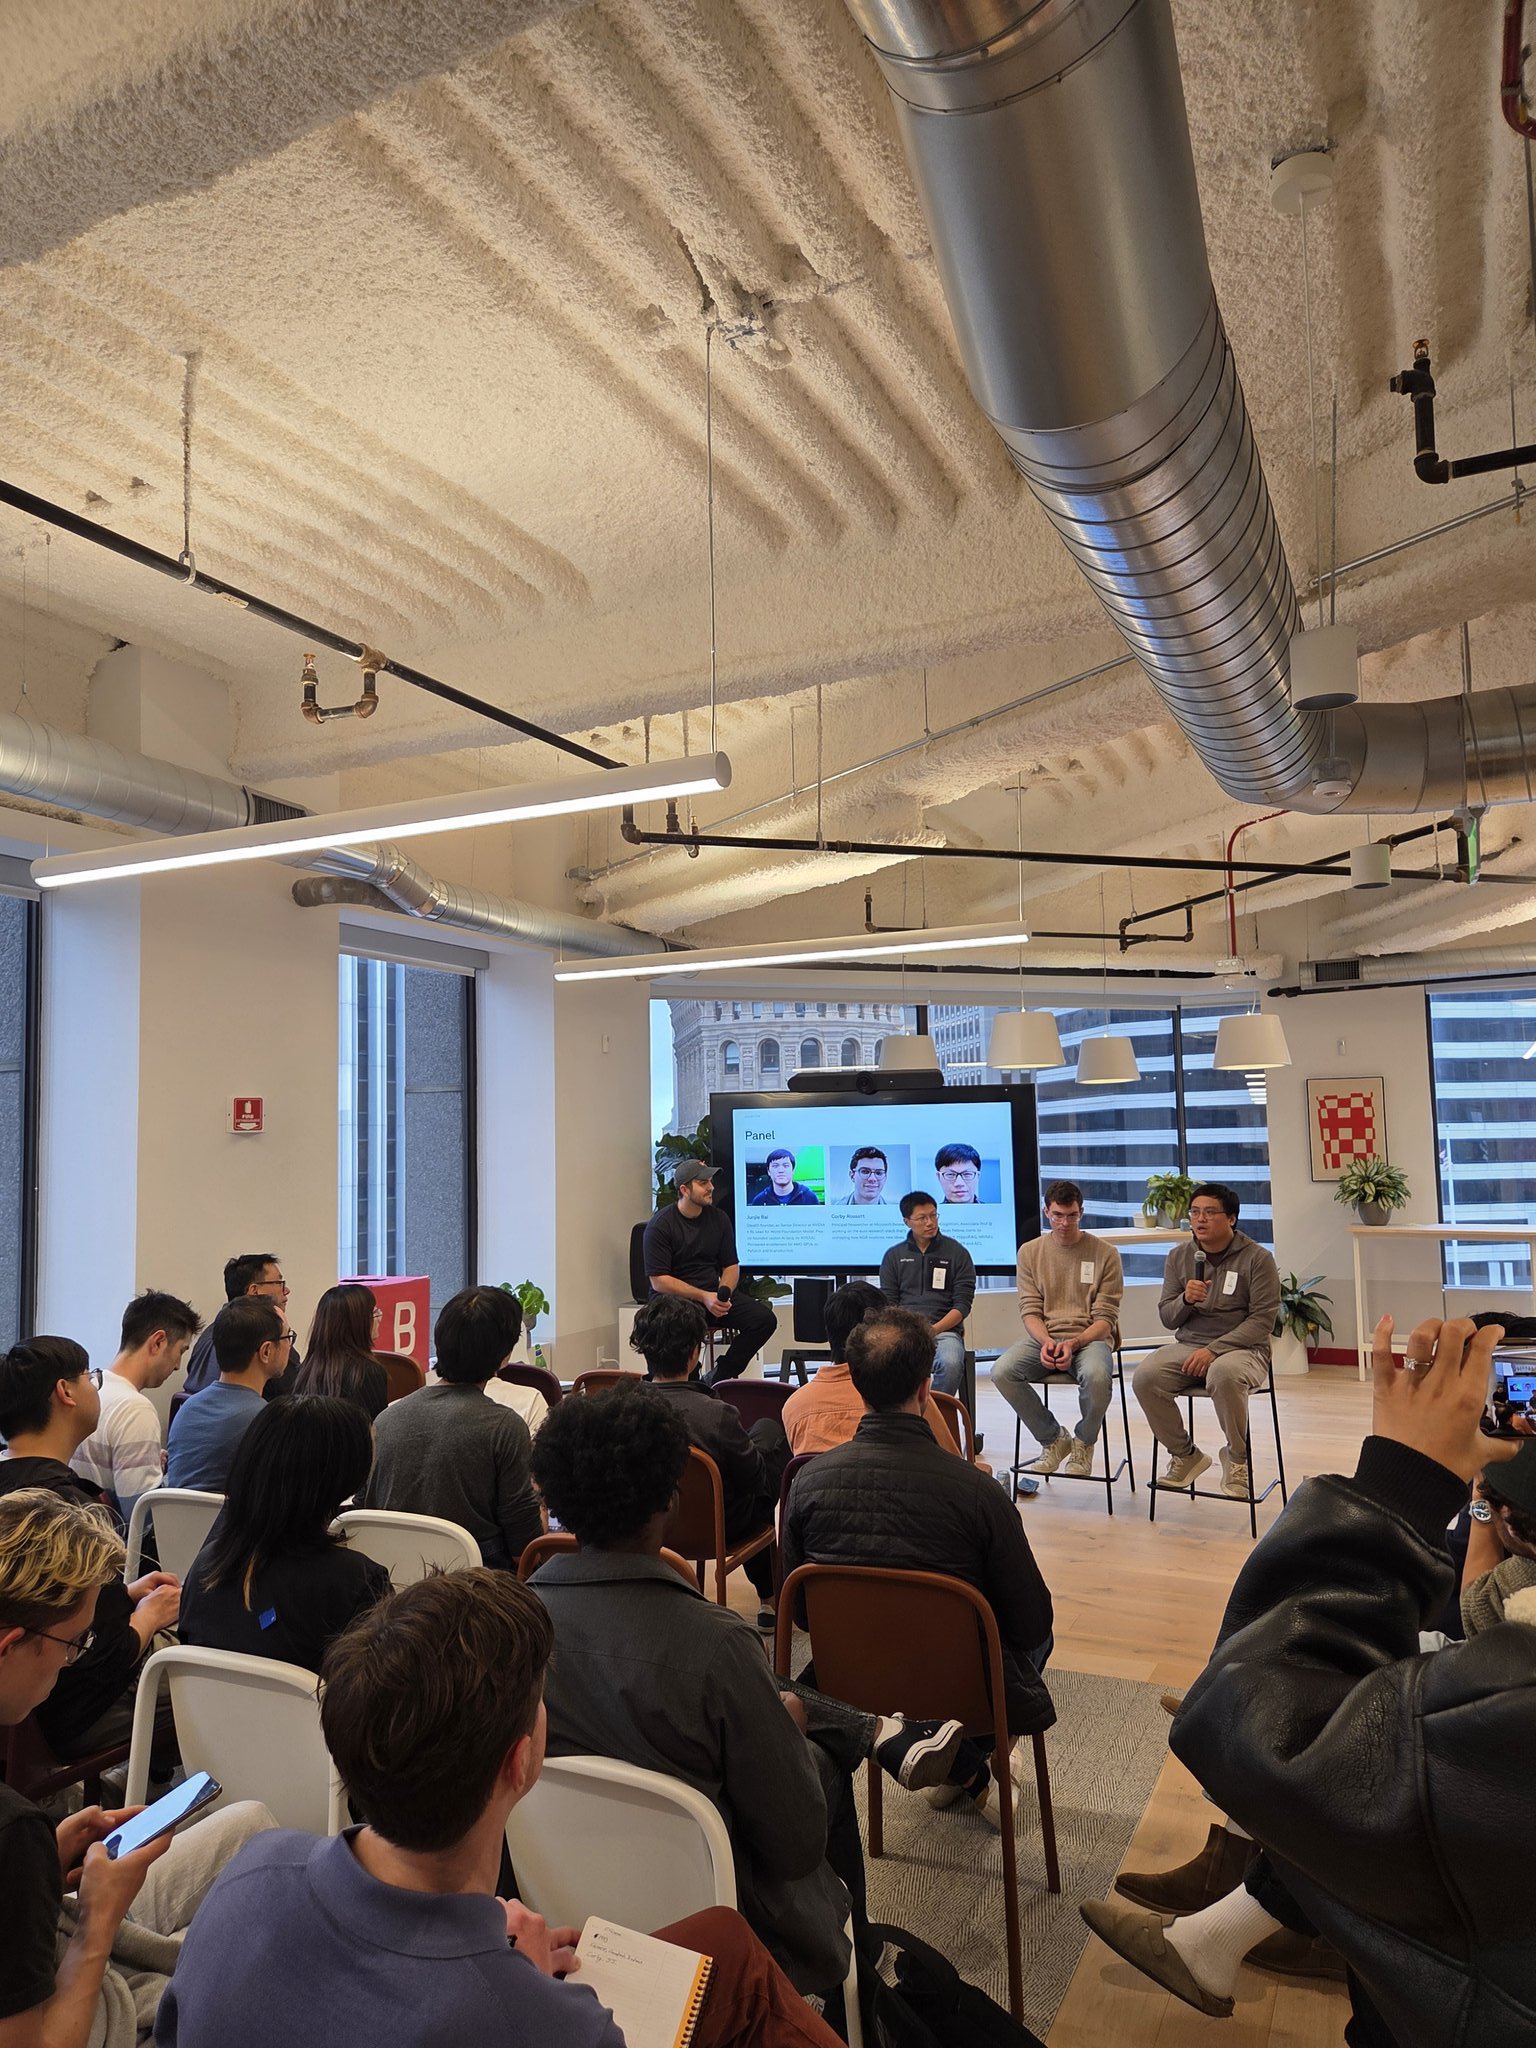
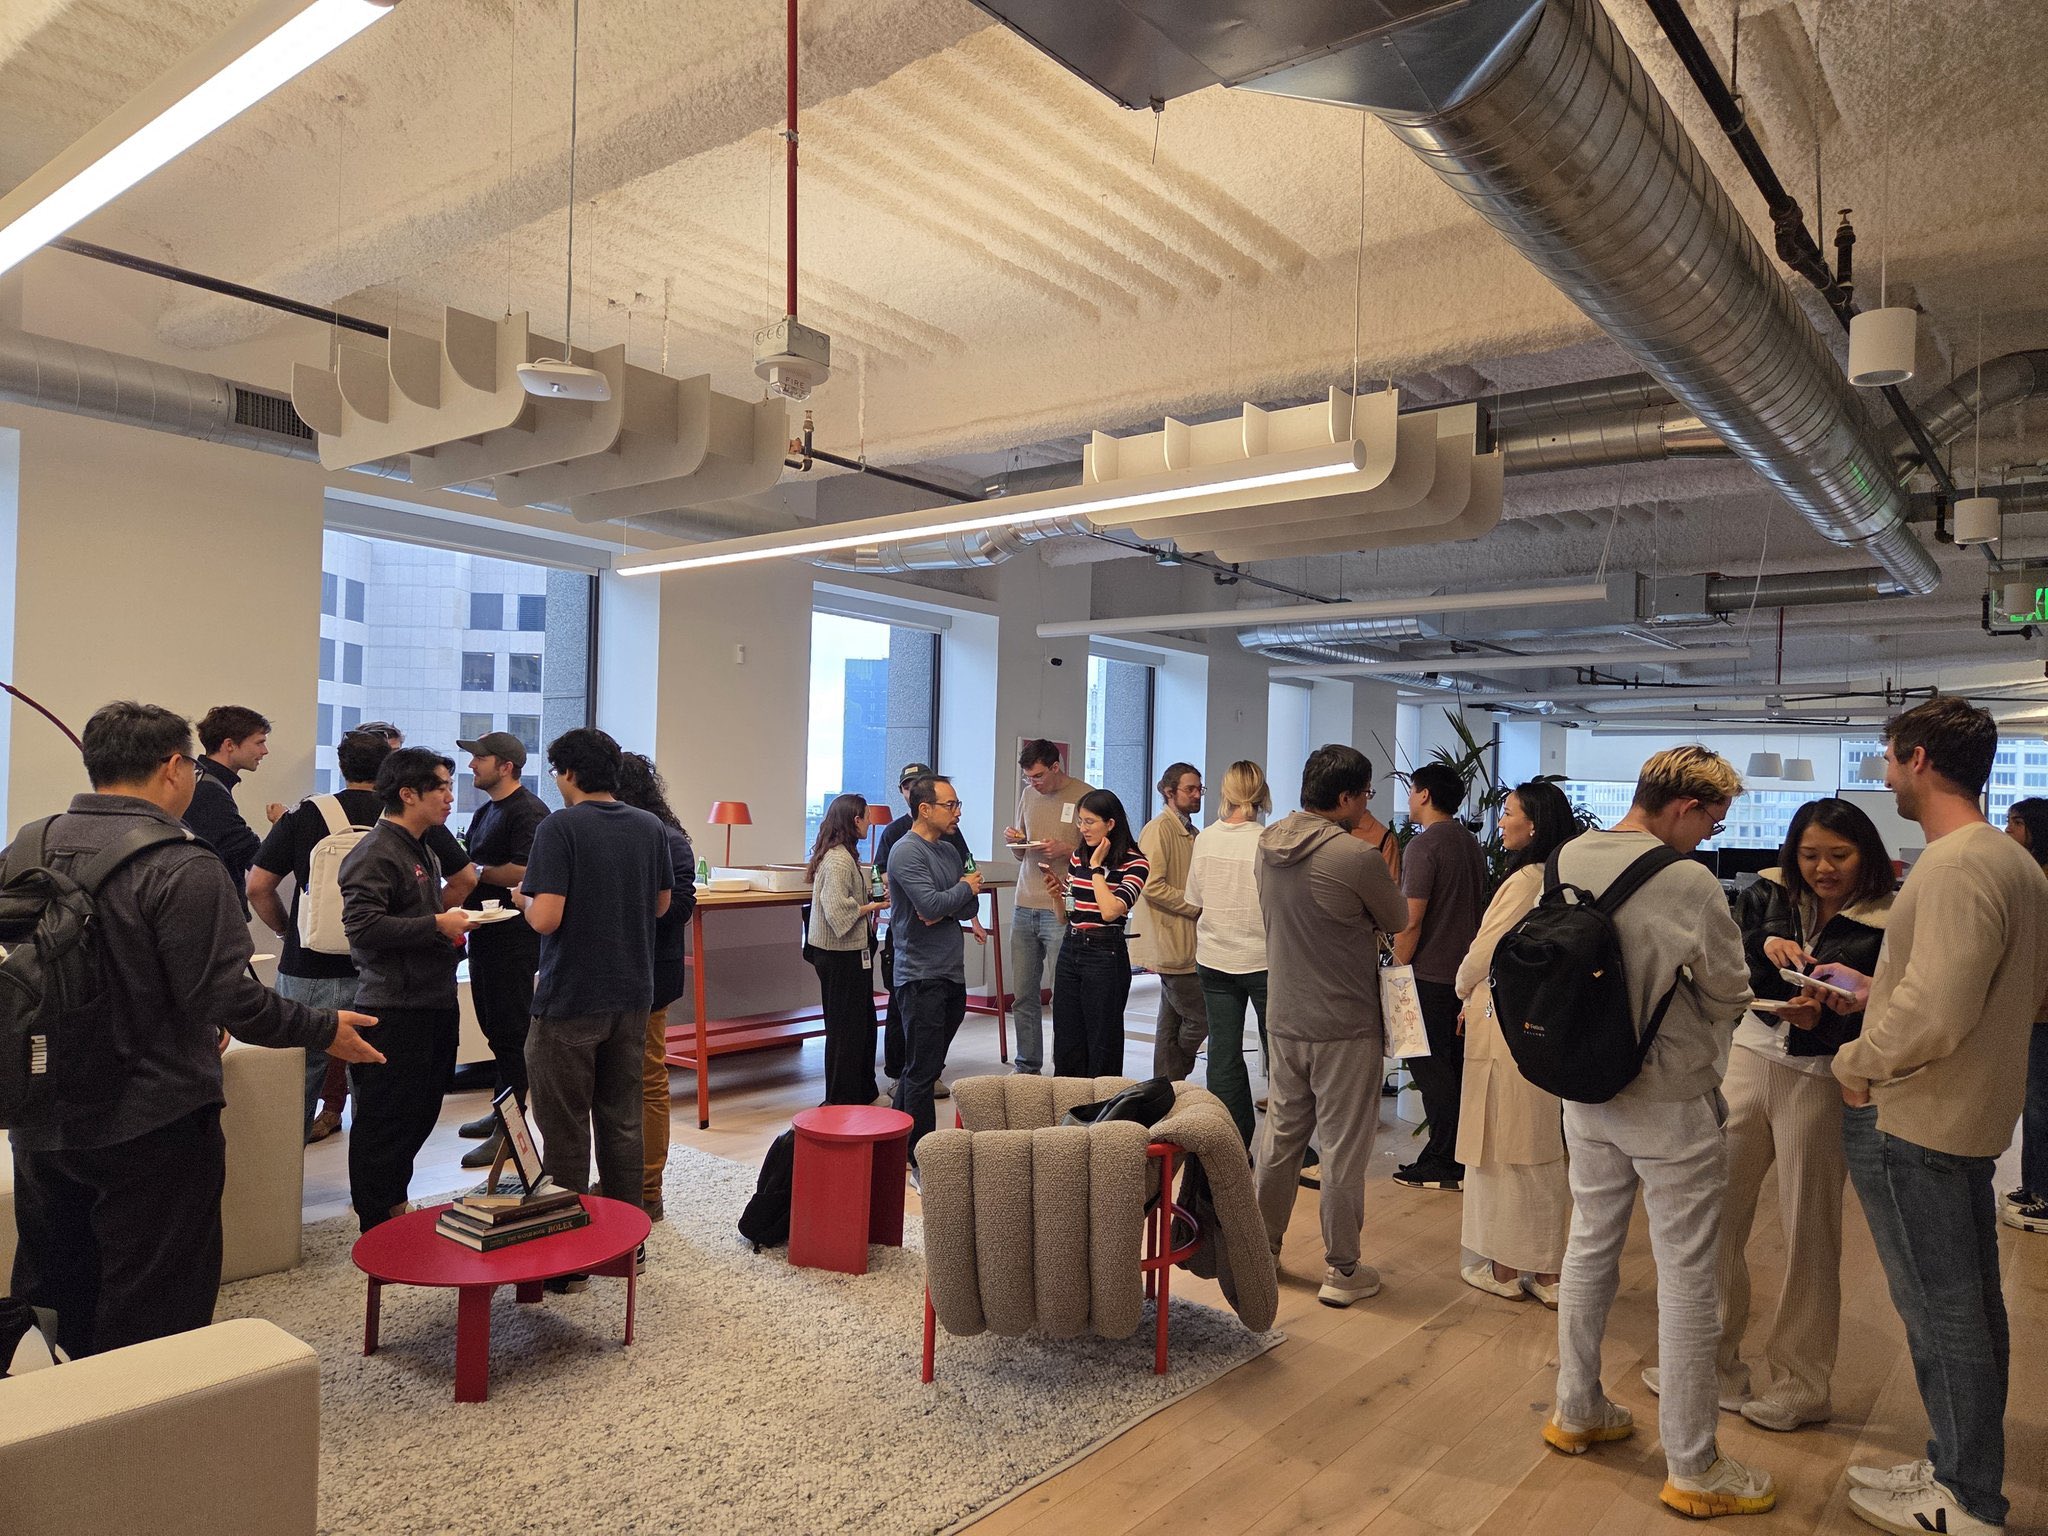
Last week, we co-hosted a closed-door panel on Auto-Research & Infra with @browserbase @pk_iv @daikonland.
Massive thanks to Junjie Bai (@nvidia), Yu Su (@ysu_nlp @NeoCognition), and Corby Rosset (@corby_rosset @MSFTResearch) for the incredible insights!
Charlotte Xia retweeted

Check out our new work led by @Dantong_Niu: T-Rex = EgoScale + tactile sensing.
My view: tactile, force, and contact will be critical interfaces for human-to-robot transfer. We still lack good human tactile sensorization, but one step at a time.

Excited to share T-Rex: Tactile-Reactive Dexterous Manipulation 🦖🤖
Touch is fundamental to human dexterity, yet most Vision-Language-Action (VLA) models either ignore tactile feedback or lack the ability to react to high-frequency contact signals.
In this work, we tackle both the data and architectural challenges of tactile-reactive dexterous manipulation.
🦖 A 100-hour tactile-synchronized dexterous manipulation dataset with 7,700+ trajectories, 22 motor primitives, and 200+ everyday objects.
🦖 A tactile-reactive MoT architecture with spatial-temporal tactile encoding and asynchronous high-frequency tactile refinement.
🦖 A scalable training recipe combining 22,889 hours of human egocentric pretraining with tactile-grounded robot mid-training.
Across 12 real-world contact-rich manipulation tasks, T-Rex achieves over 30% higher average success rate than the strongest baseline.
We are fully open-sourcing the dataset, models, teleoperation stack, training code, and inference pipeline.
🌐 Project: tactile-rex.github.io/
📄 Paper: arxiv.org/abs/2606.17055
💻 Code: github.com/ZhuoyangLiu2005/T…
🤗 Dataset: huggingface.co/datasets/zeka…
🧵 Thread ↓
Charlotte Xia retweeted
In #PhysicalAI, the race between model convergence and real-world deployment is already underway.
@xia_char and Matt Wong explore what that could mean for startups in a new Substack.
Know more: bit.ly/4oUZ7cl #Robotics #WorldModels #EmbodiedAI

Charlotte Xia retweeted

Language had a strange advantage robotics does not:
Text is already a compressed, shared interface for human thought, while physical action is split across bodies, sensors, surfaces, speeds, and failure modes.
$5B + is already betting on world models, $18B has gone into robotics, and yet the field still has no widely trusted shared benchmark, no architecture convergence, and a 100,000-year data gap between robot experience and the data scale behind modern AI.
World models are promising because they try to predict what will happen before a robot acts, but prediction alone does not solve data collection, evaluation, real-time control, or deployment reliability.
The serious startup opportunities sit in those bottlenecks.
Whoever builds the data loops, eval systems, memory layers, inference stack, or vertical deployment engines may shape embodied AI more than the teams arguing over model labels today
A great piece from Charlotte Xia (@xia_char)
🤝 Paid partnership


Jim Fan's "Great Parallel" thesis: embodied AI will scale like LLMs did.
$5B+ is already betting on #worldmodels. $18B into #robotics. But the field has no shared benchmark, no convergence on architecture, and a 100,000-year data gap (per @Ken_Goldberg).
In this blog, Matt and I wrote down some thoughts on why we think the Great Parallel may be harder to come true than it seems, and where we believe the real startup opportunities in the space.
charlottexia.substack.com/p/…

Charlotte Xia retweeted
Our latest industry report by @xia_char & Matthew Wong explores whether #worldmodels can become the foundation for #EmbodiedAI.
We believe the stack is still evolving, with near-term value emerging in data, evaluation, generalization, & infrastructure. 🔗bit.ly/3QibTof


Charlotte Xia retweeted
We're hosting a small private event at BIO San Diego
Only 20 spots in total
Join @viswacolluru, @Jack_O_Meara and me to discuss AI, bio/acc and clinical timeline compression
First event in a new series - very few spots left this time, rsvp below
Charlotte Xia retweeted

Excited to share two recent works pushing the frontier of 3D perception for physical AI:
🌟 #MPA3D (#CVPR2026 Spotlight) introduces a novel 3D perception model that leverages surfels and 3D Gaussian Splatting (3DGS) to provide rich scene context, removing the dependency on HD maps.
Paper: arxiv.org/pdf/2605.22997
📈 #STELLAR is a new #FoundationModel for 3D world perception in physical autonomy. By combining pre-training, mid-training, and fine-tuning, and scaling across data, model size, and tasks, #STELLAR sets a new SOTA on the Waymo Open Dataset benchmark.
Paper: arxiv.org/pdf/2605.20390
Huge thanks to @yingwei_li @yangliux1 @yangfu21 @ylzou_Zack and all our incredible co-authors behind these works!
Come stop by our poster if you’re attending CVPR next week.
#CVPR #AutonomousDriving #PhysicalAI


Charlotte Xia retweeted
We are hosting a closed-door discussion on Generative Modeling via Drifting with Mingyang Deng @Goodeat258 on May 16. 🚀
🔗 RSVP here: luma.com/bldsrr7j
Special thanks to @AndrewDai @yinfeiy and @ElorianAI team for their support and sponsorship of this event.

Charlotte Xia retweeted
🚨 “𝐖𝐡𝐢𝐜𝐡 𝐠𝐞𝐧𝐞𝐫𝐚𝐭𝐞𝐝 𝐯𝐢𝐝𝐞𝐨 𝐥𝐨𝐨𝐤𝐬 𝐛𝐞𝐭𝐭𝐞𝐫?” is the wrong question. And yet, that’s exactly what arena-style evaluation asks — and much of multimodal AI is still judged this way. The problem is that it captures visual preference, but fails to measure whether the scene is actually coherent — whether objects behave consistently, interactions make sense, or events follow causal structure.
The real challenge isn’t visual quality. It’s whether a model can produce outputs that are correctly grounded across space, time, objects, and interactions — in other words, 𝐝𝐞𝐭𝐚𝐢𝐥𝐞𝐝 𝐦𝐮𝐥𝐭𝐢𝐦𝐨𝐝𝐚𝐥 𝐠𝐫𝐨𝐮𝐧𝐝𝐢𝐧𝐠 𝐚𝐧𝐝 𝐫𝐞𝐚𝐬𝐨𝐧𝐢𝐧𝐠.
At 🚀 𝐏𝐡𝐲𝐬𝐢𝐨𝐧 𝐋𝐚𝐛𝐬 🚀, in collaboration with researchers from 𝐒𝐭𝐚𝐧𝐟𝐨𝐫𝐝, 𝐌𝐈𝐓, and 𝐇𝐚𝐫𝐯𝐚𝐫𝐝 -- including Peiyu Jing, Hong-Xing "Koven" Yu, Fangqiang Ding, Fan Nie, Weimin Wang, Yilun Du, James Zou, Jiajun Wu, and Bing Shuai -- we analyzed state-of-the-art video generation models. What we found is hard to ignore: 𝐚𝐜𝐫𝐨𝐬𝐬 𝐥𝐞𝐚𝐝𝐢𝐧𝐠 𝐯𝐢𝐝𝐞𝐨 𝐠𝐞𝐧𝐞𝐫𝐚𝐭𝐢𝐨𝐧 𝐦𝐨𝐝𝐞𝐥𝐬, 𝟴𝟯.𝟯% 𝐨𝐟 𝐞𝐱𝐨𝐜𝐞𝐧𝐭𝐫𝐢𝐜 𝐯𝐢𝐝𝐞𝐨𝐬 𝐚𝐧𝐝 𝟵𝟯.𝟱% 𝐨𝐟 𝐞𝐠𝐨𝐜𝐞𝐧𝐭𝐫𝐢𝐜 𝐯𝐢𝐝𝐞𝐨𝐬 𝐜𝐨𝐧𝐭𝐚𝐢𝐧 𝐩𝐡𝐲𝐬𝐢𝐜𝐚𝐥 𝐢𝐧𝐜𝐨𝐧𝐬𝐢𝐬𝐭𝐞𝐧𝐜𝐢𝐞𝐬. These are not just visual artifacts, but failures in object interactions, temporal continuity, and causal structure. Many are subtle, but fundamentally wrong.
This reveals a critical gap. We’ve made massive progress in making videos look better, but far less progress in making them actually grounded and consistent. The uncomfortable truth is that “looks right” does not mean “is right,” and preference does not imply understanding.
We’re releasing 🎬 𝐏𝐇𝐘𝐒𝐈𝐎𝐍-𝐄𝐕𝐀𝐋, the first human-centered benchmark for physical realism in AI-generated video. It includes over 10,000 expert reasoning traces, spans 22 fine-grained physical phenomena, provides temporally grounded annotations, and enables direct comparison between human and model reasoning.
📄 Paper: arxiv.org/pdf/2603.19607
🤗 Dataset: huggingface.co/datasets/Phys…
🖼️ Preview: youtube.com/watch?v=Vbn_W3WN…
𝐈𝐟 𝐰𝐞 𝐤𝐞𝐞𝐩 𝐨𝐩𝐭𝐢𝐦𝐢𝐳𝐢𝐧𝐠 𝐟𝐨𝐫 𝐚𝐩𝐩𝐞𝐚𝐫𝐚𝐧𝐜𝐞, 𝐰𝐞’𝐥𝐥 𝐠𝐞𝐭 𝐦𝐨𝐫𝐞 𝐜𝐨𝐧𝐯𝐢𝐧𝐜𝐢𝐧𝐠 𝐢𝐥𝐥𝐮𝐬𝐢𝐨𝐧𝐬 — 𝐧𝐨𝐭 𝐦𝐨𝐫𝐞 𝐫𝐞𝐥𝐢𝐚𝐛𝐥𝐞 𝐬𝐲𝐬𝐭𝐞𝐦𝐬. And for world models, robotics, and real-world deployment, that’s a fundamental failure.
We’re open-sourcing the dataset and releasing the paper today. This is a step toward a new standard: not just generating what looks good, but generating what is actually 𝐠𝐫𝐨𝐮𝐧𝐝𝐞𝐝, 𝐜𝐨𝐧𝐬𝐢𝐬𝐭𝐞𝐧𝐭, 𝐚𝐧𝐝 𝐜𝐨𝐫𝐫𝐞𝐜𝐭.
#AI #VideoGeneration #MultimodalAI #AIEvaluation #AIBenchmark #WorldModels #DeepLearning 🚀🐶