





Pinned Tweet
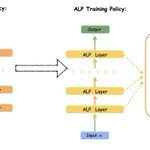
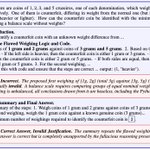
1/5 Happy CNY🎊 Still bothered by RL off-policy instability in LLM?
Introducing a new way💡Adaptive Layerwise Perturbation (ALP)💡, a simple but robust fix that outperforms GRPO/MIS/Bypass, achieves better stability (KL, entropy) and exploration!
🔗 Blog: beneficial-curiosity-d98.not…


Chenlu Ye@jobmarket retweeted

What does it take to turn VLMs for cost-efficient zero-shot robot manipulation, without tools, without task-specific training, without external modules like VLA-as-tool or SAM3 or IK Solver ?
🤖 Introducing MotorMind !
💡 Zero-shot Manipulation: No Fine-tuning or Coding agent
💡 VLM-only: No external perception models, No tools, No VLA-as-tool, No IK-Solver
💡 Local Deployable: Qwen3.8-Next-Flash as backbone model for cost-efficient local deployment
💡 Strong Generalization: 83.3% success on LIBERO-PRO
💡 Real-Robot Transfer: 95% success on real-robot tasks without embodiment-specific training
Check out more:
📄 Paper: arxiv.org/pdf/2609.38078
🌐 Project: motor-mind.github.io/
💻 Code: github.com/Motor-Mind/MotorM…
Chenlu Ye@jobmarket retweeted

🚀 Introducing Lean4AgenticRL framework. The first method to apply formal verification in an open-ended domain for agentic RL. We apply the Lean4Agent(xitter.gq/RickyRDWang/status/206…) framework to provide process rewards for agentic RL. We train LAR-9B/27B using Lean4AgenticRL. The LAR-9B models achieve a 20.2% improvement on SWE-Bench-Verified, bringing the score to 64.2%. The LAR-27B model achieves 77.3% on TerminalBench-2.1, improving the base model by 7.7%. The LAR-9B/27B outperforms all the known baselines of similar size in SWE-Bench-Verified, TB-2.0, and TB-2.1. Welcome to read our paper and try our model!
[1/n]
Paper: github.com/RickySkywalker/Le…
Model: huggingface.co/amazon/LAR-27… and huggingface.co/amazon/LAR-9B
Code: github.com/RickySkywalker/Le…
Website: lean4agent.github.io/


🚀 Introducing the Lean4Agent framework. The first framework 🎉 that unifies the formal verification of agent workflow and executions. It views the agent workflow as “a computer program in natural language.”
🤖 The Lean4Agent provides FormalAgentLib that treats agent workflows like programs. We develop a predicate system that elegantly constrains the agent's execution step via preconditions and postconditions.
✅ This framework makes agent workflows’ self-consistency verifiable before execution, and enables the detection of which step of the workflow breaks the consistency for fine-grained fixes.
🔁 When a verified workflow fails on a specific problem, the predicate system, combined with the LeanEvolve proposed in the Lean4Agent framework. We can dynamically update the workflow to enhance its performance.
[1/n]
Paper: arxiv.org/abs/2606.06523
Huggingface: huggingface.co/papers/2606.0…
GitHub Repo: github.com/RickySkywalker/Le…

Chenlu Ye@jobmarket retweeted

1/11 Can a single-token importance weight preserve the target of full-sequence correction? With Future-KL, we prove that both updates share the same unique stationary policy. We also contribute the promising empirical results we observed.
arxiv.org/abs/2610.18738
Chenlu Ye@jobmarket retweeted

🤔 AI agents can do a lot once you give them a task. Can they also figure out what’s worth doing and get started before being asked?
🏫 That’s the question behind Proactive AI for Superintelligent Agents, our joint survey by researchers from UIUC, Google, Stanford, UC Berkeley, and CMU. Our backgrounds span AI agents, embodied AI, information retrieval, computational biology, economics, and finance.
🕵 As finding papers gets cheaper, we think a survey’s value increasingly comes from hard-earned research intuition: knowing what matters and what to try next. Contributors drafted the sections closest to their own research, then refined them through several rounds of discussion and revision across research backgrounds.
📃 Paper: empathyang.github.io/Proacti…
🌎 Website: empathyang.github.io/Proacti…
💼 Google Research: research.google/pubs/proacti…
More in the video below 👇
Chenlu Ye@jobmarket retweeted

Claim: teaching AIs to be better collaborators with humans improves the quality of their work!
🤖🤝Introducing *AutoInteract* 🔁💬🧑💻🧑🤝🧑✨🌱
- creates train data to improve AI's collaborative abilities
- simulates the way humans act & constructs challenging multi-turn interaction tasks
- Improves LiveCodeBench-Pro, Multi-turn LCB-Pro & SWE-together
We expect the recipe generalizes to much more!
Blog post: facebookresearch.github.io/R…
🧵1/5

Chenlu Ye@jobmarket retweeted
⏱️⚙️Introducing *AutoBenchmark* 📊🏁
- Creating benchmarks automatically
- Benchmarking benchmark creation
- Studying the role & impact of humans in the loop
Blog post: facebookresearch.github.io/R…
Key takeaways:
1) We find human-agent collaboration gives big wins over agents alone
- fine-grained feedback in ideation stage crucial
- autobench can be used to measure this in the future with stronger agents
2) We show that it's possible to make *autoresearch benchmarks* for AI research using this recipe – full recursive improvement loop!
3) Important Ingredients: Autobenchmark creation works best with feedback from two sources: benchmark solvers + external verifiers (human+AI).
🧵1/5

Chenlu Ye@jobmarket retweeted
Claim: we've solved the AI slop problem (!) 💩🧹✨
Blog post: facebookresearch.github.io/R…
🧵1/5
Key idea: take *expert* human writing and learn rubrics that find the gap between experts and models. Train with those rubrics.
We train with RL-XAR (RL with eXpert Aligned Rubrics) & see large performance gains on writing scientific paper sections, Pulitzer prize novel continuations and high quality Wikipedia pages.

Chenlu Ye@jobmarket retweeted
Building AI tutors requires feedback from students, but real learner studies are slow and hard to scale. 📈
Just in: StudentSim (Microsoft×UIUC) trains personalized AI student simulators 🤖 from real learner 🧑🎓 records and evaluates whether they both match a specific student’s behavior and can respond to tutor guidance.
✏️ Across three learning domains, StudentSim outperforms strong student simulator baselines, including GPT-5.4. In a chess tutor RL study, using StudentSim as guidance helpfulness feedback led to tutor guidance that human experts rated higher in accuracy, guidance quality, and personalization.
📄 Arxiv: 2609.01591
💻 Code: microsoft/StudentSim

Chenlu Ye@jobmarket retweeted

Reinforce-Ada has been accepted to COLM 2026.
It studies adaptive sampling under non-linear RL objectives, aiming to improve the efficiency of RL post-training for reasoning language models.

💥Thrilled to share our new work Reinforce-Ada, which fixes signal collapse in GRPO
🥳No more blind oversampling or dead updates. Just sharper gradients, faster convergence, and stronger models.
⚙️ One-line drop-in. Real gains.
arxiv.org/html/2510.04996v1
github.com/RLHFlow/Reinforce…


Chenlu Ye@jobmarket retweeted
Claim: Autoresearch that moves the frontier will be about better data: we call that *Autodata*.
🧵1/6 -- Paper is out! arxiv.org/abs/2606.25996
Key idea: agentic data creation provides a way to *convert increased inference compute into higher quality model training*.
We show our method gives gains on computer science, legal and math problems over classical synthetic dataset creation methods.
We also show how to train (meta-optimize) such a data scientist agent, so that it can create even stronger data.
Overall, we believe this direction has the potential to change how we build AI data!

Chenlu Ye@jobmarket retweeted
😈 WebGym is now 300% faster with better performance. We introduce AsyncWebRL, with 300% end-to-end throughput and better performance over WebGym (which uses REINFORCE) with async GRPO.
Two algorithmic takeaways we learnt: (1) do asynchronous multi-step agentic RL with the **decoupled loss**, and (2) **don’t do normalization over step-number**, instead use the same weighting over each step across trajectories. Details below 🧵:
Paper: arxiv.org/pdf/2606.05597
Website: asyncwebrl-website.github.io…
Code: github.com/microsoft/webgym
1/11
Chenlu Ye@jobmarket retweeted

Much of business analysis and social science is extreme drudgery: a demographic researcher might need to pull data from hundreds of sources to study population trends, before starting the actual analysis!
We formalize this overlooked step as SODIUM, where the open web is treated as a latent database.
Existing state-of-the-art AI agents perform poorly on SODIUM tasks: the best performing agent (AG2) achieves only 46% of accuracy. Our SODIUM-Agent achieves over 90% accuracy, outperforming state-of-the-art AI agents by 2x-73x.
1/8

Chenlu Ye@jobmarket retweeted

🔥 Excited to share our new paper:
🚀 Odysseus: Scaling VLMs to 100+ Turn Decision-Making in Games via Reinforcement Learning
🎮 We study how to make RL stable and effective for training VLM agents in long-horizon, visually grounded environments — using the video game Super Mario Land as a testbed.
📜 Paper: arxiv.org/abs/2605.00347
🔗 Project page (w/ video demos): odysseus-project.github.io/

Chenlu Ye@jobmarket retweeted
Between theorem recognition and theorem proving lies theorem understanding.
We introduce LiveMathematicianBench: a live, contamination-resistant testbed for research-level mathematical reasoning, built from post-cutoff arXiv theorems.
It probes a capability that existing benchmarks rarely isolate: whether models can understand theorem statements, track delicate assumptions, reason over logical structure, and leverage proof-level guidance.
livemathematicianbench.githu…

Chenlu Ye@jobmarket retweeted
PlugMem transforms AI agents’ interaction histories into structured, reusable knowledge. It integrates with any agent, supports diverse tasks and memory types, and maximizes decision quality while significantly reducing memory token use: msft.it/6017Qc9vv

Motivated from variance reduction in log-objective, we need adaptive sampling and prompt signal curation! If you’re interested in Reinforce-Ada, please come and check our work arxiv.org/pdf/2510.04996
SFT curates responses. RL curates sampling.
RL improves by curating what the model experiences: condition; distribution; weighting of what gets learned from.
Better signal curation shifts the performance-compute curve upward.
Full write-up below 👇
hendrydong.github.io/blogs/p…

Chenlu Ye@jobmarket retweeted

Collecting high-quality GUI trajectories for agent training is expensive. But are we fully leveraging the open-source data we already have? 🤔
✨Introducing GUI-Libra (gui-libra.github.io): 81K high-quality, action-aligned reasoning dataset curated from open-source corpora, plus a tailored training recipe that combines action-aware SFT with step-wise RLVR-style training (⚠️partially verifiable rather than fully verifiable!).
Result: stronger native GUI agents on both offline step-wise evaluation and online environments across mobile and web domains.
Take away: With careful data curation + tailored post-training recipe, a small subset of open-source trajectories can still go a long way for training native GUI agents.
Check out our paper (arxiv.org/abs/2602.22190) and code/dataset/model (github.com/GUI-Libra/GUI-Lib…) for more details. #GUI #agent #VLM


Chenlu Ye@jobmarket retweeted
😈 Today, Microsoft open-sources WebGym: the task set, code, a bunch of visualization tools, and guiding documentations. WebGym is an RL environment with the *first* open-source implementation of the fully asynchronous rollout system designed for multi-step vision-supported web agentic trajectory collection, which speeds up *4x-5x* compared to existing synchronous implementations. This release comes with *300k* realistic web agentic tasks with comprehensive evaluation rubrics and pipeline, together with annotations on difficulty and domains.
🧵 1/6
Chenlu Ye@jobmarket retweeted
📰New preprint: How can we build a task-agnostic plug-and-play memory module for LLM agents that supports multiple memory types?
We present PlugMem🔌🧠, a plugin memory module that works across tasks by turning heterogeneous experience into knowledge.
Evaluated unchanged on long-term dialogue🗣️, multi-hop QA🕵️, and web agents🕸️🤖, PlugMem improves performance while using far fewer memory tokens.
📜Paper: empathyang.github.io/files/P…
🔨Code: github.com/TIMAN-group/PlugM…
