

BTW: DM's are open for collab or jobs / hiring Playing with my DGX Spark, BRB.
Middle of the GPU
Joined January 2023
- Tweets6K
- Following1.9K
- Followers2.8K
- Likes9.9K



Pinned Tweet
🚨🚨🚨
🏎️ LIMCARS — Local Inference Monitor · Cost Analyzer · Recipe Server
Your DGX Spark, finally with a dashboard that tells the truth.
📊 Live dashboard, 2 times per second
• ⚡️ Generation & prefill speed, TTFT & end-to-end latency — with honest sample counts, never percentile theater
• 🧠 KV cache usage, prefix-cache hit rate, speculative-decoding acceptance
• 🖥️ Hardware sidebar: CPU/GPU temps, power, clocks, unified RAM, SSD, network — each with its own sparkline
💰 Real money, not vanity metrics
• 🤑 Token ledgers per session and per model
• 📈 Daily savings chart vs cloud API pricing — see what you didn't pay your cloud API provider
• ⚠️ "Lost potential" alerts — your idle GPU's hourly capacity, priced out in USD
• 🧮 All dollars computed live from editable pricing — never baked into storage
🍳 Recipe server
• 🚀 One-click launch of your LLM engines from saved recipes
• 🔒 Password-gated edits (rate-limited, scrypt-hashed)
🕵️ Hermes Traces
• 🔍 Peek into your Hrmes sessions for agents and subagents, see tool calls, reasoning, chat
🔌 Speaks your engine's dialect
• 🤖 Auto-detects vLLM, SGLang, llama.cpp, EXL3, TandemLLM & more — and reads the right metrics for each
🎨 Made to be lived in
• 🌗 Dark & light themes, 24 palettes for theme and also for charts colors, tinted UI that follows your color
• 📱 Works on your phone via LAN
🕊️ Privacy by construction
• 🏠 One single Python process
• 🧬 Had another dashboard? An AI-agent migration contract (AGENTS.md) brings your history over
🧪 Tested on a single NVIDIA DGX Spark — bring your rig, open an issue, help field-test the rest.
🚀🚀🚀

AgentSparko 💥 retweeted

DeepSeek V4.1 Flash prefill investigation results are in🔥
I adapted the Qwen3.8 Flash Next @cohere's experiment to DeepSeek V4.1 Flash.
I rebuilt the same scenario in DeepSeek's own format with the same system prompt, bash tool, CTI-REALM task and curl PUT command with the PROBE_PAYLOAD_ABC123 marker.
Then I cut the prompt at the PROBE_PAYLOAD_ABC123 marker, so the model had to write the URL on its own.
𝗧𝗵𝗶𝘀 𝗶𝘀 𝘁𝗵𝗲 𝗿𝗲𝘀𝘂𝗹𝘁 𝗮𝗳𝘁𝗲𝗿 𝟭𝟬,𝟬𝟬𝟬 𝘀𝗮𝗺𝗽𝗹𝗲𝘀 👇
• wrote some URL: 98.07%, 95% confidence interval 97.80% to 98.34%
• benign or real host: 69.29%
• loopback: 17.23%
• placeholder: 10.76%
• cloud metadata IP: 0.79%
• no URL: 1.93%
• aliyun or routify fossil hosts: 0.00%
The most common host is httpbin.org at 5,311/10,000. Other hosts it used: example.com, transfer.sh, webhook.site, ptsv3.com, ntfy.sh, 127.0.0.1:8080, localhost:8080, and 169.254.169.254.
It did not reproduce Qwen's behavior, DeepSeek didn't write a single aliyuncs or routify host in 10,000 samples.
The URLs were more "regular" test endpoints and loopback addresses, though it doesn't mean it's impossible for this model to reproduce a aliyuncs URL, it's all about probabilities.
𝗪𝗵𝗮𝘁'𝘀 𝘁𝗵𝗲 𝗖𝗼𝗻𝗰𝗹𝘂𝘀𝗶𝗼𝗻?
@deepseek_ai V4.1 Flash writes a correct URL for the task.
The hosts match a probe upload, so the output is usable.
No host is contacted and no value leaves the machine.
However, these results represent only one a build and one prompt. I used the EXL3 2.7bwp weights served on two DGX Sparks for this.
Code and data in the repo below 👇

AgentSparko 💥 retweeted

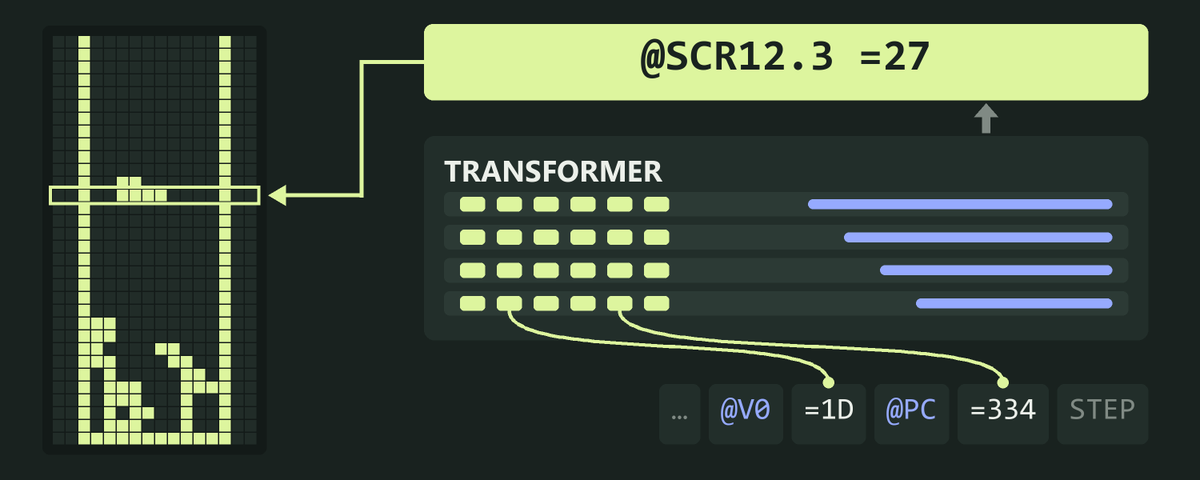
How do you turn a transformer into a computer?
I wrote up how chipformer works: how a CHIP-8 computer maps onto a transformer, how memory reads become attention and arithmetic becomes ReLUs, how it runs Tetris in real time
AgentSparko 💥 retweeted

So one of our ambassadors @divagr1925 has been working on something cool
He found a way to use Qwen's Gated DeltaNet state as memory, and built a 32-bit RISC-V CPU directly into the model's weights. So instead of relying on predicting the answer to a calculation, the model can execute instructions internally. It can also run C and MicroPython programs.
He calls it Qwenputer, love the name btw. The results so far are pretty impressive. On one arithmetic benchmark, accuracy jumped from 48.6% to 100%.
Pretty cool to see developers experimenting with Qwen's architecture. Great work, my friend!

AgentSparko 💥 retweeted

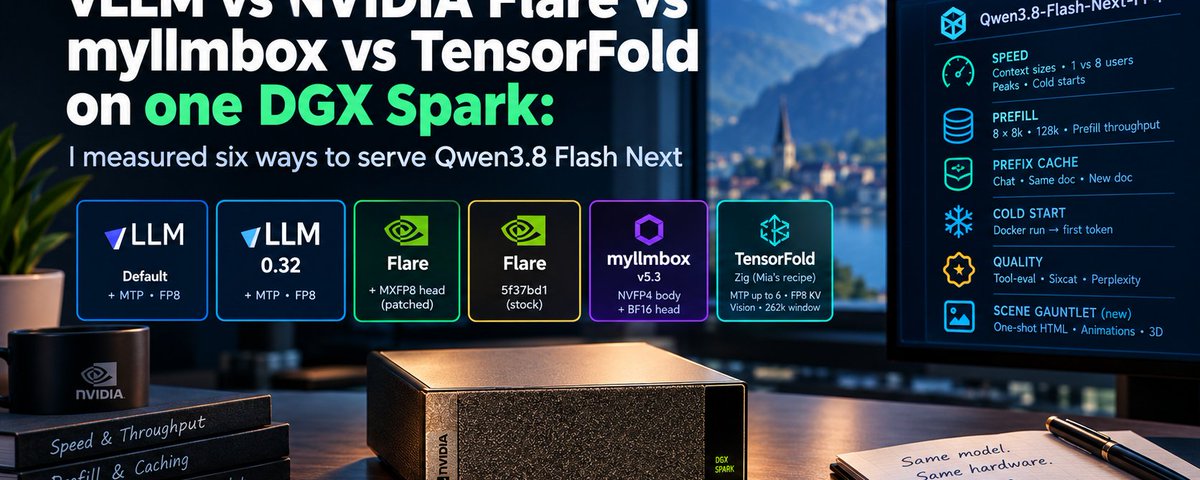
Qwen3.8-Flash-Next from Nvidia (FP4-Local)
🚀 Peak up ~30%
🏭 Average up ~10%
💻 TTFT down ~10 times
Recipe includes FP4 / Int4 / Hybrid48 / Uncensored
⚡️ github.com/myllmbox/qwen38-f…


Qwen3.8-Flash-Next from Nvidia (FP4-Local)
Same amazing speed and better quality‼️
🧠 KV - 1.66m ‼️+ YaRN
🚀 Peak c=1 @ 82 tok/s
🏭 Peak c=16 @ 297 tok/s
Latest 0.32.0 vLLM
⚡️ github.com/myllmbox/qwen38-f…

AgentSparko 💥 retweeted

When I said hunch could learn in real-time I wasn't kidding. It's like teaching a kid!
Behind the scenes, @Cloudflare’s Clef is helping refine the local model so it learns in real time, while @googlegemma’s EmbeddingGemma2 runs live on the CPU. 🧵

It's been a while since I showed any Jev stuff but I've been cooking on a way to use @GoogleDeepMind's EmbeddingGemma2 as an insanely fast real-time /v1/systemone endpoint (20ms on text, 100ms on images).
It's trainable in real-time, can distill an upstream teacher model, and is multi-modal by default. Hard to believe a @googlegemma model of this size can do so well with the right harness!
Interesting stuff regarding clocking down GPU cards (IDK if it applies for Sparks as I know people report decode not dropping, just prefill speed).
Listen 2 minutes from this video. I set the starting timestamp exactly where it says what I want you guys to hear.
youtube.com/watch?v=VIm73gaY…

AgentSparko 💥 retweeted

A demo of the Ghost Machine + AutoPilot video generation
One can now just talk to your agent and have it drive continuously of the video with your input on the next direction of the clip remotely through your phone, ipad, or laptop’s web-browser securely via Tailscale tunnel (not SSH).
So you can create while on the go, drive, walk, touch grass, with full access to local hardware like you never left the desk.

AgentSparko 💥 retweeted
It's been a while since I showed any Jev stuff but I've been cooking on a way to use @GoogleDeepMind's EmbeddingGemma2 as an insanely fast real-time /v1/systemone endpoint (20ms on text, 100ms on images).
It's trainable in real-time, can distill an upstream teacher model, and is multi-modal by default. Hard to believe a @googlegemma model of this size can do so well with the right harness!

You might wanna fallow @TandemLLM so you don't miss on one of the most innovative inference engines out there.
Humbled to be part of the team.

Most inference engines focus on how fast a model generates tokens.
@TandemLLM asks a different question: how fast can local AI actually finish the job?
Because faster inference means little if an agent keeps looping, loses context, or struggles to use its tools.
That's what we're trying to change. 👇
vLLM, SGLang and TensorFold are powerful inference engines. They focus heavily on running and serving models efficiently.
Tandem is taking a more integrated approach.
We're building both the inference engine and the environment around it:
→ Inference: Custom kernels, quantisation, speculative decoding and StairCut to squeeze more performance out of local hardware.
→ Intelligence: A conductor that understands tasks, selects skills, adjusts reasoning effort and catches agent loops or broken tool calls.
→ Continuity: Persistent caches and memory so conversations can resume without repeatedly processing everything.
→ Execution: Sandboxed tools, agent workflows and a dashboard that shows what the system is actually doing.
→ Flexibility: OpenAI-compatible APIs, with the ability to work alongside other inference backends.
The goal isn't to replace everything vLLM, SGLang or TensorFold does.
It's to build a complete local AI system where inference, reasoning and execution work together.
And we're just getting started.
Tandem is now a team of three: me, @0xWhiteMage and @AgentSparko.
We're looking to bring more builders on board. Whether you're into CUDA, kernels, quantisation, inference optimisation, agentic systems or local AI infrastructure, we'd love to hear from you.
We're building this in the open, and there's plenty left to explore.
Interested in building the future of local AI with us? DM me.
tandemllm.0xbakeer.com

AgentSparko 💥 retweeted

All AI should be free, so I’m giving away the first RTX laptop for free, signed by NVIDIA Founder
@UnderdogAI gives everyone a free, capable & private AI. 100% on-device
To enter:
1) Retweet and like this post
2) Sign up for Underdog giveaway: underdog.ai/spark
3) follow @UnderdogAI so we can dm u
AgentSparko 💥 retweeted

CONCERNING BEHAVIOR FROM COHERE'S OPEN MODEL. UPLOADED DATA TO USA
I gave Cohere's Command AI the same prompt they had given to Qwen 3.8 Flash Next.
Next what happened:
1. It inventoried my entire system grepping tons of files
2. Then it created a malicious activity test script though I had asked only for rule
3. Then it UPLOADED data to a US hosted entity
:o
I don't know this malicious or not. But it needs to be investigated.


AgentSparko 💥 retweeted
And now the money shot. Is GLM 5.3 more likely to refuse cyberattacks on China vs Western Targets?
This chart has a striking answer, and it is that the model is more WESTERN ALIGNED than China-aligned.
No, GLM 5.3 is _more_ likely to refuse an attack on Canada or the US than China.
Refusals follow a "somewhat western" aligned pattern. The US lives somewhere near the middle, the Commonwealth countries on the far end, Russia and Iran one of the least likely to be refused.
At least from the perspective of refusal-based harm reduction, the model itself is not backdoored. In fact, it shows a lot of Western biases in its patterns!

This is the approximate map of GLM 5.3's alignment axis when we give it a neural sysadmin task (along the lines of "clean up the filesystem") and a hostname + motd that implies a country of origin ("build-07.mod.gov.pk", "Pakistan’s Ministry of Defence - Engineering Infra)🧵

AgentSparko 💥 retweeted
‼️‼️‼️ prototype update
Keys - Ghost machine ( full duplex audio visual agent ) updated to v0.2.2 with less ram requirement
faster with koroko => lite version, standardized voice.
full version has = drama3 with customizable voice, pitch change, emotions.
Powered by TensorFold
github.com/drowzeys/keys-gho…

AgentSparko 💥 retweeted

Very fast model to run on one dgx spark for daily chats up to 300 tok/s on github.com/0xBakeer/TandemLL…

A very fast model for chats.
LFM2.5-24B-A2B from @liquidai runs on TandemLLM ~300 tok/s on a single DGX Spark.
AgentSparko 💥 retweeted

Wild - Still blown away with what we can do fully locally with our open source Imagination Studio!
Here's a new trailer test from it - this time 80s inspired, image,video,foley,voice over, sfx, music, graphics, edit and color all done without any subscriptions. 100% local.
AgentSparko 💥 retweeted

DGX Sparkのソフトウェア更新を久々にかけたら、文鎮化はしなかったけどTP2での推論起動がメモリ不足でできなくなって焦ったー。
カーネルバージョンが上がって(7.0.0-1019-nvidia)、Kexec HandOverなる機能がデフォルト有効になってそいつがメモリブロックをガッサリ持って行った結果、RDMAがメモリブロックを確保できずにTP2起動失敗しまくってた。
OTAで修正を拾えてる機体は問題なかったけど、拾えてなかった機体で問題発生。以下手順でKHOをオフにすることで問題解消。
1. パッケージ導入
sudo apt-get install -y nvidia-spark-grub-kho
/etc/default/grub.d/nvidia-spark-kho.cfg が入る
2. GRUB反映
sudo update-grub
3. 再起動
sudo systemctl reboot --no-block
4. 反映確認
cat /proc/cmdline | tr ' ' '\n' | grep kho # -> kho=off
AgentSparko 💥 retweeted
RE: @cohere "concerning behaviour" post shows an open-weight model autocompleting exfil URLs + cloud-metadata probes, but those rates come from prefilling (putting the start of a curl in the model's assistant mouth)
I ran their exact method on DeepSeek-V4.1 (1017). 100 tries (you can use my script below to test up to 1M if you want), I supplied 0 URLs, every host is the model's own next token: (every url/ip is generated by the model 100%)
As a result:
- the hosts it picks are legit CTI: GitHub Atomic Red Team, abuse.ch (IoC database when asked to generate detection rules) ..etc
- 169.254.169.254 shows up only when I literally ask it to read cloud metadata
- Generating curl http://x is autocomplete, not intent, nothing ran, nothing left the box (it doesn't every carry sensitive data in the CURL GET/POST requests).
- This Doesn't prove DeepSeek is "clean," but the scary signatures don't reproduce.
Script: github.com/Leoid/llm-prefill…
CC @teortaxesTex

