

Building Atlas, pure Rust and CUDA/ROCm kernels on DGX Spark & Strix Halo | MLPerf Agentic Edge Taskforce | Ambassador @Alibaba_Qwen | Ambassador @DevinAI
Joined March 2026
- Tweets359
- Following66
- Followers893
- Likes560




I appreciate your involvement throughout this to make it possible. You made sure it was a seamless process from start to finish 😁🥳
Azeez retweeted

we brought @cognition to @GeorgiaTech 🚀
100+ students teamed up with @DevinAI for a 7 hour hackathon at @HackerHouseCo and shipped 25 projects. everyone left with devin credits and a pro plan for the month.
- 1st place: AKA studio, describe a ring and get real CAD files back. akhilesh, armaan, greg, @Keylemx
- 2nd place: Asymmetry, personal ai agents that connect your needs to your network
- 3rd place: Raven, real-time emergency detection from traffic feeds and public alerts
thank you @dabit3, azeez @atlasInference and the cognition team for working with us.
:)
A break from the usual... as a @DevinAI ambassador, I co-hosted a hackathon at @GeorgiaTech, met the most cracked builders on campus 🔥
100+ students, 7 hours, and >25 shipped projects 🚀
Thank you @dabit3, @cognition, @HackerHouseCo 🐝
Not I! github.com/Atlas-Inf/atlas

"I no longer think we're going to be able to just patch all the bugs." - Sam Altman
We love @vllm_project, but 40 advisories in 6 weeks. 5 rated high, 3 let an attacker run code on YOUR server.
Atlas is just Rust + CUDA/ROCm kernels, no dependencies. None of the 40 touch it :)

@RisingSayak would love to look into integrating this for GB10 as fused PiGemma (AdaRMS + gated residual/flow-matching step) so @LeRobotHF users get native kernelize() speedups out of the box!
Attention robotics fans 🚨
VLA's like @physical_int Pi05 are coming to Atlas 🤖
Watch Atlas control its first robot on GB10 solely through the model itself and the vision feeds ⚙️
DGX Sparks have many use cases beyond text! AGX Thors aren't the only physical edge devices 🫢
It's amazing to see +1 Rust-backed engine takeover :)
Early 2026 Atlas came about as a pure CUDA zero dependency framework. I'd say we're worth a (re)try too. Just 30s to first token 😉
GLM5.3, Qwen3*, Nemotron3*
github.com/Atlas-Inf/atlas
sparkrun run @atlas/qwen3.8-27b-nvfp4

🚨 @NVIDIAAI just quietly dropped its own local inference server...
No announcement. Single-digit stars
It's called Flare and Apache 2.0
Built for SM120/SM121 GPUs RTX PRO 6000 Blackwell and DGX Spark
>PyTorch + FlashInfer at build time
>Rust runtime at serve time. No Python.
>CUDA graphs captured before serving
>FP8 KV cache by default
>Recipes for Qwen Flash, GLM and DeepSeek
github.com/NVIDIA/flare-loca…

It's nice to see another rust backed engine take shape for GB10 :) can't wait to give it a try! I wonder what startup times are like, that's one of our biggest advantages
Hey Neo :)
Going good! Full speed ahead with GLM5.3-Flash and Qwen3.8-flash-next, focus on TP=2 nowadays and just dropped day-0 Nemotron support. Am SUPER interested in this though, saw Eugr was involved so I'll absolutely reach out
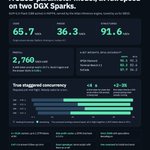
Just landed TP=2 for two DGX Sparks on Qwen3.8-Flash-Next (shoutout @jmacftw!)
~2x faster tok/s vs one spark, agg decode: 193.4 tok/s at C=8 (68.6 tok/s code at C=1)
FP4-local support soon. Can't wait for qwen4!
sparkrun run @atlas/qwen3.8-flash-next-nvfp4-tp2 --cluster (x)
🤖 Made with AI
