Creative Tech at @plexiz. I do creative things, then post what worked
Joined October 2011
- Tweets112
- Following541
- Followers1.1K
- Likes994


Pinned Tweet
For my first post, I want to show one of our videos, and how we made it. It's a little rough. We've gotten better since, but this one holds a special place: it was the first one we made for a client.
It's an 18-second World Cup spot we made at @plexiz for El Poder de la Nuez, the American Pecan Promotion Board's campaign in Mexico. The star is Pepecano, a squirrel our team designed as the campaign's new character.
The idea: Pepecano is watching the game with a giant bowl of pecans. Goal. He jumps, the bowl flips and every pecan goes flying. Slow motion, pure panic, then squirrel super-speed to save them all. This was right in the middle of the World Cup madness in Mexico. It was awesome.
Tools used:
• Seedance 2.0 in Higgsfield for every shot. In the final version, each prompt carried three reference images (the living room, the exact pecan and the character) plus a beat-by-beat timeline down to half a second.
• ElevenLabs to test voices. The final voice is the campaign's real spokesperson.
• Frame.io for review notes.
• A traditional edit for the cut, the sound and the animated end card.
Things we had to overcome:
• World Cup IP rules. The match on the TV is invented and blurred: no logos, no scoreboard, no real teams. No famous commentator either, just the crowd roar.
• Scale. Seedance 2.0 struggles with object size. After a whole night of digging, the only tip I found was to feed it a size comparison photo.
• Round 1 of client feedback: the pecans looked too dark, the one in his hand looked like a coffee bean, his back stripe was the wrong color and the jersey on the TV couldn't look like any real team's. Color and scale were baked into every clip, so we got the pecan color and size approved first and regenerated the whole spot from zero.
• Round 2: the client caught Pepecano picking pecans up off the floor. They wanted every one caught mid-air. The prompt got one hard rule: pecans never touch the floor or the couch. It took me 10+ generations, and the fixed cut was ready about an hour after the note.
Lesson: lock the character and product references with the client before you generate anything.
24 days from first draft to approval. It went live that same day on YouTube, Instagram and TikTok.
Pablo retweeted

Today we’re open-sourcing Inworld's Voice Isolator and SAVA (Semantic-Acoustic Voice Activity) models, and publishing the technical report behind Realtime TTS-2.
1/ Voice Isolator: preserve the speaker’s voice.
It removes background chatter, music, and noise while retaining the laughs, breaths, and character of the original recording. It works at 48 kHz, with an offline model for recordings and a realtime model that streams with 20 ms of lookahead.
2/ SAVA: give people room to finish their thought.
Our Semantic-Acoustic Voice Activity model uses both the sound and meaning of speech to detect when someone is speaking and when their turn is complete. It already runs in our voice products and fits on a single laptop CPU thread. In our tests on real meeting recordings, it detected completed turns in a median of 71 ms, compared with 210 ms for the open-source model we tested against.
3/ TTS-2 technical report: share how we built the voice on the other end.
We explain how we trained TTS-2 to follow instructions about delivery, use the same reference voice across languages, and generate streaming speech. We also cover the work behind Flash’s faster, more efficient serving, with training methods, evaluation results, and lessons from failures during development.
Voice Isolator and SAVA include code and model weights under Apache 2.0.
Explore the releases and try them on your own audio here: inworld.ai/open-source
Pablo retweeted

Canvas gives you the freedom of exploration. When we talk about control, we first think about pixel level of correctness but we should also talk about the visibility of thoughts, choices and iterations.

Pablo retweeted

ICYMI: LongCat-Video-Avatar-1.6 just landed on @huggingface 🔥
upgrades vs v1.5:
> more natural lip animation & improved audio synchronization
> better for long video generation
> new optimizations for faster inference
took it for a spin with portraits from a funky Krea 2 LoRA by @akatz_ai + audio by Drama 3
weights: huggingface.co/meituan-longc…
space: huggingface.co/spaces/victor…
Pablo retweeted

i built a 100-foot walking robot in Blender, entirely from code, using AnyMachine:
github.com/apekshik/anymachi…
anymachine starts from a single reference image. from that it generates more references: frontal, side, top, three-quarter, then a close-up of every joint.
Fable 5.2 then takes those and builds it out completely, not as one mesh but as individual parts. for my stilt walker that was 160 unique parts, a fully working hydraulics, a full rig and a walk cycle.
the real work was the pipeline: references good enough to model from, and checking every part against them. the whole method is in the repo.
point your agent at the repo and it can build out any machine far more reliably. i’ve seen it generalize really well to other machines!
Pablo retweeted

Just pushed an update to my skills repo.
All 19 skills have been improved with a total of 185 changes across them.
Rerun the install command to update.
aiforui.dev/skills

Pablo retweeted

can you tell which one is real?
84% couldn't
introducing Avatar 6, #1 on New Measure's Avatar Arena
what's new:
realism - passes for the real you
context-aware gestures - matches what your script means
reference - up to 30 secs of video + a photo
try it now ↓

Pablo retweeted

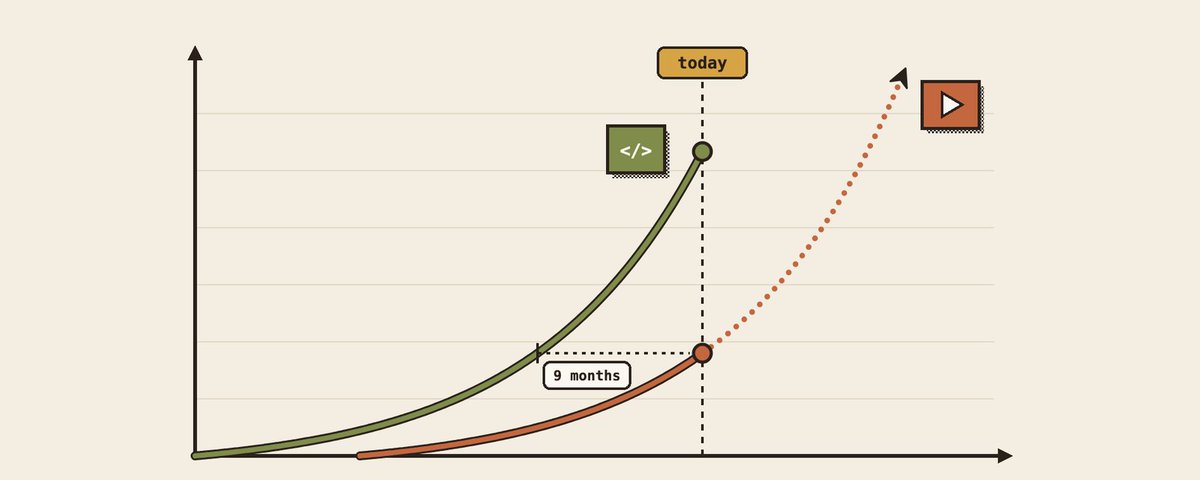
every. single. marketing. department. will. be. flipped. upside. down.



Pablo retweeted
1/ announcing our smallest, most efficient little model is here: muse ember 🔥
built for work that agents repeat all day, it gets you more intelligence per dollar than Haiku, Luna, and all other flash models at any reasoning setting and does it at a third of the cost or less!

Pablo retweeted
i think we've reached the point where the cracked marketer is more in demand than the cracked engineer
Pablo retweeted

we need a collection of God tier prompts like this
not skills I DON'T CARE ABOUT YOUR SKILLS
i want a single sentence of vectors so juicy each verb, noun, and adjective act like flavorful curry bombs BURSTING with information that a simple prompt ends up being VERY impactful

Pablo retweeted

Im tired of infinite canvas startups.
Im tired of generative video snake oil providers.
Im tired of hype for hyperframes, as html and playwright is a dumb long term solution for video rendering.
So I decided to build Raea. Open source. Free for everyone.
Faster and more capable than hyperframes or remotion. (10-20x faster with real footage and complex scenes).
And it renders without a browser….
Capable of more than just video. It’s built on @BevyEngine so it’s highly capable at producing 3D art, shaders and games.
It’s also built on Blitz Dom @dioxuslabs , and a bridge between the page and the 3d world behind it allows you and your agent to write everything in typescript and react… without a browser.
This video below was made entirely with Claude, Raea, and a weekend. I never had more fun playing and toying with creative work than I did making this.
But to be honest, that’s not where I’m stopping. I want Raea to be an engine that correctly empowers creatives and agents, while not cognitively offloading the parts that make your work unique.
I’m excited to continue working on this project as long as I can, and always open to feedback!

Pablo retweeted

🤯 AI 视频换人,已经不只是换一张脸了!现在连发型、服装、动作和背景都能在本地修改。
这个开源项目 OpenJutsu,基于 MiniMax H3 + SAM 3.1 + Qwen3-VL,把视频人物替换和局部重绘整合成了一套工具。
最值得关注的是 4 个能力:
🎭 1. 整个人物替换
上传一段视频和一张角色照片,把视频主角替换成新角色。
不只是换脸,还包括发型、身材和服装。新角色跟随原视频动作,原来的运镜、剪辑和音轨保留。
👥 2. 最多 4 人同时替换
Advanced Motion Transfer 支持最多 4 个角色。
可以给每个人设置角色名称,系统通过 SAM 3.1 追踪人物,再用 Qwen 判断身份和匹配关系。
适合乐队 MV、多人对话和群像视频。
🧥 3. 视频局部修改
Object Swap 支持四种操作:
• Change:换衣服、头发、汽车等物体。
• Remove:移除指定物体。
• Background:人物不动,只替换背景。
• Add:在指定位置添加新物体,还能用关键帧控制位置。
🎬 4. 从图片生成新造型 + 后期修复
From Picture 可以把角色照片放进原视频的动作和姿势中,再生成新视频。
还支持 17 种 Relight 灯光风格,以及 Fix Faces 人脸修复、Fix Colours 画面调色。
适合谁用?
使用 ComfyUI + MiniMax H3 制作人物替换、AI MV、角色短片、服装展示和视频局部编辑的创作者。
🔗 GitHub:
github.com/D3voz/openjutsu
⚠️ 两个真实踩坑:
作者实测配置为 RTX 4060 Ti 16GB + 64GB 系统内存。6 秒 480p 视频约需 6–13 分钟;1080p 比 736p 慢约 2.5 倍。
镜子、玻璃等反射场景目前还不可靠,倒影可能保留原人物外观。另外需要 ComfyUI 及多个配套节点,不能只下载一个程序就直接生成。
#OpenJutsu #ComfyUI #MiniMaxH3 #AI视频 #视频换人

Pablo retweeted

Today, we open-source P-H3-Image, an image generation and editing model built from MiniMax-H3 by @MiniMax_AI. A SOTA video model, turned into an efficient open image model.
- 𝗛𝗼𝘄 𝗲𝗳𝗳𝗶𝗰𝗶𝗲𝗻𝘁 𝗶𝘀 𝗶𝘁? Generate or edit images 5× faster, in 8 steps instead of 50. A 4 MP image takes 2.6 s instead of 12.4 s. The model is 7× smaller than H3, so high-resolution images are a light download and run on a much smaller GPU.
- 𝗛𝗼𝘄 𝗴𝗼𝗼𝗱 𝗶𝘀 𝗶𝘁? Strongest at photorealism, documentary and editorial photography, film stills, and graphic styles with short quoted text. It renders 2 to 16 MP and edits with up to 8 input images.
-𝗛𝗼𝘄 𝗱𝗼𝗲𝘀 𝗶𝘁 𝘄𝗼𝗿𝗸? We reworked every component of H3: the prompt upsampler, the text encoder, the diffusion schedule, the transformer, and the decoder. Use it with Diffusers or ComfyUI.
📄 Tech Report: pruna.ai/blog/oss-p-h3-image…
🤗 @huggingface Open Weights: huggingface.co/PrunaAI/P-H3-…
👉 @ComfyUI Native Support: huggingface.co/PrunaAI/P-H3-…
Cloning your voice is easier than you think.
I recorded just over a minute of my voice. That's it.
In ElevenLabs I used Instant Voice Clone: upload the audio, confirm it's your voice, save.
Two catches: more than 2-3 minutes of audio barely helps, and the free plan can't clone. Starter can.
The video is in Spanish. The voice you hear is my clone.
What would you do with yours?
🤖 Made with AI
1
75
I didn't film this video. My avatar did.
My face, my voice, my studio. Not a single take.
How I made it:
- Higgsfield + GPT Image 2.5 Sunburst for the look, 4 versions per prompt
- ElevenLabs v4 with my cloned voice
- HeyGen Avatar V to animate it
The hard part was the face. Early versions changed it or gave me a tiny head on a huge body.
Comment AVATAR and I'll send you the exact prompt.
🤖 Made with AI
Pablo retweeted

This fitness coach doesn't exist
29 seconds. 3 moves. 8M views...
One Picsart CLI for all the generation + one GitHub repo (HyperFrames) for the edit. Claude Code drove both.
here's the whole sequence:
Day 0: Lock the character. Grey tee, dark joggers, lime wristbands. GPT-Image-2 for the concept, Nano Banana Pro for the character sheet. Same face in every shot after that.
Day 1: Make the moves. Nano Banana Pro draws a keyframe per exercise, Kling v3 animates it. Squats, push-ups, plank. ~2 min per clip.
Day 2: Make him talk. Eleven v3 for the voice, OmniHuman 1.5 for the lip-sync (~3–4 min per clip), Lyria for the music.
Day 3: Hand it all to Claude Code. It writes the edit as code (HTML + GSAP): kinetic captions, step cards, form cues, a progress bar, the muscle map. HyperFrames, HeyGen's open-source video engine (~53k stars), renders it to MP4 in ~2 min.
The next 30 days: same coach, same outfit, new moves. Nothing to sell yet. You're building a face people recognize – that's what you sell later.
Then every scene becomes an ad slot. He can wear it, hold it, drink it:
Jump rope → sneakers
Locker-room water break → bottles, electrolytes
Tying laces on the street → running shoes
Breakfast → protein
Boxing bag → gyms
Rooftop meditation → fitness apps
His outfit → sportswear
The CLI makes the coach. Claude Code writes the edit. HyperFrames renders it. You sell the slot.
Week 1: character + 3 routines
Week 2: post daily, test hooks
Week 3: keep what holds attention, cut the rest
Week 4: your best clips on one page = your media kit
Month 2: pitch sportswear, protein, gyms, fitness apps
Month 3: same system, second coach
Cost: ~235 Picsart credits all-in, rejected takes included. HyperFrames: open-source (Apache-2.0). Claude Code: your own subscription.
save this and read the article below: