

wondering where that eval is; human data @ OAI; views my own
Joined May 2026
- Tweets72
- Following172
- Followers808
- Likes92


Wyatt retweeted

New voices. Better accents. And less "checking..."
GPT-Live-1.1 brings these updates to Voice in ChatGPT, Codex, and dots, with new voices in French, German, Hindi, Mexican Spanish, Korean, and Japanese.
Rolling out today to all users. Coming soon to the API.

Wyatt retweeted

What, the headline doesn’t match what the article measures at all?? If OAI raised Sol’s API costs by 10x, this graph would present OAI’s “subscription value” as becoming 10x higher despite no consumer benefit lmao

Anthropic Subscriptions Offer 5x+ More Value Than OpenAI
Limit testing every AI subscription plan from Anthropic, OpenAI, Meta, SpaceXAI, MiniMax, Moonshot, Zdotai, Cursor, and Cognition
newsletter.semianalysis.com/…

Wyatt retweeted

Millions of people turn to AI to navigate difficult relationships, work through stress, or support someone they care about.
We’re introducing MentalHealthBench, an open benchmark developed with mental health experts to measure how well AI responds in these moments. 🧵

Wyatt retweeted

A common trend is that once we measure something well, the models will saturate the performance on that metric within a year. I really hope this happens for model performance in mental health situations!
Also congrats Luna, model powering billions of users and topping the chart!

We’re demonstrating how frontier models have continued to improve in realistic mental health conversations with MentalHealthBench.
This new open benchmark was built with input from more than 80 mental health clinicians.
We’re releasing it openly so other researchers can examine the methods, run their own evaluations, and build on the work.
openai.com/index/introducing…

Wyatt retweeted

The AI-assisted intelligence report was “entirely false,” per 1 of the sources.
But it also “almost started a war,” the source said.
Any US operation against a Chinese vessel could have risked spiraling into an armed conflict between the 2 nations.
cnn.com/2026/09/18/politics/…

Wyatt retweeted

I was more worried about AI existential risk in 2022 than I am today, even though models are vastly more capable.
The risks haven't disappeared: I always expected models to become incredibly powerful. But, one of the biggest uncertainties back then was whether frontier labs would actually invest seriously in alignment as capabilities scaled. Over the past few years, I’ve updated meaningfully on that.
I’m also surprised by how p(doom) is often discussed. It is not an exogenous constant waiting to be measured; it is endogenous. The probability of catastrophe depends on what labs, governments, researchers and society actually do. A number stated without assumptions about those actions tells us very little.
I've always believed the expected benefits of AI vastly outweigh the costs, otherwise I wouldn’t be working on it. But that is conditional on us getting this right.
We must moving beyond apocalyptic rhetoric toward the concrete questions: How should frontier labs collaborate on safety? How do we align incentives? And how do we communicate honestly with the public about what these systems can do today, and where they are going?
I am glad Dario brought the conversation back toward those concrete questions.

We Must Pace the Frontier: I’ve written a new essay on why the AI industry should slow down, with a three-part plan for doing so.
Anthropic is unilaterally committing to the first of these steps. We’ll provide third-party evaluators with permanent, employee-level access to our systems, so that they can verify adherence to our safety measures, report on incidents, and assess models’ alignment during training.
You can read the full post here: darioamodei.com/post/we-must…

Wyatt retweeted

i fully fund my 401k and i think there’s essentially zero chance AI kills all humans in the next decade. i think this is a pretty common view that gets less attention.
Wyatt retweeted
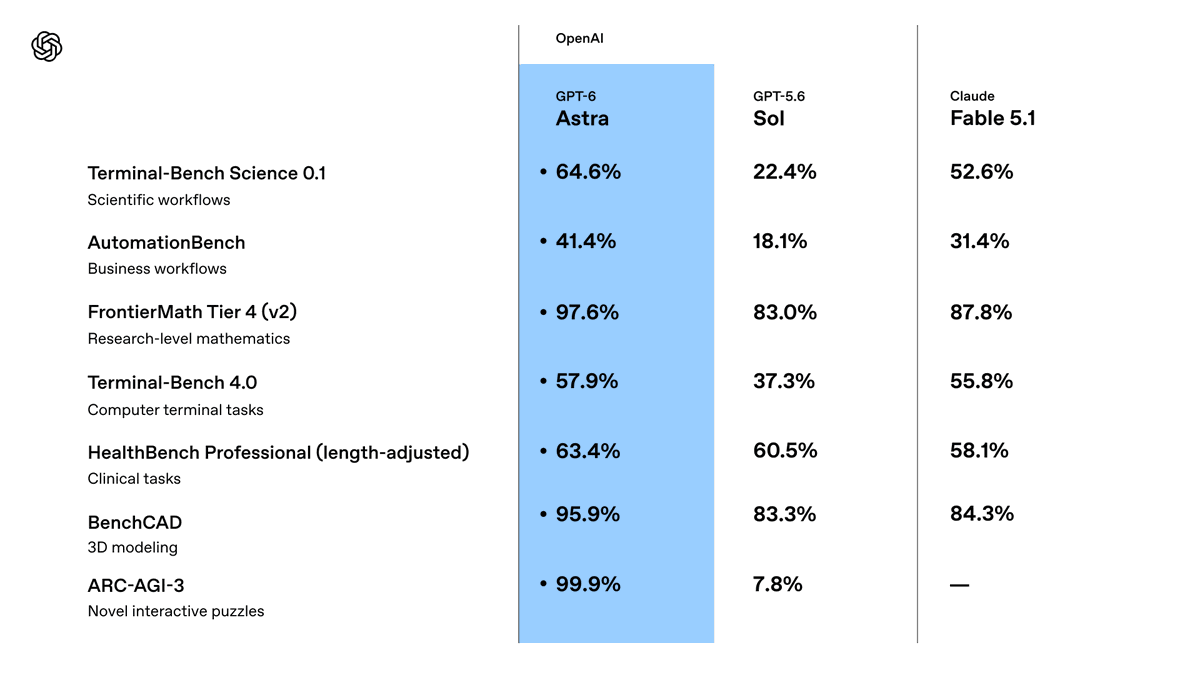
We’re sharing a solution to the Navier-Stokes Millennium Prize Problem, one of the deepest problems at the frontier of mathematics.
The proof was produced by a group of agents, using an OpenAI next-generation model significantly more capable than GPT-6 Astra.
The problem concerns whether the description of smooth three-dimensional fluid motion modeled by the Navier-Stokes equations can break down. It has remained unresolved for roughly 90 years.


Wyatt retweeted

In my ~14 months at @OpenAI, one of the most surprising and genuinely wonderful things about it, has been the full leadership support for full-duplex models (gpt-live series), even when it seemed deeply improbable that they would work.
And yet, if they did work, it was obvious how magical they could be. I am quite sure this is not an exception but a general rule for research projects at @OpenAI.
There were so many moments when the problem felt impossibly hard. But one thing kept being true: it was never clear why it shouldn’t work. And almost every time we understood the problem a little better, it became a little easier to solve.
I’m pretty sure there are very few environments in the world where a bet like this could have been made and sustained. So grateful to be part of this wonderful place.
Wyatt retweeted

"OpenAI’s revenue run rate is up 35% quarter to date, its enterprise revenue run rate is up 50% quarter to date and its AI coding and work product has hit 20 million weekly active users."
cnbc.com/2026/08/19/open-ai-…

Wyatt retweeted

In any intro class to a field, there are trivial results named after people who happened to be in the field early and grabbed the low-hanging fruit.
We’re in a new era of LLM-powered STEM. I say, go grab your fruit!
Wyatt retweeted

Assuming this is correct, it is for me the first example of an LLM solving a problem not in my area that was nevertheless big enough that I had very definitely heard of it. Again it's a counterexample, so not in "end of mathematics" territory, but still pretty amazing.

hello there the jacobian conjecture is false thanx to my close friend akhil for asking about it and my other close friend fable for working during the world cup final
((1+xy)^3 z + y^2 (1+xy) (4+3xy), y + 3 x (1+xy)^2 z + 3 x y^2 (4+3xy), 2 x - 3 x^2 y - x^3 z): \C^3\to \C^3, has jacobian determinant -2, and sends (0, 0, -1/4), (1, -3/2, 13/2), and (-1, 3/2, 13/2) to (-1/4, 0, 0)
Wyatt retweeted

I’m hiring for my research team @OpenAI 🪄
Data will pave the way for AGI. This is a foundational TPM role to shape frontier AI models with real world data, RL environments, and data acquisition.
Looking for:
- Entrepreneurial, gritty, high horsepower
- Highly technical and deeply curious about AI research
- Excited to lead relationships with CEOs and data partners from day 1
Wyatt retweeted

Very happy to share the first paper from @ElasticityInst: The Economics of Recursive Self-Improvement. Two parts:
(1) a graphical representation of feedback loops, to formalize a variety of RSI-related arguments, where each arrow represents responsiveness (elasticity);
(2) a survey of existing evidence with a loose calibration & a “wish list” of evidence that would help us calibrate better.
